Inference Gateway CLI
The Inference Gateway CLI (infer) is a powerful Go-based command-line tool providing comprehensive access to the Inference Gateway with interactive chat, autonomous agents, Computer Use tools, and development workflows.
Versioning: the CLI is pre-1.0 and breaking changes are expected until it stabilises. The commands on this page install
@latest, so there is no version number to keep in sync here - see the releases page for whatlatestcurrently resolves to.
Key Features
- Zero-Configuration Setup - Add API keys and start chatting
- Autonomous Agent Mode - Delegate complex tasks with iterative execution
- Computer Use Tools - GUI automation with screenshot, mouse, and keyboard control
- Screen Recording - Record the screen, a window, or a region to MP4 from chat (Learn more)
- Rich Tool Integration - File operations, code search, web access, GitHub via the
ghCLI - Smart Safety System - Configurable approval workflow with diff visualization
- Beautiful TUI - Scrollable interface with syntax highlighting and multiple themes
- Web Terminal - Browser-based interface with tabbed sessions
- Remote Messaging Channels - Control the agent from Telegram and other platforms (Learn more)
- Agent Skills - Reusable, model-readable instruction folders loaded on demand, portable across vendors (Learn more)
- Custom Tools - Add tools written in any language with one YAML manifest per tool (Learn more)
- Plugins - Claude Code-format skill bundles plus an always-on ruleset, managed with
infer plugins - Frame Sources and Vision Annotation - Let text-only models read screen and camera frames (Learn more)
- Cost Tracking - Real-time token usage and cost calculation (Learn more)
Installation
The CLI repository's Installation guide is the canonical reference for every install channel; this section mirrors it.
npm / npx (Recommended)
Run the CLI without installing anything (requires Node.js >= 18). The matching native binary is downloaded and cached on first use:
npx @inference-gateway/cli@latest --help
npx @inference-gateway/cli@latest chat
Or install it globally:
npm install -g @inference-gateway/cli
infer --help
Not recommended for production - prefer the install script, the Nix flake, the container image, or a source build. Prebuilt binaries cover Linux, macOS, and Windows on amd64/arm64.
Install Script (Recommended)
Linux/macOS:
# Latest version
curl -fsSL https://raw.githubusercontent.com/inference-gateway/cli/main/install.sh | bash

# Specific version
curl -fsSL https://raw.githubusercontent.com/inference-gateway/cli/main/install.sh | bash -s -- --version v0.217.0

# Custom directory
curl -fsSL https://raw.githubusercontent.com/inference-gateway/cli/main/install.sh | bash -s -- --install-dir $HOME/.local/bin
Windows (PowerShell 5.1+ / pwsh) uses install.ps1, with -Version and an INSTALL_DIR environment variable for the same two options.
Go Install
go install github.com/inference-gateway/cli/cmd/infer@latestNix Flake / Flox
# Run without installing
nix run github:inference-gateway/cli

# Pin a release
nix run github:inference-gateway/cli/v0.217.0

# Install into your profile
nix profile install github:inference-gateway/cli
With Flox, pin it in .flox/env/manifest.toml under [install] as infer.flake = "github:inference-gateway/cli", then flox activate.
Container Image
docker network create inference-gateway
docker run -d --name inference-gateway --network inference-gateway \
  --env-file .env \
  ghcr.io/inference-gateway/inference-gateway:latest

docker run -it --rm --network inference-gateway ghcr.io/inference-gateway/cli:latest chat
Manual Download
Download binaries from the GitHub releases page - infer-<os>-<arch> for Linux, macOS, and Windows on amd64/arm64 (rename the Windows binary to infer.exe). Verify the download against checksums.txt or its Cosign signature using the Binary Verification guide, then make it executable and move it onto your PATH as infer.
Build from Source
git clone https://github.com/inference-gateway/cli.git
cd cli
CGO_ENABLED=0 go build -tags purego -o infer ./cmd/infer
The build is fully cgo-free on macOS, Linux, and Windows - no C toolchain and no macOS SDK are required, and the same host cross-compiles every target. The purego build tag selects the pure-Go display and input backend and is used on all three platforms.
Shell Completions
The CLI ships an infer completion subcommand (provided by fang) that generates completion scripts for bash, zsh, fish, and powershell. Enabling completions adds tab-completion for subcommands, flags, and many flag values.
# Zsh (current session)
source <(infer completion zsh)

# Zsh (persistent) - write to a directory on $fpath
infer completion zsh > "${fpath[1]}/_infer"

# Bash (current session)
source <(infer completion bash)

# Bash (persistent)
infer completion bash > /etc/bash_completion.d/infer

# Fish
infer completion fish > ~/.config/fish/completions/infer.fish

# PowerShell
infer completion powershell | Out-String | Invoke-Expression
Run infer completion --help to list the supported shells. After writing a persistent completion file, start a new shell (or re-source your shell rc) for it to take effect. If completions do not appear, see Shell Completions Not Working.
Quick Start
# Initialize configuration
infer init

# Generate AGENTS.md documentation for AI agents (recommended for new projects)
infer chat
> /init

# Check gateway status
infer status

# Start interactive chat
infer chat

# Launch web terminal
infer chat --web

# Headless mode
infer headless "Analyze this codebase and suggest improvements"

# Get help (styled output)
infer --help

# Show version
infer --version

# Enable shell completions for the current shell (zsh example)
source <(infer completion zsh)
Generating AGENTS.md
For new projects, use the /init shortcut to automatically generate an AGENTS.md file. This file provides structured documentation that helps AI agents understand your project:
infer chat
> /init
The agent will:
- Analyze your project structure with the Tree tool
- Examine configuration files, build systems, and documentation
- Generate comprehensive
AGENTS.mdincluding:- Project overview and technologies
- Architecture and structure
- Development environment setup
- Key commands (build, test, lint, run)
- Testing instructions
- Project conventions and coding standards
- Important files and configurations
This documentation helps other AI agents (and developers) quickly understand how to work with your project.
How AGENTS.md reaches the model
The project-root AGENTS.md is injected whole into the system prompt as a PROJECT INSTRUCTIONS (AGENTS.md) section, after any custom instructions. It is capped by agent.agents_md.max_lines (default 399) and agent.agents_md.max_chars (default 8000); when the file exceeds either limit it is truncated with a marker. Both limits apply to the root file only. Turn the whole section off with agent.agents_md.enabled: false.
agent:
  agents_md:
    enabled: true
    max_lines: 399
    max_chars: 8000
Environment variables: INFER_AGENT_AGENTS_MD_ENABLED, INFER_AGENT_AGENTS_MD_MAX_LINES, INFER_AGENT_AGENTS_MD_MAX_CHARS.
Nested AGENTS.md files
Following the agents.md standard, an AGENTS.md in a subdirectory holds rules for that directory and takes precedence over the root file there. The CLI points the model at these nested files rather than injecting them, so the model reads a package brief with the Read tool only when it works in that directory - the system prompt stays small no matter how many briefs the repository has.
Discovery walks the working directory up to 4 levels deep and skips hidden directories and node_modules/vendor trees. The walk is lexical, so the system prompt stays byte-stable across turns and keeps prompt-cache prefix hits.
How the section renders depends on the project tree:
- With
agent.context.tree_enabledon (the default): thePROJECT STRUCTURElisting already shows where the nested files are, so only the precedence rule is added. - With the tree off: the precedence rule is followed by the nested paths, at most 20 entries. Beyond that the section notes how many more exist.
Nested files are never subject to max_lines / max_chars, since their content is not injected. When the root AGENTS.md is missing, nested files are still discovered and pointed at.
Help and Version Output
The CLI's help, error, and version output are rendered with fang, so every command produces styled, colorized output. The samples below are shown as plain text; in a real terminal the headings, flags, and errors are colorized.
Help
infer --help (and --help on any subcommand) prints a styled usage page grouped into usage, commands, and flags. Note that -v is --verbose; version is the long-form --version flag.
infer

A powerful command-line interface for managing and interacting with
the Inference Gateway.

USAGE
  infer [command] [--flags]

COMMANDS
  init           Initialize user configuration
  status         Check gateway health and resource usage
  chat           Interactive chat session (TUI)
  headless       Headless task execution
  config         Configuration management
  tools          Run and inspect agent tools directly
  completion     Generate the autocompletion script for the specified shell
  version        Show version information

FLAGS
  -h --help      Show help
  -v --verbose   Verbose output
     --version   Print version information
Errors
Unknown commands and flags exit non-zero with a styled error message and no noisy usage dump (fang sets cobra's SilenceErrors/SilenceUsage and renders the error itself):
$ infer badcmd
Error: unknown command "badcmd" for "infer"
$ echo $?
1
Version
infer --version prints the version, styled by fang:
$ infer --version
infer version vX.Y.Z
The standalone version subcommand is kept for backwards compatibility and prints the same information:
infer versionThe manual
--versionboolean flag was replaced by fang's built-in version handling (fang.WithVersion). Bothinfer --versionand theinfer versionsubcommand remain supported.
Core Commands
| Command | Description | Key Features |
|---|---|---|
infer init | Seed the userspace baseline | Creates ~/.infer/ defaults - writes nothing to the project |
infer status | Check gateway health | Shows resource usage and connectivity, --format json|yaml |
infer chat | Interactive chat TUI | Streaming, scrolling, tool expansion, mode switching |
infer chat --web | Web terminal | Browser interface, tabbed sessions, remote access, live screen |
infer headless <task> | Autonomous task execution | Background operation, task planning, validation |
infer headless --serve | Long-lived AG-UI worker | One run per run_agent_input frame over stdio, no task argument |
infer config <cmd> | Configuration management | Generic get/set for any config key |
infer tools <cmd> | Run agent tools directly | Execute a tool or validate a bash command |
infer stats | Summarize local telemetry | Token usage, tool outcomes, and cost across sessions |
infer traces | View a session's trace span tree | Offline span-tree viewer, --list and JSON output |
Gateway Status
infer status prints a human-readable health block by default. --format json and --format yaml print one machine-readable object instead, for scripts and health checks:
infer status --format json | jq -r .status| Field | Description |
|---|---|
url | The gateway URL that was probed |
status | running or unreachable |
version | The gateway version |
source | Where the gateway runs from (container or binary) |
models | Number of active models |
error | Only present when the gateway is unreachable - the probe failure |
Exit codes: an unreachable gateway still exits 0 - read status to branch on health. An unknown --format value exits non-zero.
Chat Interface Features
Navigation:
- Shift + Arrow Down/Up: Scroll chat history
- Ctrl+O: Toggle tool result expansion
- Ctrl+R: Fuzzy search the project's prompt history (see below)
- Ctrl+M (Alt+M fallback): Toggle raw/rendered markdown
- Shift+Tab: Cycle agent modes (Standard -> Plan -> Auto-Accept -> Auto+Judge)
- Ctrl+K: Toggle model thinking blocks
Capabilities:
- Real-time streaming with syntax highlighting
- Mouse wheel and keyboard scrolling
- Model switching during conversation
- Tool result inspection
- Cost tracking in status bar
- Collapsible thinking blocks
- GitHub issue references - type
#to insert and expand#Ntokens (see below) - Opt-in next-step suggestions as ghost text in the empty input (see below)
Prompt History Search (Ctrl+R)
Ctrl+R opens a fuzzy search over the current project's prompt history above the input:
- Type to filter - matches are highlighted, most recent prompts first, duplicates collapsed.
- Up/Down select an entry.
- Enter loads the highlighted prompt into the input for editing - it is not sent.
- Esc closes the overlay and leaves whatever you had typed untouched.
Muscle memory:
Ctrl+Rused to toggle raw/rendered markdown. That toggle moved to Ctrl+M, with Alt+M as a fallback. Terminals without the Kitty keyboard protocol reportCtrl+MasEnter, so useAlt+Mthere.
Both actions are rebindable in .infer/keybindings.yaml - text_editing_history_search for the search and display_toggle_raw_format for the markdown toggle. infer keybindings list prints the current bindings.
Next-Step Suggestions
When chat.suggestions.enabled is on, the CLI offers a one-line next step as dim ghost text in the empty chat input after an assistant turn completes. It is opt in and off by default:
infer config set chat.suggestions.enabled true
# then /reload in a running chat
The request is sent about two seconds after the turn completes, and only when the UI stayed quiet for that window - empty input, no typing, no autocomplete popup, no overlay form, no busy turn, no queued messages. So it costs at most one small LLM call per completed turn.
| Key | Action |
|---|---|
Tab / Right arrow | Accept the suggestion into the input - not sent |
Esc | Dismiss it and cancel the in-flight request |
| Typing / a new turn | Same - dismisses it and cancels the request |
The call is silent-fail: a timeout, an error or a non-conforming answer leaves the input untouched and logs at debug level, so a flaky suggestion model never interrupts the chat.
Recent problems count too. Beyond the last few conversation messages, the suggestion also takes into account the warnings and errors the session logged since your last message. When something was logged, the suggestion can be about it - and for a logged problem it always asks you to file a GitHub issue as a follow-up, never to fix it. Suggestions grounded in the conversation are unchanged.
The model never reads the logs. It gets a capped, redacted digest: one line per distinct problem with its severity, message and error, repeats collapsed into a count, secrets masked, and no stack traces, callers, timestamps or ids. Another session's problems are left out. With nothing logged, the request is byte-for-byte what it was before, so a quiet session pays no extra tokens.
Limit: the digest covers what the session's own process logged. A problem another process logged for the session - such as a teleport the daemon ran - is not part of it.
The same suggestion reaches AG-UI hosts on the run state - see AG-UI next-step suggestion state.
# .infer/config.yaml
chat:
  suggestions:
    enabled: true
    model: '' # Empty falls back to the active chat model, then agent.model
    context_messages: 4 # Recent non-hidden messages grounding the suggestion
    max_tokens: 512 # Output cap - an answer that hits it is discarded, not truncated
    timeout: 10 # Seconds before the request is abandoned
    logs:
      enabled: true # Take the session's recent warnings and errors into account
      max_lines: 5 # Distinct problems in the digest
max_chars: 600 # Size cap for the whole digest| Key | Default | Description |
|---|---|---|
chat.suggestions.enabled | false | Master switch for the ghost-text suggestion |
chat.suggestions.model | '' | Model for the suggestion call. Empty falls back to the model the chat is using, then agent.model - a cheap, fast model fits here |
chat.suggestions.context_messages | 4 | How many recent non-hidden conversation messages ground the suggestion |
chat.suggestions.max_tokens | 512 | Output token cap. Reasoning models spend thinking tokens against it |
chat.suggestions.timeout | 10 | Seconds before the suggestion request is abandoned |
chat.suggestions.logs.enabled | true | Whether the session's recent warnings and errors are taken into account. false keeps the suggestion to the conversation alone |
chat.suggestions.logs.max_lines | 5 | How many distinct problems the digest carries - repeats of one problem collapse into a count |
chat.suggestions.logs.max_chars | 600 | Size cap for the whole digest. What does not fit is dropped |
Each key has an INFER_* override - INFER_CHAT_SUGGESTIONS_ENABLED, INFER_CHAT_SUGGESTIONS_MODEL, INFER_CHAT_SUGGESTIONS_CONTEXT_MESSAGES, INFER_CHAT_SUGGESTIONS_MAX_TOKENS, INFER_CHAT_SUGGESTIONS_TIMEOUT, INFER_CHAT_SUGGESTIONS_LOGS_ENABLED, INFER_CHAT_SUGGESTIONS_LOGS_MAX_LINES and INFER_CHAT_SUGGESTIONS_LOGS_MAX_CHARS. The system prompt lives in prompts.yaml under chat.suggestions.system_prompt and is overridden with INFER_PROMPTS_CHAT_SUGGESTIONS_SYSTEM_PROMPT.
GitHub Issue References (#)
Type # in the chat input to open a dropdown of the current repository's open issues - each entry shows the issue number, title, and state. The list is resolved through the gh CLI from the repo's git remote, newest first. Selecting an issue inserts a highlighted #N token into your message.
On submit, every #N token is expanded inline into that issue's title, body, and most recent comments (up to the latest 20) before the message is sent to the model - so the agent works from full issue context without a redundant gh issue view lookup.
infer chat
> Summarize #123 and propose a fix
# "#123" expands into the issue title, body, and recent comments before sending
Prerequisite: the gh CLI must be installed and authenticated, and the working directory must be a git repository with a remote. The feature gracefully no-ops when gh is missing, the directory is not a git repo, the repo has no remote, or authentication has expired - the dropdown simply shows nothing.
Both halves are available to daemon and worker clients, so the browser extension and the desktop app offer the same # autocomplete: the list_issues frame answers with the project's recent open issues, and the worker expands the #N tokens of a run_agent_input (or user_message) text part before the run starts. A token counts when it starts the text or follows whitespace, at most 10 distinct issues are expanded per message, and a token whose fetch fails - or one past the cap - is left in place as the raw #N.
Resuming a session (--session-id)
infer chat --session-id <id> loads a persisted conversation before the TUI starts, letting you pick up where you left off. The session must have been persisted by a storage backend (storage.enabled: true).
# Find session IDs from saved conversations
infer conversations list

# Resume a specific session
infer chat --session-id abc-123-def
Session ID resolution:
- A literal UUID is used as-is.
- Any non-UUID value is treated as a session group key and resolved through the session rollover chain to the latest session in that group.
Fallback: If the session cannot be loaded (e.g. the ID does not exist or storage is disabled), the CLI prints a visible notice and starts a new session under the requested ID — the same semantics as infer headless --session-id.
Ignored in non-interactive modes: The flag is ignored (with a printed notice) in --web mode and when input is piped (non-interactive).
Status indicator row
Below the chat input, a row of status indicators shows the current agent state. You can interact with these indicators using the keyboard:
| Key | Action |
|---|---|
Down arrow | Focus the indicator row from the chat input |
Left / Right arrow | Cycle between indicators |
Enter | Open the matching view for the selected indicator |
Esc / Up arrow | Return focus to the chat input |
The selected indicator is highlighted as an accent-colored pill.
Indicator labels:
| Indicator | Label format | Description |
|---|---|---|
| Tools | Tools: N (mode) | N is the number of tools available in the current agent mode. mode is the active mode name (Standard, Plan, Auto-Accept, or Auto+Judge - the latter shown as AUTO+JUDGE - <model>). Opens the /tools view. |
| A2A | A2A: X/Y | X is the number of connected A2A agents, Y is the total number of configured agents. Opens the /agents view. When liveness probes are enabled, X counts down as agents fail and counts back up when they recover - the indicator stays live for the session lifetime. |
| Theme | Theme | Opens the theme selector to change the TUI color scheme. |
| Reconnect | Reconnecting... / Reconnecting (N/M) | Shown in red when the stream has stalled and the CLI is reconnecting. N is the current attempt, M is client.retry.max_attempts. Input is blocked until the stream recovers or all attempts are exhausted. |
| Duration | 3s / 1m5s | The time the agent has worked in this session, next to the cost indicator. Whole seconds only. Nothing is rendered before the session's first run. |
| Artifacts | ⬇ artifacts | Opens the session artifacts view, the same view /artifacts opens. Hidden with chat.status_bar.indicators.artifacts: false. |
Session working time
The duration indicator behaves like a stopwatch: it counts while the agent works, holds when the agent reaches a terminal state - completed, cancelled or failed - and resumes with the next run. A user interrupt stops the counter. While an approval or a question waits on you the display holds and then catches up once it is answered, so the waiting time counts.
The total is saved with the session, so resuming a session continues its count. /new, a new session and a cleared conversation reset it to zero, the same way they reset the cost.
It is on by default and turned off like any other indicator:
# .infer/config.yaml
chat:
  status_bar:
    indicators:
      duration: false # Hide the time the agent has worked in this session (default: true)
Browsing the session's artifacts
/artifacts - or selecting the ⬇ artifacts indicator - lists the files the current session saved under its artifacts directory: screen recordings, generated images, downloads. They are listed on the workspace the session runs on, newest first, each row with its name, size and modification time.
| Key | Action |
|---|---|
Enter | Save the selected artifact on this machine |
o | Save it and open it with the system viewer |
r | List again |
/ | Filter by name |
Esc | Close the view and return to the chat |
A saved artifact lands in ~/.infer/projects/<project-slug>/artifacts/<session id>/ on your machine, and the view reports the path under the list. For a session running locally that is where the file already sits, so Enter just confirms it.
A teleported session's artifacts are listed and read from its pod through the daemon - no kubectl, and a suspended Orchestrator is resumed on the way, which is why the first listing can take a moment. The transfer is one frame per file, so a file over 64 MiB is refused with its size rather than truncated - mirror those out of the pod with an upload hook instead (the session-teleport example does it with RustFS).
Only the files directly under the session's artifacts dir are listed, and a session that has saved nothing yet shows as empty. The frames behind the view are documented under session artifacts.
Background job list
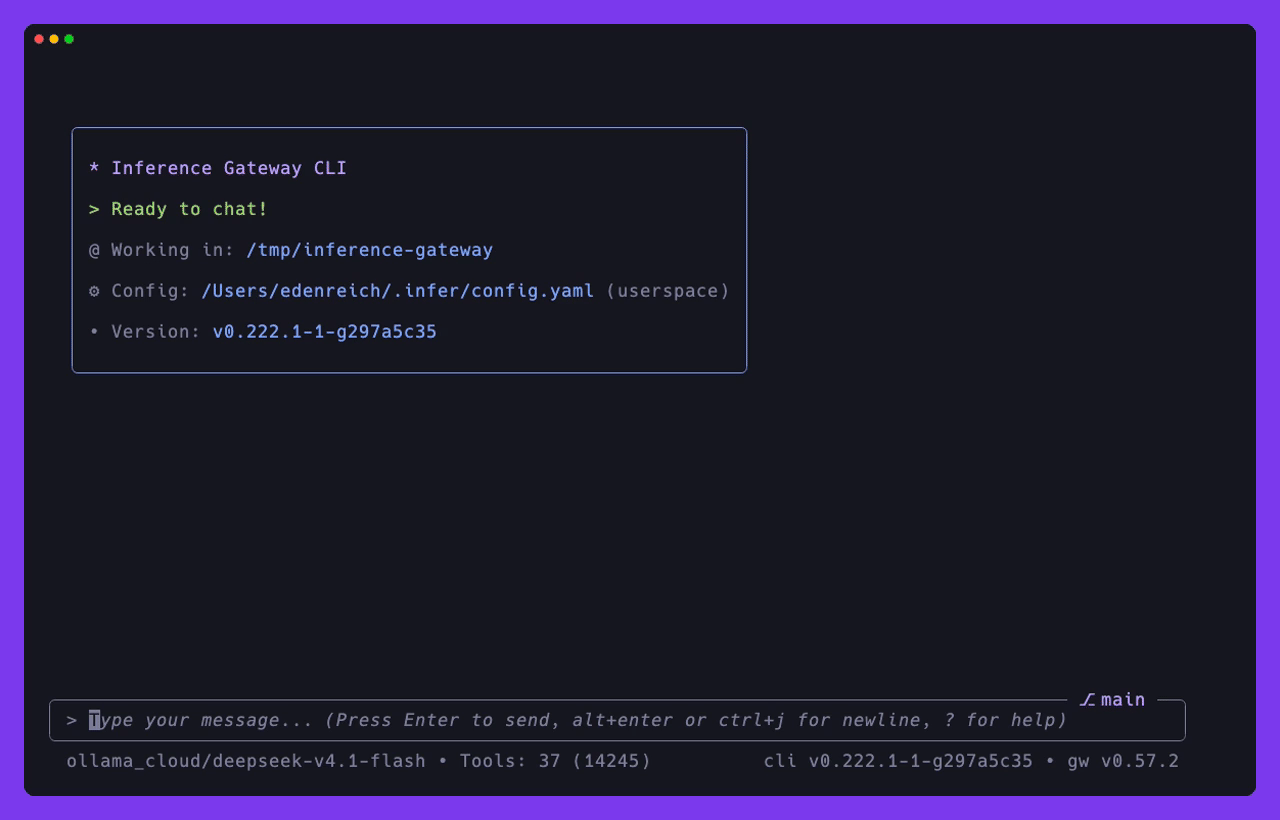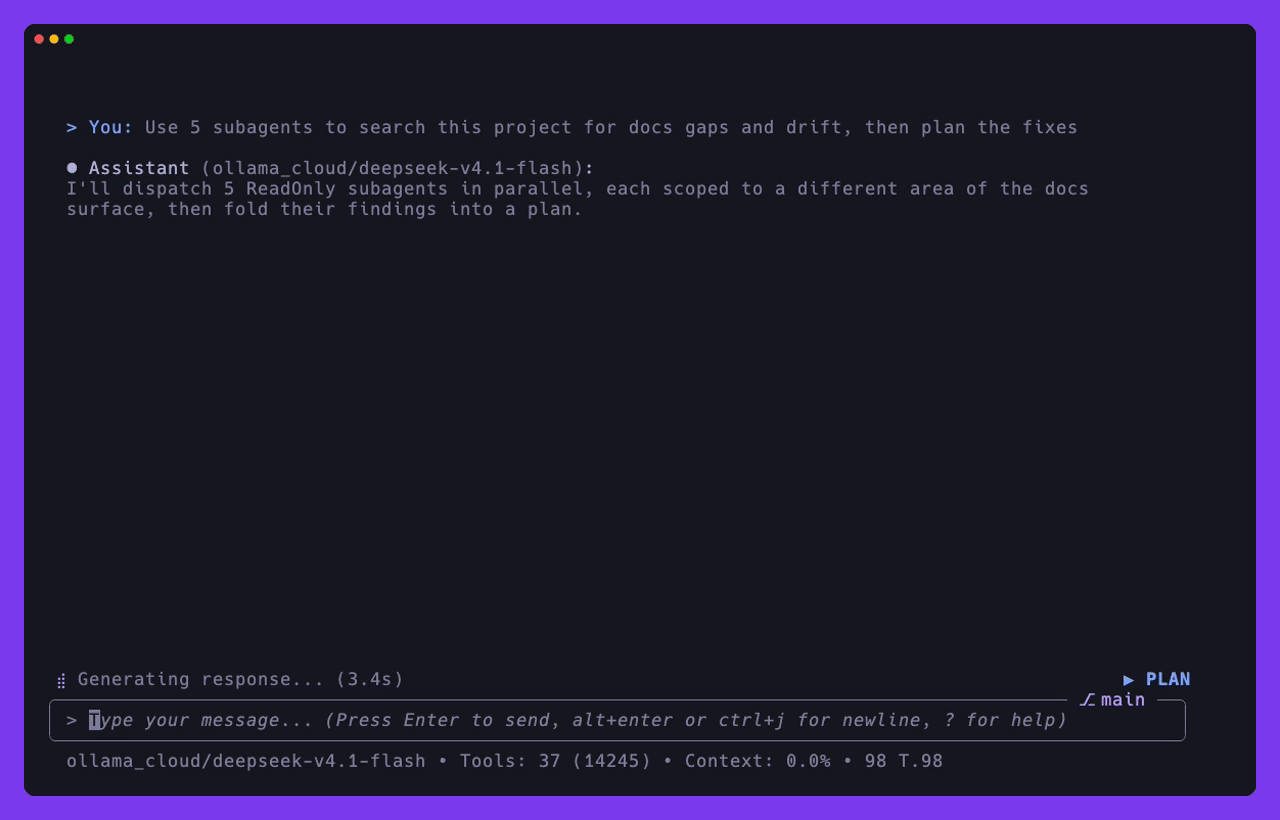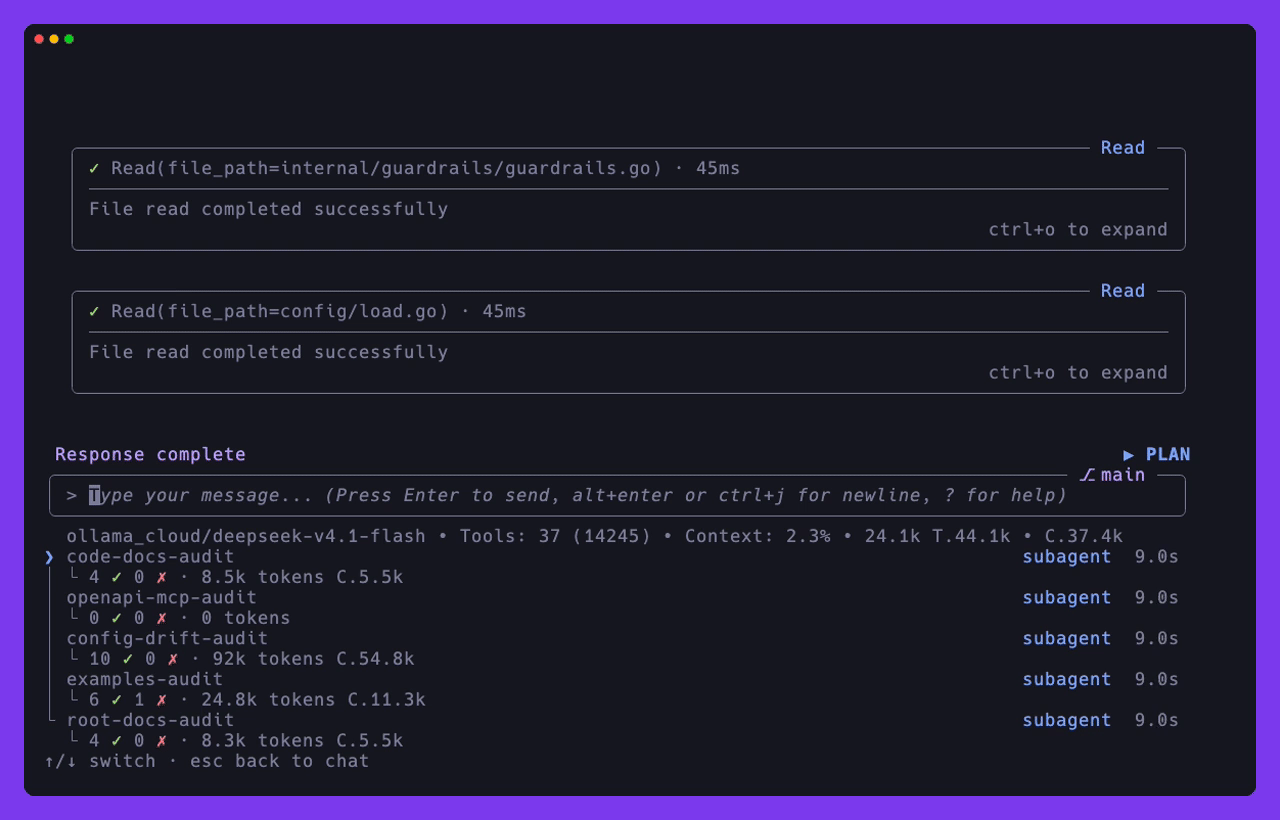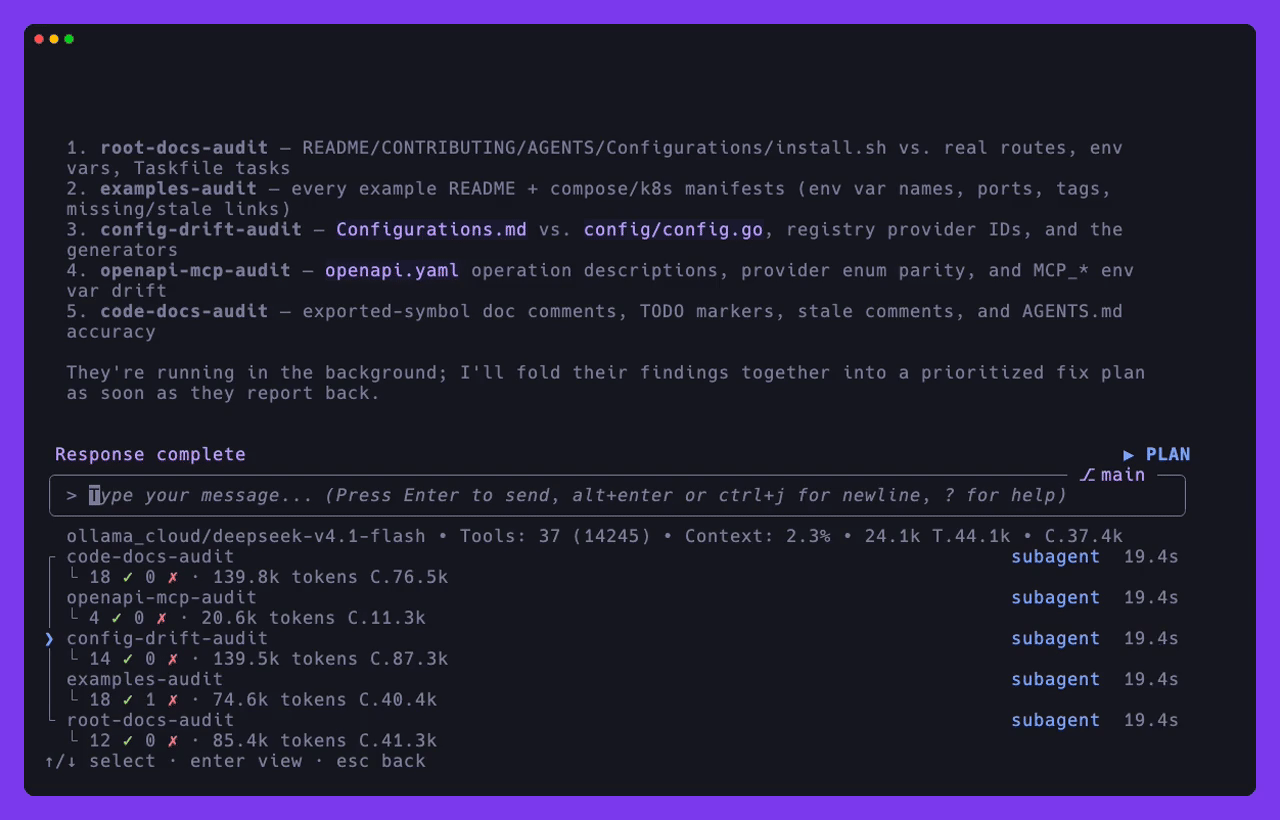
While background jobs are tracked - local subagents, A2A tasks, background shells, screen recordings - they appear as a stacked list below the status indicators, one row per job with its label, kind and a live elapsed counter.
A subagent's row carries a child line with its run stats: tool calls that succeeded and failed, the tokens of its whole session and the slice the provider served from its prompt cache (C.). For a headless subagent the line counts up while it works. Each count's icon takes its status color - ✓ in the success color, ✗ in the error color - only while that count is above 0; at 0 the icon is dimmed, so a run with no failures never shows a red ✗. A finished row lingers with a green ✓ or a red ✗ for chat.status_bar.subagent_linger_seconds (default 5), then drops.
┌ npm run build shell       2.0s
│ reviewer      subagent ✓ 40.0s
│ └ 12 ✓ 1 ✗ · 61.2k tokens C.58.1k
└ tester        subagent ✗ 48.0s
└ 3 ✓ 4 ✗ · 890 tokens| Key | Action |
|---|---|
Down arrow | Focus the job list from the status indicator row |
Up / Down | Move the selection over the tracked jobs |
Enter | Show the selected job's transcript in place of the chat's |
Esc | Back to the chat's own transcript, then back to the input |
Up (on top row) | Return focus to the status indicator row |
Typing any other text blurs the list and lands in the input. While a job is viewed, moving the selection follows it to the newly selected job, and the transcript refreshes once a second until the job is reaped.
Scroll window. The list shows at most 5 rows so a large fan-out cannot push the status bar off screen, but the cap is a scroll window rather than a hard limit: with the list focused, the selection moves over every tracked job and the window scrolls to follow it, so any job can be selected and opened with Enter. Jobs outside the window are summarized by dim boundary markers - N above above the first row and +N more below the last. With the list unfocused the window sits at the top, so only +N more is shown.
Switching models (/model)
/model is the unified model command:
/model <name>- permanently switch the active model for the rest of the session./model <name> <prompt...>- run a single message with<name>, then restore the session model afterward. Handy for sending one hard question to a stronger model without changing your default./model(no argument) - open the model picker.
infer chat
> /model deepseek/deepseek-v4-flash                              # switch the session model
> /model anthropic/claude-opus-4-8 Explain this stack trace    # one-off, then restore
Model picker labels
When you open the model picker (/model with no argument), each model may show a suffix label indicating its capabilities:
| Label | Meaning |
|---|---|
vision | The model accepts image input natively - pasted or @-referenced images are seen directly, no ImageDecode needed. |
audio | The model takes audio input (speech-to-text, multimodal chat). |
video | The model takes video input. |
image-gen | The model generates images (e.g. DALL-E, GPT-Image) rather than text. |
view-only | The model cannot serve /chat/completions and therefore cannot be selected - see below. |
Labels are derived from the gateway-reported modalities (/v1/models?include=modalities), not from name patterns. A model gets the vision label when its input modalities include both text and image; it gets the image-gen label when its output modalities include image without text. Labels are appended to the metadata suffix after the context window and price:
ollama_cloud/glm-5.3-flash (1M, vision, video)
groq/whisper-large-v3      (?, $0.04/$0.00 per MTok, audio, view-only)
Gateway version requirement: Modalities-driven labels and the chat-capability filter require gateway v0.47+. Against an older gateway, models report no modalities, so no labels are shown and no model is chat-capable. Upgrade the running gateway to v0.47+ to see your catalog.
View-only models
Non-chat models - speech-to-text (e.g. groq/whisper-*), text-to-speech (e.g. openai/tts-*, groq/playai-tts*), image generation and video - are listed in the picker with a view-only marker, after the chat-capable rows. They are visible so you can see what the gateway offers, but pressing Enter on one is rejected with a notice (<model> does not support chat and cannot be selected) and the picker stays open. Only chat-capable models can be selected, and /model <name>, model validation and autocomplete are unaffected.
A model the gateway reports no modalities for ("modalities": null) is treated as not chat-capable, which is how most speech and embedding models arrive.
Filter tabs
The picker has two tab rows that are ANDed together, so Free + Vision lists only free vision models:
| Row | Keys | Tabs |
|---|---|---|
| Pricing | 1-4 | [1] All, [2] Free, [3] Pay-as-you-go, [4] Subscription |
| Capability | 5-8 | [5] Any, [6] Vision, [7] Audio, [8] Video |
Vision matches image input. Audio and Video match models that work with that modality on either side, so both speech-to-text and text-to-speech models appear under Audio. See Model Categories for how the pricing tabs are derived.
The footer help line lists the full keymap:
↑↓ navigate · Enter select · / search · esc clear · 1-4 pricing · 5-8 capability · Ctrl+C cancelDigits typed while the search input is active (/) go into the query, not the tabs.
Diff viewer and git staging
When the agent proposes file changes (or you open a diff), the diff viewer supports patch-level staging - select individual lines, split hunks, and stage or unstage everything at once. All keys are configurable in .infer/keybindings.yaml (category diff_viewer); the defaults:
| Key | Action |
|---|---|
space / v | Start or clear a line-range selection within the current hunk |
a / u / enter | Apply (stage/unstage) the selected lines - or the whole hunk if none selected |
s | Split the current hunk into smaller, independently stageable blocks |
] / [ | Jump to the next / previous hunk |
A | Stage all changes (git add -A, including untracked files and deletions) |
U | Unstage all changes (git reset -q HEAD) |
Select a range with space/v, navigate, then apply to stage just those lines - or split a mixed hunk with s and stage each block separately. The footer hint reflects whether a selection is active, and hides discard when a staged file is selected (discard only applies to unstaged changes).
Agent Modes
Toggle between modes anytime during chat using Shift+Tab.
| Mode | Tools | Approval | Best For |
|---|---|---|---|
| Standard (Default) | All configured | Required for Write/Edit/Delete/Bash | General development, collaborative coding |
| Plan | Read, Grep, Tree, read-only subagents, plus writes and Bash inside the scratchpad | Standard rules inside the scratchpad | Code reviews, architecture analysis, planning |
| Auto-Accept (YOLO) | All configured | None - immediate execution | Trusted environments, rapid prototyping, automation |
| Auto+Judge | All configured | An LLM judge answers every gate | Unattended CI/headless runs that still want a gate |
Standard Mode
Full tool access with safety controls and approval prompts for sensitive operations.
infer chat
> "Refactor the authentication module to use environment variables"
# Agent analyzes code, proposes changes, requests approval before modifying
Plan Mode
Analysis and planning, with your working tree read-only until the plan is approved. Write, Edit, MultiEdit, Delete and Bash do execute while planning, but only inside one directory - the scratchpad - so the agent can copy a file in, try the change, build or test it, and write a plan backed by evidence instead of guesswork.
infer chat
# Press Shift+Tab to switch to Plan Mode
> "How should I implement user authentication with JWT tokens?"
# Agent explores code structure and provides detailed plan
While planning, the agent can pause to ask you up to four multiple-choice clarifying questions with the AskUserQuestion tool, then fold your answers into the plan it submits for approval. The same tool is available in the other interactive modes, where the answers come back mid-task instead.
When the investigation spans several areas, the agent can fan it out to local subagents that explore in parallel. In plan mode every subagent runs read-only, whatever its preset or tool allowlist says, so a delegated subagent may explore the repository but never change it. Ask for it directly ("Use 5 subagents to search this project for docs gaps and drift, then plan the fixes") and watch them work from the background job list under the composer.
The scratchpad
Plan mode gets exactly one writable directory:
~/.infer/projects/<project-slug>/tmp/scratchpadIt is the only location Write, Edit, MultiEdit, Delete and Bash may touch while planning. Every other path stays read-only, whatever your sandbox configuration allows and whatever you granted in another mode. Bash runs with its working directory pinned there, so verification touches only scratch copies.
How it behaves:
- Lazily created on the first write or the first plan-mode command.
- Outside the git working tree, so nothing leaks into commits. It is wiped by
/resetalong with the other runtime directories. - Survives plan approval into the fresh session that executes the plan, so the executing agent can still read what was verified.
- A write outside it is a plain error naming the scratchpad path. No grant can unlock plan mode, so the rejection does not offer the usual sandbox-grant approval prompt.
../traversal out of the scratchpad, and a symlink inside it pointing outside, are rejected the same way.
The built-in plan-mode guidance names the scratchpad and tells the model to copy files in rather than edit originals, verify there, report what it proved under the plan's ## Verification section, and keep the scratchpad out of ## Files to Modify - it is never part of the change.
Two limits worth knowing:
- Writing inside the scratchpad still goes through the normal approval rules, so a scratch write can still prompt you in Standard-style gating.
- The pinned working directory applies to every plan-mode command, including the baseline ones -
git statusin plan mode reports on the scratchpad, not on your project. An allow-listed command can also still reach outside the scratchpad through an absolute path argument: the file tools are the hard boundary, the shell is allowed-list plus approval.
How mode instructions are delivered
Plan-mode instructions are not a system prompt. The system prompt at message[0] is byte-stable for the whole session - including across Shift+Tab mode switches - so the provider/local prompt (KV) cache keeps its prefix hits. The per-mode instructions ride along in the built-in mode-change-reminder (on_mode_change trigger) that fires when the mode changes, substituted into its {guidance} placeholder.
prompts.agent.mode_adjustment_plan and prompts.agent.mode_adjustment_auto (env: INFER_PROMPTS_AGENT_MODE_ADJUSTMENT_PLAN / _AUTO) let you override that guidance. They ship empty - the built-in texts live in the mode-change reminder's guidance map. Precedence per mode, highest first:
| Priority | Source |
|---|---|
| 1 (Highest) | guidance.<mode> in your reminders.yaml |
| 2 | prompts.agent.mode_adjustment_<mode> in prompts.yaml |
| 3 (Lowest) | Built-in default guidance |
Deprecated names.
prompts.agent.system_prompt_plan/system_prompt_auto(envINFER_PROMPTS_AGENT_SYSTEM_PROMPT_PLAN/_AUTO) still load into the new fields with a deprecation warning; when both are set the new names win.Trade-off: since the mode-change reminder is the sole carrier of mode-specific instructions, setting
enabled: falseinreminders.yaml(orINFER_REMINDERS_ENABLED=false) means those instructions are never delivered. Tool restrictions still apply - only the guidance text is lost.
Approving a plan
When the plan is ready, the agent calls RequestPlanApproval; the chat TUI renders the saved plan in a dedicated panel and shows a status line - use the arrow keys to select an option and Enter to confirm. Three options are offered:
| Option | Key | Resulting mode | Effect |
|---|---|---|---|
| Accept (default) | Enter / y | Auto-Accept | Executes the plan with no per-action approval prompts. |
| Approve Each Step | s | Standard | Executes the plan but prompts for approval on each Write/Edit/Delete/Bash action. |
| Reject | n | - | Ends the session; reply with feedback and the agent re-iterates the plan. |
The default Accept enables Auto-Accept mode - unrestricted execution with no per-action approval. Pick Approve Each Step to accept the plan but keep the Standard-mode approval gate on every action. The plan file stays on disk whichever you choose; rejecting a plan does not delete it. The scratchpad is left in place too, so the session that executes the plan can read whatever was verified there.
Auto-Accept Mode
Zero approval prompts for maximum speed. Use with caution in version-controlled environments.
infer chat
# Press Shift+Tab twice to switch to Auto-Accept Mode
> "Run the test suite, fix all failing tests, and commit the changes"
# Agent executes everything immediately
Important for Auto-Accept: Ensure clean git working tree and backups.
Because the per-action approval gate is off in this mode, the agent runs under a dedicated destructive-action policy delivered by the mode-change reminder (see How mode instructions are delivered; override with prompts.agent.mode_adjustment_auto). It is told to stop and confirm before irreversible operations - deletes, git push --force, git reset --hard, dropping databases, rm -rf, publishing or releasing - to prefer the reversible path when no user is reachable, and never to print or publish a secret value. With reminders disabled this policy text is not delivered.
Auto+Judge Mode
Autonomous like Auto-Accept, but the calls that would prompt a human are decided by an LLM judge instead of being waved through. Press Shift+Tab once more from Auto-Accept, or select the mode explicitly in headless runs:
infer headless --mode auto-with-judge "fix issue #42"The judge is configured in its own judge.yaml file, and the same gate is available in any mode via tools.safety.approval_behaviour: judge. Both are off by default. See Judge Mode for the verdict contract, on_error semantics, and observability.
Headless Agent Stream Output
infer headless <task> runs the agent non-interactively and writes a newline-delimited JSON (JSONL) stream to stdout. Each line is one JSON object with a type discriminator, intended for programmatic consumers such as the infer-action GitHub Action. The stream is additive: new type values may be introduced over time and consumers should ignore any type they do not recognize.
infer headless "Refactor the authentication module"Secure by default. A headless run executes in standard mode, so off-list or mutating actions are not auto-run - they are blocked (when no approver is reachable) or sent for IPC approval (under a channel manager). See Headless secure-by-default to opt into more autonomy.
Output format (--format)
The output format is controlled by the --format flag (renamed from the legacy --output-format). It accepts four values:
json(default) - newline-delimited JSON (JSONL), one compact object per line, suitable for programmatic consumptionjson-pretty- same per-turn stream asjsonwith each object indented across multiple lines for human readingag-ui- spec-compliant AG UI framed output withTEXT_MESSAGE_START/CONTENT/ENDframing and a fresh message id per turn. Atoken_usagecustom event follows every LLM step. The terminalRUN_FINISHEDevent carries the session totals in itsresult, or thecancelledoutcome when the turn was stopped. Resuming with--session-idopens the run with aMESSAGES_SNAPSHOTof the restored conversation. Implied by--servetext- human-readable plain text output
# Default JSON output
infer headless "Refactor the authentication module"

# Human-readable pretty-printed JSON
infer headless "Analyze the codebase" --format json-pretty
Machine consumers should keep using
jsonfor performance;json-prettyis for debugging and human inspection.
Stream event types
Every line in the json (or json-pretty) stream is a JSON object with a type discriminator. The stream is additive - new types may be introduced and consumers should ignore any they do not recognize.
| Type | When emitted | Description |
|---|---|---|
info | Once at start | Run metadata (model, session id) |
assistant | Per turn | Assistant response with content, reasoning_content, tool_calls, token_usage |
tool | Per tool call | Tool execution result. content holds the bare marshaled result (no legacy Result of tool call: / Tool execution failed: envelope). Structured tool_execution metadata (tool_name, success, error, rejected, duration) and the failed flag ride alongside. |
approval_request | When approval is needed | Approval request metadata |
judge_verdict | Per judge decision | Emitted under judge mode or approval_behaviour: judge - tool, decision, reason, model, turn. Mirrored as a custom event in ag-ui. |
computer_use_paused | On a pause control message | Computer use was paused; carries the session request_id - see pause and resume control |
computer_use_resumed | On a resume control message | Computer use was resumed; carries the session request_id |
session_stats | Once at end | Token usage and cost summary (detailed below) |
agent_error | Before stream starts | Machine-readable error when the run fails before any turn (gateway unavailable, unknown model). For ag-ui format this is emitted as RUN_ERROR. |
One assistant line per LLM turn
Each completed LLM turn emits exactly one assistant line, in turn order - an empty turn (no content, no reasoning, no tool calls) emits none. That holds for a text-only turn the agent continued past because a post_stream continuation nudge fired (todo continuation, truncation continuation, empty-response continuation): the nudged turn keeps its own assistant line instead of being merged into the next turn's line. Consumers that walk the stream by turn can therefore treat assistant lines as the sequence of turns that produced output, and read the final answer from the content of the last assistant line.
The hidden system reminder a continuation nudge appends is not emitted to the stream. It exists only in the model-facing message history, so it never shows up as an assistant or tool line. Reminder text visible in a trace or under logging.debug is log output, not a stream line.
In the ag-ui format the same contract holds one level up: one TEXT_MESSAGE_START / CONTENT / END triple with a fresh message id per LLM turn, nudge-continued turns included.
Exit codes:
| Code | Meaning |
|---|---|
| 0 | Task completed successfully |
| 1 | Task failed |
| 2 | Max turns exhausted (agent.max_turns) |
| 3 | Time budget exhausted (agent.max_duration_minutes) |
Codes 2 and 3 are both "stopped early, not broken" - a harness can tell out of turns from out of time and salvage the work in progress instead of treating the run as a failure.
Headless behavior:
- Subagent mode: Headless runs always spawn subagents in
headlessmode, never tmux/interactive, regardless oftools.agent.mode. - Background tasks: The run waits for in-flight background tasks (background shells, A2A tasks) before completing, bounded by
a2a.task.agent_mode_max_wait_seconds. - Session rollover: Long conversations automatically roll over into a new session id (session compact, see Compaction). A non-UUID
--session-idis treated as a session-group key that follows these rollovers - useful for channel-based workflows.
Pause and resume control (IPC)
A host UI (the desktop app, or any process that owns the infer headless subprocess) can pause and resume an in-flight computer-use run by writing a control line to the agent's stdin, the same IPC pattern as approval_response:
{ "type": "computer_use_control", "action": "pause" }
{ "type": "computer_use_control", "action": "resume" }- Works with the
json,json-pretty, andag-uiformats, with or without--require-approval, and regardless of thecomputer_use.approvallevel. - Pause cancels the in-flight request and emits
computer_use_paused. - Resume restarts the run over the same conversation with a hidden
Please continue from where you left off.message, and emitscomputer_use_resumed. The resume also clears the cancellation the paused run carried, so a pause and resume stays one successful run. - A malformed line, an unknown
type, or an unrecognizedactionis ignored (logged as a warning), so the stdin stream can carryapproval_responseandcomputer_use_controlmessages interleaved.
Events out. In the json / json-pretty stream both events are plain JSON lines carrying the session request_id:
{ "type": "computer_use_paused", "request_id": "b7a1c3d2-..." }
{ "type": "computer_use_resumed", "request_id": "b7a1c3d2-..." }
In the ag-ui stream they arrive as CUSTOM events with the same names:
{ "type": "CUSTOM", "name": "computer_use_paused", "value": { "request_id": "b7a1c3d2-..." } }
{ "type": "CUSTOM", "name": "computer_use_resumed", "value": { "request_id": "b7a1c3d2-..." } }
Example. Pause the run, then resume it a few seconds later:
{
  sleep 5
  echo '{"type":"computer_use_control","action":"pause"}'
  sleep 5
  echo '{"type":"computer_use_control","action":"resume"}'
} | infer headless --format json "Open the settings window and enable dark mode"{"type":"info","model":"...","session_id":"b7a1c3d2-..."}
{"type":"assistant","content":"Taking a screenshot to find the settings window..."}
{"type":"computer_use_paused","request_id":"b7a1c3d2-..."}
{"type":"computer_use_resumed","request_id":"b7a1c3d2-..."}
{"type":"assistant","content":"Continuing - clicking the appearance tab..."}
{"type":"session_stats","message":"Session complete","...":"..."}Session stats summary line
When a session completes, the CLI emits a single session_stats line summarizing token usage and computed dollar cost for the run. This lets consumers report real run cost without re-implementing the per-model pricing table.
{
  "type": "session_stats",
  "message": "Session complete",
  "timestamp": "2026-05-29T17:48:55+02:00",
  "model": "deepseek/deepseek-v4-flash",
  "prompt_tokens": 21000,
  "completion_tokens": 1260,
  "total_tokens": 22260,
  "requests": 7,
  "cost": { "input": 0.0021, "output": 0.0008, "total": 0.0029, "currency": "USD" }
}
Fields:
| Field | Type | Description |
|---|---|---|
type | string | Always session_stats for this line. |
message | string | Human-readable status, currently Session complete. |
timestamp | string | RFC 3339 timestamp at which the line was emitted. |
model | string | Model used for the run. A single model is attributed per run. |
prompt_tokens | number | Sum of input tokens across all requests in the run. |
completion_tokens | number | Sum of output tokens across all requests in the run. |
total_tokens | number | prompt_tokens + completion_tokens. |
requests | number | Number of LLM requests (turns that reported usage) in the run. |
cost | object | Computed dollar cost for the run - see Cost object. |
Cost object
| Field | Type | Description |
|---|---|---|
input | number | Cost attributed to prompt_tokens using the configured pricing table. |
output | number | Cost attributed to completion_tokens using the configured pricing table. |
total | number | input + output. |
currency | string | ISO 4217 currency code from pricing.currency. Defaults to USD. |
When pricing.enabled: false (or pricing data is unavailable for the model), input, output, and total are all 0 while currency is still populated. The cost object is always present, giving consumers a stable schema.
Behavior notes:
- The line is additive - it does not replace any existing stream output.
- It is emitted once per run, at session completion (including on early errors).
- It is always emitted in
agentmode - there is no flag to enable or disable it. - Cost is attributed to a single model per run.
- Consumers should ignore unknown
typevalues to remain forward-compatible.
AG-UI RUN_FINISHED result
In the ag-ui format the same totals ride on the terminal RUN_FINISHED event instead of a session_stats line. result carries the per-session totals, cumulative across the session (not just the current run):
{
  "type": "RUN_FINISHED",
  "threadId": "b7a1c3d2-...",
  "runId": "9f4e1a0b-...",
  "result": {
    "inputTokens": 21000,
    "outputTokens": 1260,
    "cacheReadTokens": 18400,
    "totalToolCalls": 7,
    "cost": 0.0029,
    "lastInputTokens": 12800,
    "contextWindow": 128000
  }
}| Key | Type | Description |
|---|---|---|
inputTokens | number | Total input tokens across the session. |
outputTokens | number | Total output tokens across the session. |
cacheReadTokens | number | Tokens served from the prompt cache. |
totalToolCalls | number | Tool calls issued across the session. |
cost | number | Total session cost, in the configured currency. |
lastInputTokens | number | Input tokens of the most recent request. |
contextWindow | number | Model context window in tokens, omitted when the model's window is unknown. |
The event has no result when the run made no model request, so consumers must treat it as optional.
The same stats object is also streamed as a CUSTOM event named token_usage after every LLM step, before tool execution continues, so consumers can track cumulative usage while the run progresses. Its value keys match the RUN_FINISHED result above, including contextWindow being omitted when the model's window is unknown, and the event is not emitted until the session has made at least one model request:
{
  "type": "CUSTOM",
  "name": "token_usage",
  "value": {
    "inputTokens": 21000,
    "outputTokens": 1260,
    "cacheReadTokens": 18400,
    "totalToolCalls": 7,
    "cost": 0.0029,
    "lastInputTokens": 12800,
    "contextWindow": 128000
  }
}
AG-UI cancelled runs
Every run is bracketed by RUN_STARTED and exactly one terminal RUN_FINISHED or RUN_ERROR. A stopped turn is not a failure: it ends as AG-UI 1.0 describes cancelled runs, a RUN_FINISHED carrying outcome cancelled and no result, rather than a RUN_ERROR:
{
  "type": "RUN_FINISHED",
  "threadId": "b7a1c3d2-...",
  "runId": "9f4e1a0b-...",
  "outcome": "cancelled"
}
RUN_ERROR stays reserved for a run that actually failed (a panic, a gateway error, a worker that died mid-turn), so a host can tell "the user stopped this" apart from "this broke" without parsing error text.
A computer-use pause cancels the in-flight request, so a paused run is a cancelled one. A later computer_use_resumed clears that cancellation - the pause and the resume stay one successful run, and the terminal event the host finally sees is an ordinary RUN_FINISHED with its result. Hosts should therefore treat cancelled as the outcome of the turn, not as a reason to tear down the thread.
The same outcome reaches daemon clients that send an interrupt frame, since the worker's stdio stream and the daemon socket carry identical frames.
For AG-UI consumers (the desktop app sidecar, or any process hosting infer headless --format ag-ui): the per-step token_usage events stream the cumulative stats above, so live indicators stay current during the run instead of jumping once at RUN_FINISHED. Drive the context-percentage indicator from lastInputTokens / contextWindow - lastInputTokens is the live occupancy of the window, where inputTokens is a session-wide sum and will overshoot it. Hide the indicator when contextWindow is absent. Drive the cost indicator from cost, which is already the computed dollar total and needs no per-model pricing table on the client.
AG-UI next-step suggestion state
A serve worker carries the same one-line next-step suggestion the chat TUI shows as ghost text on the run state, under the nextStepSuggestion key. It is patched with a STATE_DELTA just before the terminal RUN_FINISHED or RUN_ERROR, so a host renders the suggestion for the turn that just ended:
{
  "type": "STATE_DELTA",
  "delta": [
    {
      "op": "add",
      "path": "/nextStepSuggestion",
      "value": "Run the test suite to confirm the fix"
    }
  ]
}- The key is seeded
""in everySTATE_SNAPSHOT, so it is always present and a client needs no absent-key branch. - A suggestion that is disabled, failed or discarded publishes nothing - the key stays at its seeded
"". A turn with a message already queued behind it, a failed or cancelled run, and a subagent's worker ask for no suggestion at all. - The suggestion call's tokens land in the same session totals the terminal event carries.
AG-UI computer-use activity and recording state
Under --format ag-ui the stream itself reports what a computer-use run is doing and whether a screen recording is up, so a host (the desktop app overlay and monitor, or any AG-UI client) renders them from standard events instead of reverse-engineering Computer tool arguments and RecordStart results.
Computer-use activity. Each pointer or keyboard action is written as an ACTIVITY_SNAPSHOT with activityType computer_use, keyed computer_use:<toolCallId>, just before the Computer tool performs it:
{
  "type": "ACTIVITY_SNAPSHOT",
  "activityType": "computer_use",
  "messageId": "computer_use:call-1",
  "content": {
    "toolCallId": "call-1",
    "action": "click",
    "x": 812,
    "y": 344,
    "screenWidth": 1920,
    "screenHeight": 1080
  }
}- Written for the pointer actions
move,click,double_click,triple_clickand the keyboard actionstypeandkey. Keyboard actions carry noxandy. xandyare already scaled to screen coordinates, andscreenWidth/screenHeightgive the space they are relative to - an overlay can place a cursor marker without knowing the model's own resolution.- The snapshot replaces the previous one with the same
messageId, so a client keeps one live action entry per tool call.
Recording state. The screenRecording key of the run state object carries active, and while a recording runs also where it writes and what it captures:
{
  "type": "STATE_DELTA",
  "delta": [
    {
      "op": "add",
      "path": "/screenRecording",
      "value": {
        "active": true,
        "path": "/home/user/.infer/projects/my-app/tmp/media/recordings/session-1.mp4",
        "region": { "x": 0, "y": 0, "width": 1280, "height": 720 },
        "frameWidth": 1280,
        "frameHeight": 720
      }
    }
  ]
}| Field | Value |
|---|---|
active | Whether a recording is running right now - the only field when it is off |
path | The file the recording is being written to |
region | The captured region, {x, y, width, height} |
frameWidth / frameHeight | The dimensions of the frames the recorder captures |
region and frameWidth/frameHeight are in the frame space the recorder captures - the same space screenshots and their annotations use - so a client can overlay the region without rescaling. This is the same state key the daemon carries, because a session worker is an infer headless --format ag-ui process.
The full per-event reference lives with the CLI source, in docs/ag-ui-output.md.
Writing the result to a file (--result-file)
infer headless accepts a --result-file <path> flag that atomically writes the final assistant message and the run outcome as JSON to <path> on exit. The Agent tool uses it to harvest the result of an interactive (tmux pane) subagent only - headless subagents report each turn on stdout instead, see --keep-alive. The flag is useful on its own whenever a script needs the final answer as a file rather than by parsing the stdout stream.
infer headless "Summarize the open PRs" --result-file /tmp/result.jsonRunning the task as a plain prompt (--prompt-only)
infer headless --prompt-only <task> sends the task text to the model as a plain prompt. Nothing in it is intercepted first: a leading ! or !! is not run as a direct shell call, and a leading / is not resolved as a shortcut - both reach the model as ordinary text.
infer headless --prompt-only "/compact is the command I mean to document"Use it whenever the task text comes from somewhere you do not control, so an untrusted caller cannot turn a prompt into a shell command. The daemon's A2A server always sets it for the tasks it serves.
Keeping the session alive (--keep-alive)
infer headless --keep-alive <task> does not exit when the task turn ends. It keeps the process and the session alive and reads further work from stdin: each run_agent_input frame runs as another turn in the same session, so follow-ups keep the accumulated context instead of starting over. Every finished turn is reported as one subagent_turn line on stdout, and closing stdin (EOF) ends the run.
infer headless --keep-alive --session-id sub-1 "Review the auth module" <<'FRAMES'
{"type":"run_agent_input","input":{"messages":[{"id":"m2","role":"user","content":"Also cover the token refresh path"}]}}
FRAMES
Each turn prints a line like:
{
  "type": "subagent_turn",
  "final_assistant": "...",
  "success": true,
  "session_id": "sub-1",
  "done": true,
  "stats": { "tools_succeeded": 3, "tools_failed": 0, "input_tokens": 1200, "output_tokens": 80 }
}
The line is the --result-file JSON shape plus "type": "subagent_turn" and done, so a consumer that already parses result files needs no new parser.
--format text and --serve are rejected with --keep-alive: the first has no frame to carry a turn line, and the second is already a long-lived worker with its own AG-UI protocol. This is the shape the Agent tool spawns its async headless subagents in - see headless keep-alive lifecycle.
Resuming a session (--session-id)
infer headless --session-id <id> loads a persisted conversation before the agent starts, letting you resume a previous session. The session must have been persisted by a storage backend (storage.enabled: true).
# Find session IDs from saved conversations
infer conversations list

# Resume a specific session
infer headless "Continue the refactoring" --session-id abc-123-def
Session ID resolution:
- A literal UUID is used as-is.
- Any non-UUID value is treated as a session group key and resolved through the session rollover chain to the latest session in that group.
Fallback: If the session cannot be loaded (e.g. the ID does not exist or storage is disabled), the CLI prints a visible notice and starts a new session under the requested ID.
The same flag is also available on infer chat --session-id for resuming chat sessions interactively.
AG-UI resume snapshot
Under --format ag-ui, resuming an existing conversation emits a MESSAGES_SNAPSHOT of the restored conversation right after RUN_STARTED, before the turn produces anything of its own. A host that reconnects to a thread can therefore render the prior history from the stream itself, with no side channel and no separate conversation-read command:
infer headless --format ag-ui --session-id abc-123-def "Continue the refactoring"{"type":"RUN_STARTED","threadId":"abc-123-def","runId":"9f4e1a0b-..."}
{"type":"MESSAGES_SNAPSHOT","messages":[
{"id":"msg-1","role":"user","content":"Refactor the authentication module"},
{"id":"msg-2","role":"assistant","content":"Reading the module first.","toolCalls":[{"id":"call-1","type":"function","function":{"name":"Read","arguments":"{\"file_path\":\"auth.go\"}"}}]},
{"id":"msg-3","role":"tool","toolCallId":"call-1","content":"package auth\n..."}
]}Each entry of the stored conversation maps to one snapshot message:
| Field | On | Value |
|---|---|---|
id | every message | The stored message id |
role | every message | user, assistant, system or tool |
content | every message | The message's text content |
toolCalls | assistant messages | The tool calls that message issued, omitted when it issued none |
toolCallId | tool messages | The id of the assistant tool call this result answers |
error | tool messages | The failure message, present only when that tool execution failed |
- Only a restored conversation produces a snapshot - a fresh session (an unknown
--session-id, or none at all) starts withRUN_STARTEDand no snapshot, so hosts should treat it as optional. - The event is the same
MESSAGES_SNAPSHOTthe daemon answersnew_session/resume_conversationwith, because a session worker is aninfer headless --format ag-uiprocess.
Serve worker (--serve)
infer headless --serve is a long-lived worker: one process per thread instead of one process per prompt. It takes no task argument and implies --format ag-ui. It reads app frames from stdin and runs one agent turn per run_agent_input frame, writing each turn to stdout as one AG-UI run - RUN_STARTED with threadId set to the conversation id, then exactly one RUN_FINISHED or RUN_ERROR.
infer headless --serve --session-id abc-123-defThis is the shape the daemon spawns its session workers in, so a host that owns the subprocess speaks the same vocabulary as a daemon client: app frames in with a lowercase type, AG-UI events out with an uppercase type, no envelope and no translation.
{
  "type": "run_agent_input",
  "input": {
    "messages": [{ "id": "m1", "role": "user", "content": "Refactor the authentication module" }]
  }
}{"type":"RUN_STARTED","threadId":"abc-123-def","runId":"9f4e1a0b-..."}
{"type":"TEXT_MESSAGE_START","messageId":"msg-4","role":"assistant"}
{"type":"TEXT_MESSAGE_CONTENT","messageId":"msg-4","delta":"Reading the module first."}
{"type":"TEXT_MESSAGE_END","messageId":"msg-4"}
{"type":"RUN_FINISHED","threadId":"abc-123-def","runId":"9f4e1a0b-...","result":{"...":"..."}}Stdin frames:
| Frame | Behaviour |
|---|---|
run_agent_input | Runs one turn from input.messages (the new messages only - the worker owns the history). Sent mid-turn it is queued and drained into the running turn; anything still queued when a turn ends starts the next turn. An input.resume answers a pending interrupt, and an empty input resumes |
interrupt | Cancels the running turn, which ends with RUN_FINISHED outcome cancelled |
browser_result | Answers a browser_command the worker wrote on stdout - see browser tools without a port |
approval_response | Unchanged: tool_call_id, approved, scope for a pending tool call |
user_question_response | Unchanged: the collected AskUserQuestion answers, or a dismissal |
computer_use_control | Unchanged: action is pause or resume - see pause and resume control |
Only the first run of a resumed session opens with a MESSAGES_SNAPSHOT; later runs on the same worker start with RUN_STARTED alone, because the host already has the history.
Browser tools without a port
With browser_use.backend: extension a serve worker binds no port. A browser tool writes a browser_command line on stdout and waits for the browser_result line with the same id on stdin, so the host relays both to the extension - exactly what the daemon does for its own workers. Only a daemon binds the extension port.
Shutdown
Closing stdin (EOF) lets the running turn and any queued run_agent_input frames finish, then shuts the worker down together with the gateway, MCP servers and containers it started. For a fast stop send {"type":"interrupt"} first, then close stdin: the running turn ends cancelled and the worker drains immediately instead of waiting the turn out.
Daemon
infer daemon is the long-lived hub every external client connects to. One process owns the outside world: the AG-UI WebSocket binding that the desktop app and the OpenTask browser extension dial into, the messaging channels, the scheduler, the heartbeat, and the A2A server peer agents task it through. Clients do not spawn infer headless themselves - they ask the daemon for a thread, and the daemon runs it.
desktop app -----+
                 +--> AG-UI WebSocket binding ----+
extension -------+                                |
                                                  +--> infer daemon --> session worker per thread
Telegram channel ----------------------------------+                    (project dir + conversation)
                                                  |
scheduler / heartbeat ----------------------------+
                                                  |
                                                  +--> one log: ~/.infer/logs/daemon-<date>.log
Note: The binding, the session workers and the client handshake described here are the daemon hub. Older CLI builds connect the extension directly to
infer chatand spawn oneinfer headlessper desktop prompt; see Connecting the extension for what changes on the client side.
What the daemon runs
| Subsystem | What it does |
|---|---|
| Binding | Serves ws://127.0.0.1:<port>/ws (default 52789) for the extension and the desktop app, behind an Origin check and a token. On its own daemon.binding.enabled switch |
| Session workers | One long-lived infer headless --serve process per thread, spawned in the thread's project directory, speaking AG-UI over stdio |
| Channels | Telegram and other messaging channels, each sender mapped to its own thread |
| Scheduler | Cron jobs from the local scheduler backend, run as threads instead of one-off processes |
| Heartbeat | Periodic self-checks and the artifact poller that pulls conversations back from the GitHub backend |
| A2A server | Serves this agent to peer agents over A2A, one headless run per task. Off by default, on its own a2a.server.enabled switch - see hosting an A2A server |
| Logging | Collects worker, one-shot job, channel and connection logs into one daemon log |
Starting the daemon
infer daemonThe daemon boots with the binding alone - channels, the scheduler and the heartbeat are optional and enabled through configuration. The binding has its own switch in the daemon.yaml sidecar, so a client that never touches the browser (the desktop app, a channel) can reach the daemon without enabling browser_use:
# ~/.infer/daemon.yaml
binding:
  enabled: true
  port: 52789 # optional; falls back to browser_use.extension.port
  token: <shared secret> # optional; falls back to browser_use.extension.token
The binding listens when daemon.binding.enabled is true, or - as before - when browser_use.enabled is true with backend: extension. Port and token resolve the same way in both cases: the daemon.yaml value wins, and ~/.infer/browser_use.yaml stays the fallback.
# ~/.infer/browser_use.yaml
enabled: true
backend: extension
extension:
  port: 52789
  token: <shared secret; infer init seeds one>
With neither token set the daemon refuses to boot rather than serving an unauthenticated socket - set daemon.binding.token, or browser_use.extension.token as the fallback. The browser extension relay is separate from the binding: it attaches only with browser_use.enabled and backend: extension. With the binding on through daemon.yaml alone, clients get threads but browser tools have nothing to drive.
Every field has an INFER_DAEMON_-prefixed environment override:
| Variable | Maps to |
|---|---|
INFER_DAEMON_BINDING_ENABLED | daemon.binding.enabled |
INFER_DAEMON_BINDING_PORT | daemon.binding.port |
INFER_DAEMON_BINDING_TOKEN | daemon.binding.token |
A standalone infer chat or infer headless with backend: extension reaches the browser as a daemon client (client: "browser" in the handshake), and starts infer daemon itself on the first browser call when nothing is listening on the port. Neither binds the port, so nothing has to hand it back.
The daemon needs the binding port to be free: if another process already holds it, the boot fails with the port named instead of retrying until it frees. Stop whatever holds it, or change the port.
A loopback listener for the extension when the binding requires client certificates. A browser extension dials a plain ws://127.0.0.1:<port>/ws and cannot present a client certificate, so a binding that requires one - the shape the operator serves in a pod - would shut it out. With the extension backend on and such a binding, the daemon therefore also listens on plain 127.0.0.1:<browser_use.extension.port> for the extension alone. It uses the extension token, the same handshake and the same origin check, and serves none of the binding's HTTP routes, so the web terminal, the screen, the artifacts and the peer A2A endpoint stay behind mutual TLS. Every other configuration keeps its single listener.
The extension port must differ from the binding port, including an unset daemon.binding.port that falls back to it, and the extension token must be set - either one unmet fails the boot with the reason. Available from infer v0.251.0.
Workspace lifecycle and cleanup
A workspace is where a session's agent runs. This daemon is one, named by workspace (default the hostname), and daemon.yaml registers the others. infer daemon teleport <conversation-id> --to <workspace> sends a session to another one between turns, and teleporting it back to this machine ends with the session home again:
# ~/.infer/daemon.yaml
workspace: laptop
idle_exit: 0s
away_exit: 1m
workspaces:
  - name: k8s-dev
    kind: kubernetes
    idle_ttl: 2h
    away_ttl: 1m
retention: 168h| Field | Default | Environment | What it does |
|---|---|---|---|
idle_exit | 0s | INFER_DAEMON_IDLE_EXIT | Stops a daemon that had no thread and no client for that long. Zero keeps it running, except for a daemon a client starts on demand, which stops after 30 minutes |
away_exit | 1m | INFER_DAEMON_AWAY_EXIT | Stops a daemon sooner once every session that teleported to it left again and it had no thread and no client for that long. It only shortens idle_exit - it never stops a daemon without one, and 0 turns it off |
workspaces[].idle_ttl | - | - | The idle_exit a kind: kubernetes workspace passes to its pod daemons |
workspaces[].away_ttl | 1m | - | The away_exit it passes to its pod daemons. Set it to the same value as idle_ttl to keep a pod up for the full idle_ttl after its session left |
workspaces[].retention | - | - | How long the operator keeps a suspended Orchestrator, its Sandbox, volumes and Secret before deleting them |
A session that teleported away counts as done even if it never ran on the pod, so a pod daemon whose sessions all left idles out after away_ttl rather than the full idle_ttl, as long as no client is attached. It reports its agents done, the operator suspends the Orchestrator, and the retention countdown starts. Teleporting the session to that workspace again before the retention runs out resumes the Orchestrator with its volumes, which clears the countdown.
A Gateway the Orchestrator links to by name is scaled down and up with it: the operator parks it at zero replicas while every Orchestrator referencing it is suspended, keeping its Deployment, Service and Secrets, and scales it back up as soon as one resumes. See Linking the orchestrator to a Gateway.
The daemon remembers the workspace a session came home from in ~/.infer/daemon/runtimes/, so stopping the session also cleans up behind it:
infer daemon stop <conversation-id>It stops the agent and deletes its remote runtime, including one the session already left - useful when the runtime waits on an approval or ended in an error, since a pod in that state keeps its Orchestrator until it is stopped.
Threads
A thread is a project directory plus a conversation id, and it runs in exactly one session worker:
- A client opens a thread with
new_sessionorresume_conversation, passingproject_dirand the thread options (model, agent mode, system prompt and custom instruction overrides, sandbox directories, max turns, and a named Markdown agent). The daemon answers with aMESSAGES_SNAPSHOTof the restored history. threadIdon the thread's runs is its conversation id, so a client can list and resume the same conversations the CLI resumes.- Every agent turn is one run:
RUN_STARTED, then exactly oneRUN_FINISHEDorRUN_ERROR. A stopped turn ends asRUN_FINISHEDwith outcomecancelled. - Several clients may subscribe to one thread; each of them sees the same frames.
- Idle workers exit after a timeout, and a worker that crashes mid-turn has its open run closed with
RUN_ERROR.
Opening a thread as a named agent
A client can open the thread as one of the project's Markdown agents by sending agent with the open frame, instead of spelling out a system prompt, a model and a tool allowlist itself:
{
  "type": "new_session",
  "project_dir": "/home/me/code/my-app",
  "agent": "code-reviewer"
}
The daemon resolves the name against project_dir and the home directory when it creates the thread, and the thread then runs with:
- the agent's Markdown body as its system prompt. A
custom_instructionsoverride still appends on top of it - the front-matter
modelas the model the thread opens with. An agent that names none, or namesinheritor a bare alias, keeps the model the client asked for. A laterselect_modelswitches the thread like any other - the agent's
toolsanddisallowedToolsas the worker's tool restriction, the same way a named subagent's allowlist binds its subagent. The thread'smodeis not derived from the list, somodeandset_modekeep control
The lookup order is the one skills and custom tools already use - project first, then home, first match wins:
.infer/agents/<name>.mdin the project directory.agents/agents/<name>.mdin the project directory~/.infer/agents/<name>.md~/.agents/agents/<name>.md
An unknown name fails the open with a RUN_ERROR naming the agents that are available, so a client never gets a silently plain thread instead of the agent it asked for.
The resolved options travel as the thread's options, carrying the tool lists and never the agent name. A relayed open or a teleport therefore keeps the agent's restriction on the peer, which does not need a copy of the agent files.
Workspace kinds
A workspace is where a session's agent runs. The daemon you type into is one, and daemon.yaml registers the others, so a session can be teleported to a beefier machine or into a Kubernetes cluster between turns. A kind: kubernetes workspace runs each session as an operator Orchestrator in namespace, with the agent inside a pod.
The cluster or machine a workspace runs on is compute, written down once in ~/.infer/compute.yaml, and a workspace names it with compute:
# ~/.infer/compute.yaml
clusters:
  - name: k3d-agents
    context: k3d-agents
    namespace: agents
    mode: standard # standard (default) or all-in-one
    gateway_env:
- ANTHROPIC_API_KEY # the gateway gets the key, the agent never sees it# ~/.infer/daemon.yaml
workspace: laptop
workspaces:
- name: laptop
kind: local
- name: code-reviewer
compute: k3d-agents
protocol: agui # agui (default) or a2a
image: ghcr.io/inference-gateway/cli:latest
storage: 5Gi
forward_env:
- GITHUB_TOKEN # the agent itself needs this one
secrets:
- code-reviewer-credentials # every key of this Secret becomes a variable of the pod
- name: release-manager
compute: k3d-agents
image: ghcr.io/inference-gateway/cli:latest
secrets:
- release-manager-credentialsA workspace on compute takes its kind and its connection from it, and keeps what describes the computer itself: image, storage, protocol, idle_ttl, env, forward_env, secrets and mcp_servers. Setting kind, or any key its compute already sets, fails at startup, and so does naming compute compute.yaml does not define.
One Gateway per cluster. Every standard-mode workspace on one cluster shares that cluster's Gateway and credentials Secret instead of each deploying its own, and the last session to go takes them along. The namespace belongs to the cluster too, because an Orchestrator only references a Gateway in its own namespace.
A workspace that carries its own connection keeps working exactly as before, with a Gateway of its own:
workspaces:
  - name: k8s-dev
    kind: kubernetes
    context: k3d-infer-workspaces
    namespace: infer-workspaces
    image: ghcr.io/inference-gateway/cli:latest
    mode: standard
    gateway_env:
- ANTHROPIC_API_KEYmode, gateway_env, secrets and mcp_servers apply to Kubernetes workspaces only and are rejected on any other kind. infer daemon workspaces prints the compute each workspace runs on in a COMPUTE column.
How the daemon dials a workspace (protocol)
protocol is how this daemon talks to the workspace's own daemon, on every kind. agui (the default) rides the AG-UI WebSocket binding, and a2a carries the same teleport vocabulary over A2A JSON-RPC on the same listener - see the A2A peer endpoint. A workspace whose daemon serves nothing over its chosen protocol fails a teleport at the provisioning stage, before anything is created, so a kind: kubernetes workspace on a2a needs an image new enough to serve /a2a.
infer daemon workspaces prints the choice in a PROTOCOL column, and the chat TUI names it next to the workspace: in the /workspaces picker, in the status bar indicator (⇄ k8s-dev (a2a)) and on the teleport progress line.
Where the gateway runs (mode)
mode says where a Kubernetes workspace runs the gateway its agents call, and gateway_env names the variables that gateway gets, typically provider keys. Both are set on the cluster in compute.yaml for a workspace that names its compute, and on the workspace itself for one that carries its own connection.
| Mode | What it deploys |
|---|---|
standard (default) | One operator Gateway per cluster, beside its sessions, shared by every workspace on that cluster. Each teleport writes the gateway_env values into the gateway's Secret and the pod only learns the gateway's URL, so nothing the agent runs can read a key into its context. A teleport waits for the gateway to serve before it restores the session |
all-in-one | Nothing beside the pod. A teleport seals the gateway_env values along with forward_env and the pod's workers run the gateway themselves on 127.0.0.1:8080. One pod less, but the keys sit in the agent's environment |
In standard mode the Gateway and its Secret are owned by every session's Orchestrator, so they are garbage-collected with the last session. Without gateway_env no gateway is deployed at all and the pod calls whatever INFER_GATEWAY_URL names.
Use gateway_env for credentials only the model calls need, and forward_env for credentials the agent itself needs - a GITHUB_TOKEN it pushes with, for example. forward_env values never land in a Kubernetes object, but the agent can read them, which is exactly why provider keys belong under gateway_env.
Where the keys come from
A teleport resolves every gateway_env and forward_env name the way the local gateway does: the teleporting daemon's environment first, then ~/.infer/auth.yaml. Nothing is read from the cluster.
- A name the daemon resolves no value for keeps the value an earlier teleport wrote into the Secret, so an unset variable never blanks a working gateway.
- A name no longer listed in
gateway_envis dropped from the Secret. - A changed value rolls the gateway. An unchanged one does not, so a new session shares the running gateway pod without a rollout.
Credentials the cluster already holds (secrets)
secrets lists Secrets that already exist in the workspace's namespace. Every key of each one becomes a variable of the pod's daemon through a secretKeyRef, so the agent's computer holds its own credentials and the values never pass through the machine that opens the thread. The keys are read when a session's Orchestrator is created, and a Secret that is missing fails the teleport before anything is created.
Give each agent a workspace of its own and each workspace its own Secret, and an agent only ever has the credentials that are its own:
# ~/.infer/daemon.yaml
workspaces:
  - name: code-reviewer
    kind: kubernetes
    namespace: agents
    image: ghcr.io/inference-gateway/cli:latest
    secrets:
      - code-reviewer-credentials
  - name: researcher
    kind: kubernetes
    namespace: agents
    image: ghcr.io/inference-gateway/cli:latest
    secrets:
- researcher-credentialskubectl create secret generic code-reviewer-credentials \
--namespace agents --from-literal=AGENTMAIL_API_KEY=...That makes secrets the fourth way a Kubernetes workspace gets a value, and they differ in who can read it:
| Field | Where the value lives | Who reads it |
|---|---|---|
env | Plain text in the Orchestrator object | The agent, and anyone who can read the object |
gateway_env | The gateway's Secret, written by each teleport | The gateway only, not the agent |
forward_env | Sealed from this machine on each teleport, never a cluster object | The agent |
secrets | Secrets the cluster already holds, referenced by the pod | The agent, and never this machine |
A hosted MCP server is the usual reason to want one: put the key in the workspace's Secret and have mcp.yaml expand it from the pod's own environment, and name the server under mcp_servers.
MCP servers for the pod (mcp_servers)
mcp_servers names hosted servers of this machine's ~/.infer/mcp.yaml that the workspace's pods get. Each named server goes into the session's Orchestrator with its name, URL, headers, include_tools, exclude_tools and timeout, and the operator writes it into the pod's own mcp.yaml, so the agent in the pod connects it like any other server.
Headers are forwarded exactly as written, never expanded on this machine, so a ${VAR} stays a reference the pod expands from the variables its secrets give it - the credential itself never lands in a Kubernetes object:
# ~/.infer/mcp.yaml
servers:
  - name: example
    enabled: true
    url: https://mcp.example.com/mcp
    headers:
      x-api-key: ${MCP_EXAMPLE_API_KEY}
    include_tools:
      - search
    timeout: 10
A server's tool filters and timeout travel with it, so the agent in the pod gets the same tools of that server as this machine does: include_tools, exclude_tools and timeout are taken from mcp.yaml as written. A timeout of 0 or less is left unset in the pod, which gives it the pod's own default.
# ~/.infer/daemon.yaml
workspaces:
  - name: code-reviewer
    compute: k3d-agents
    image: ghcr.io/inference-gateway/cli:latest
    secrets:
      - code-reviewer-credentials # holds MCP_EXAMPLE_API_KEY
    mcp_servers:
      - example
A server's own enabled says whether this machine's chats use it, and mcp_servers is separate: a server the laptop leaves off can still go to the pods, which is the usual shape for a server only the cluster reaches.
What is refused, before the Orchestrator is created, so nothing half-configured is ever applied:
| The entry | What happens |
|---|---|
A header holding a value rather than a ${VAR} reference | The teleport fails with the server and the header named, never the value, so no secret is written into the cluster |
A container server (run: true) | Refused - it runs on this machine, and only a hosted server reaches the pods |
A name mcp.yaml does not have | Refused, naming the server and the file |
mcp_servers on any kind other than kubernetes | Fails at startup, along with mode, gateway_env and secrets |
A prefix before the reference is fine, so a Authorization: Bearer ${TOKEN} header is forwarded as written.
The servers are read when a session's Orchestrator is created, so an edit reaches the next session and running ones keep theirs. It needs the operator and image versions under Kubernetes prerequisites.
Software the image does not ship (user_data)
A computer-use workspace usually needs software its image does not carry, a browser being the usual one. Rather than a custom image per client, a kind: kubernetes workspace takes user_data: a cloud-init user-data script the pod runs as root when it boots, before the daemon starts, the way a cloud VM runs it.
# ~/.infer/daemon.yaml
workspaces:
  - name: ubuntu-desktop
    kind: kubernetes
    namespace: agents
    image: ghcr.io/inference-gateway/computer:latest
    user_data: |
      #!/bin/sh
      set -e
      apt-get update
apt-get install -y --no-install-recommends gimp- The script must start with
#!- a#cloud-configdocument is not supported yet, and a script without the shebang fails at startup. - An application the script copies into
/etc/xdg/autostartopens at boot, which is how a workspace gets a browser on the screen without the agent launching one. - Its output goes to
/var/log/cloud-init-output.login the pod, so a failed install is read there rather than from the daemon log. - The script never lands in the Orchestrator. It goes into the session's Secret under the key
userdata- the key KubeVirt'scloudInitNoCloudvolume reads - and the Orchestrator only points at it throughspec.userData.secretRef. Like an instance's user-data it is fixed for the session's lifetime. user_datais Kubernetes-only, and setting it on any other kind fails at startup along withmode,gateway_env,secretsandmcp_servers.
The operator runs the pod as root in a user namespace, so that root is an unprivileged user on the node - see Boot a computer with user-data for the security context and the node requirements. It needs operator v0.35.0 or newer - an older one fails the create, and the error names v0.35.0. The field itself is read from infer v0.251.0.
The image built for this is the computer image, which runs the seed script itself.
Volumes the sessions share (volumes)
A session's own storage starts empty and user_data runs again on every boot, so a heavy application is installed again on each machine and sessions had no way to share content. volumes mounts PersistentVolumeClaims that already exist in the workspace's namespace into every session's pod, so an installed application and the material the agents work on both outlive the pod:
# ~/.infer/daemon.yaml
workspaces:
  - name: ubuntu-desktop
    kind: kubernetes
    namespace: infer-workspaces
    image: ghcr.io/inference-gateway/computer:latest
    volumes:
      - name: resolve
        claim: davinci-resolve
        mount_path: /opt/resolve
      - name: footage
        claim: raw-footage
        mount_path: /mnt/footage
read_only: true| Field | Description |
|---|---|
name | Volume name inside the pod, unique in the workspace. |
claim | Name of an existing PersistentVolumeClaim in the workspace's namespace. |
mount_path | Absolute path the claim is mounted at. |
read_only | Mount the claim read-only. Defaults to false. |
read_only: true is for content an agent copies into /workspace before it changes it, so the original stays as it is - source footage, a dataset, a reference corpus. Leave it unset for a volume the pod writes to, an installed application's directory or a cache.
A session never owns a claim. The claim is created and filled outside the session, and stopping the session or letting its retention run out leaves the claim and its data in place. Removing one is a deliberate kubectl delete pvc.
- Only a
kind: kubernetesworkspace takesvolumes, and setting it on any other kind fails at startup, along withmode,gateway_env,secrets,mcp_serversanduser_data. - The operator refuses a
mount_paththat is, or lies under,/workspace,/home/infer/.infer/projectsor/var/lib/cloud/seed/nocloud- the paths the pod manages itself. - A claim that does not exist leaves the pod unscheduled, reported on the Orchestrator with the scheduler's own message.
- A
ReadWriteOnceclaim is shared by pods on one node only, so sessions spread over several nodes need aReadWriteManyorReadOnlyManyclaim.
Like user_data, the list is fixed when a session's Orchestrator is created, so a change reaches the sessions teleported after it and running ones keep theirs. It needs operator v0.36.0 or newer - an older one fails the teleport with an upgrade message naming that version. The field the workspace fills is spec.sandbox.volumes.
Kubernetes prerequisites
The cluster needs the operator (v0.28.1 or later), agent-sandbox, and the Gateway API CRDs the operator requires. Install agent-sandbox first, because the operator looks for it only when it starts.
user_data needs an operator at v0.35.0 or newer, the release that boots a Sandbox from a user-data Secret, on nodes that satisfy its user-namespace requirements.
volumes needs an operator at v0.36.0 or newer, the release that mounts existing claims into a session's pod.
mcp_servers needs more than that: an operator that renders spec.mcp.servers, v0.33.0 or newer, and a pod image of v0.248.0 or newer, the infer release whose mcp.yaml reads a url with headers. A server that sets include_tools, exclude_tools or timeout needs the operator at v0.34.0 or newer, the release that renders those fields - a server without them still runs on v0.33.0. An older operator fails the create, and the error a workspace with mcp_servers prints names v0.34.0.
The operator deploys a Gateway only in a namespace matched by its WATCH_NAMESPACE_SELECTOR, inference-gateway.com/managed=true by default, so label the workspace's namespace for standard mode:
kubectl label namespace infer-workspaces inference-gateway.com/managed=trueYour kubeconfig user needs, on top of the permissions a teleport already uses (get, list, create, patch, delete on orchestrators.core.inference-gateway.com and create on pods/portforward):
| Resource | Verbs |
|---|---|
gateways.core.inference-gateway.com | get, create, update |
deployments | get |
secrets | update |
The session-teleport example
The CLI repo's examples/session-teleport runs this end to end on k3d. Its k8s-cloud workspace teleports a session onto ollama_cloud/glm-5.3-flash with gateway_env: [OLLAMA_CLOUD_API_KEY], the key taken from the teleporting daemon's environment or ~/.infer/auth.yaml, and its namespace carries the inference-gateway.com/managed=true label the operator looks for.
Its k8s-mcp workspace gives its pods the example's demo MCP server through mcp_servers: the server's x-api-key is written as a ${DEMO_MCP_KEY} reference in the laptop's mcp.yaml, the pod expands it from the Secret its secrets name, and infer mcp status in the pod lists the server as connected. Its include_tools passes only get_time and calculate to the pod, so the walkthrough installs the operator at v0.34.0. The laptop's own chats leave that server off, since only the cluster reaches it.
Its k8s-desktop workspace records the browser scenario it runs, and both ways of getting a recording out of the pod are set up there: /artifacts in the chat TUI to grab one file onto your machine, and an upload hook that mirrors every finished run's artifacts to a RustFS bucket for the bulk path.
Clients and the handshake
The client dials in and sends the first frame within 5 seconds:
{
  "type": "browser_hello",
  "token": "<shared secret>",
  "client": "extension",
  "extension_version": "1.9.2"
}{ "type": "browser_hello_ack" }clientisextension,desktop, orbrowserfor a CLI process that connects only to drive the browser; an absent or unknown value counts asextension. There is one extension connection - a new one replaces the previous, because MV3 service workers restart at will - and any number ofdesktopandbrowserconnections.- Any valid-token hello is accepted.
- Only
chrome-extension://,moz-extension://,safari-web-extension://or absentOriginheaders are accepted.
Shared event stream
Every transport carries the same vocabulary, with no envelope around it: AG-UI events go out with an uppercase type, app frames come in with a lowercase type. The frames on a session worker's stdio (infer headless --format ag-ui) and on the daemon socket are identical, so a client written against one works against the other.
AG-UI events out:
| Event | When |
|---|---|
RUN_STARTED | A turn starts; threadId is the conversation id |
MESSAGES_SNAPSHOT | Answer to new_session / resume_conversation; also emitted right after RUN_STARTED on a resumed run |
TEXT_MESSAGE_START / TEXT_MESSAGE_CONTENT / TEXT_MESSAGE_END | Assistant or user message, role on START |
TOOL_CALL_START / TOOL_CALL_ARGS / TOOL_CALL_END | A tool call the assistant issued |
TOOL_CALL_RESULT | The raw JSON execution result of a tool call |
STATE_SNAPSHOT / STATE_DELTA | The run state object - todos, usage, backgroundTasks, nextStepSuggestion and screenRecording |
ACTIVITY_SNAPSHOT | Progress a client keeps as one entry per messageId: agent_status, judge_verdict, computer_use |
RUN_FINISHED | The turn ended; outcome cancelled when it was stopped, result carries the session totals |
RUN_ERROR | The turn failed, or its worker died |
CUSTOM events out, each with a name and a value:
| Name | Value |
|---|---|
approval_request | tool_name, tool_args, tool_call_id - a tool call is waiting |
approval_resolved | tool_call_id - somebody else answered it |
user_question_request | tool_call_id and the AskUserQuestion form's questions |
agent_status | A local A2A agent starting: name, state, message, pull progress done/total |
background_tasks | running plus the jobs array (id, kind, label, description, detail, status) |
queued_message | A background job landed its note into the conversation |
token_usage | The same cumulative stats as RUN_FINISHED.result, after each model request |
judge_verdict | Per judge decision: tool, decision, reason, model, turn |
computer_use_paused / computer_use_resumed | request_id - answer to a computer_use_control frame |
browser_extension_status | connected, extension_version, protocol_version - on extension connect and disconnect |
browser_use_paused / browser_use_resumed | request_id - answer to a browser_use_control frame |
App frames in:
| Frame | Purpose |
|---|---|
new_session / resume_conversation | Open a thread in a project directory, optionally as a named agent |
user_message | Send a message into the thread; queued when the agent is busy |
interrupt | Stop the streaming turn, which ends cancelled |
approval_response | tool_call_id, approved, scope - the decision for a pending tool call |
user_question_response | The collected answers, or a dismissal |
computer_use_control | action is pause or resume, for computer use |
list_conversations / list_history | Browse the project's stored conversations |
list_skills / list_models / select_model / set_mode | Inspect and change what the thread runs with |
list_shortcuts | The project's shortcut registry, for the / menu |
list_issues | The project's recent open issues, for the # autocomplete |
list_files | The project's files, for the @ autocomplete |
list_tasks / cancel_task | List and stop a session's background jobs |
tool_request / tool_result | Run a tool directly, scoped to a project directory |
list_artifacts / read_artifact | List a session's artifacts and read one |
Unknown type and name values are ignored on both sides, so the vocabulary stays additive. The full per-event reference lives with the CLI source, in docs/ag-ui-output.md.
Approvals
Approvals have one contract on every transport. The daemon sends CUSTOM approval_request to every client of the thread, and the first approval_response wins - it goes to the worker, and the thread's other clients get CUSTOM approval_resolved with the same tool_call_id so they can clear their prompt. A decision made in the terminal resolves the panel's prompt the same way. A response for an unknown or already-answered tool_call_id is ignored.
Browser use through the daemon
There is one real browser, so only the daemon binds the extension port. browser_command lines from the session workers are routed to the extension connection and each browser_result goes back to its worker by id. Commands from every source - session workers, the desktop app and browser clients - are serialized rather than interleaved on the same tab, and a command a client posts on the socket is answered only on that connection. Every non-extension client is told the state of that connection by the browser_extension_status frame - on connect, and on each attach or detach. With no extension connected, browser tools fail with no browser extension connected on port <port>; a command the extension does not finish in time fails with timed out waiting for the browser extension to <action>. The command and result shapes are documented in the OpenTask bridge protocol.
Hosting an A2A server
The daemon can also face the other way: instead of only calling A2A agents, it serves this agent to peers over A2A. With a2a.server.enabled: true it hosts an ADK A2A server, and every task a peer sends runs as one headless run in the daemon's working directory - so the project's .infer/ config, tools, skills and sandbox apply to it.
# .infer/config.yaml
a2a:
  server:
    enabled: true
    host: 127.0.0.1 # default
    port: 8090 # default
    mode: standard # default - standard, plan, auto or auto-with-judge
# token: set it through INFER_A2A_SERVER_TOKEN, not here| Setting | Default | Environment variable | Description |
|---|---|---|---|
enabled | false | INFER_A2A_SERVER_ENABLED | Host the A2A server in infer daemon |
host | 127.0.0.1 | INFER_A2A_SERVER_HOST | Bind address. Loopback by default |
port | 8090 | INFER_A2A_SERVER_PORT | Bind port |
token | (empty) | INFER_A2A_SERVER_TOKEN | The bearer token every caller must present. Required when enabled |
mode | standard | INFER_A2A_SERVER_MODE | The agent mode served tasks run in |
The token is required: with the server enabled and no token set, the daemon refuses to boot rather than exposing an unauthenticated coding agent. It is a credential, so set it through INFER_A2A_SERVER_TOKEN (from .env, for example) instead of writing it into config.yaml. A loopback bind is not protection on its own - a local web page can reach 127.0.0.1. Treat mode: auto as handing unrestricted shell access to every holder of that token.
What a peer sees:
- The agent card at
/.well-known/agent-card.json, advertising onecoding_taskskill,text/plainin and out, no streaming and no push notifications, and the bearer scheme a caller needs. message/sendplustasks/get,tasks/listandtasks/cancel, with tasks kept in an in-memory store (nothing survives a daemon restart).- A one-at-a-time queue: tasks are accepted immediately but run one after another, never concurrently. Each run is bounded by
a2a.task.agent_mode_max_wait_seconds, so a hung run cannot hold the queue. tasks/cancelcancels the run itself and the task ends ascanceled.
A completed task's status message is the run's final assistant message. A task whose message carries file or data parts is refused - served tasks are text only.
Sessions: the A2A contextId becomes the session the run stores its conversation under, so a peer that reuses one contextId across tasks continues the same session and keeps the accumulated context. A contextId is limited to letters, digits, _ and - (up to 128 characters), because it becomes a storage key.
Served tasks always run with --prompt-only, so task text is never interpreted as a shortcut or a direct call.
The daemon log
One file holds the whole picture: ~/.infer/logs/daemon-<date>.log (logging.dir moves the directory). Everything the daemon starts logs JSON to stderr and keeps no log file of its own while supervised - session workers and the one-shot job runs (scheduled fires, heartbeat ticks) alike - and the daemon collects that stderr into its own log, each line tagged with the project_dir, conversation_id and worker_pid it came from. There is no per-process app-<date>.log to correlate.
Also in the same file:
| Logged | Fields |
|---|---|
| Client connects and disconnects | client |
| The browser extension relay's attach and detach | extension_version from the hello |
| Routing errors (unknown thread, dead worker, no extension) | project_dir and conversation_id of the thread they concerned |
| Channel, scheduler and heartbeat lines | project_dir and conversation_id when they act for a thread |
Logs are not streamed to clients, so tail the file when debugging a client:
tail -f ~/.infer/logs/daemon-$(date +%Y-%m-%d).logCompute
Compute is what sessions and models run on: Kubernetes clusters, standalone machines, and GPUs rented by the hour. It lives in ~/.infer/compute.yaml, apart from any daemon that uses it, because a cluster exists whether or not a daemon runs on it.
# ~/.infer/compute.yaml
clusters:
  - name: k3d-agents
    kubeconfig: ~/.kube/config # the default kubeconfig when empty
    context: k3d-agents # the current context when empty
    namespace: agents # required, shared by every workspace on the cluster
    mode: standard # standard (default) or all-in-one
    gateway_env:
      - ANTHROPIC_API_KEY
machines:
  - name: workstation
    address: workstation.lan:52789
    token: ${WORKSTATION_TOKEN}
    tls:
      ca_file: ~/.infer/daemon/workstation-ca.crt
gpus:
  provider: runpod
  gpu_type: NVIDIA GeForce RTX 5090
  model: ggml-org/gemma-4-E4B-it-GGUF:Q4_0
max_hourly: 1.50- A cluster holds the connection and the placement rules a
kind: kubernetesworkspace would otherwise repeat per workspace. A cluster name has to be a valid Kubernetes label value, because it labels the Gateway and the sessions of every workspace on the cluster. - A machine holds
address,tokenandtls, the connection of akind: daemonworkspace. Write the token as a${VAR}reference and the commands keep it as one. gpusholds the defaults and the hourly price cap for rented GPUs.
compute.yaml is read from the home directory only. A project's .infer/compute.yaml is ignored, because clusters and machines belong to the user, not to a project.
infer compute clusters and infer compute machines
add and remove edit compute.yaml as written, so a ${VAR} reference is saved back as a reference and never as the secret it names. remove refuses compute a workspace in daemon.yaml still runs on.
infer compute clusters add k3d-agents --context k3d-agents --namespace agents --gateway-env ANTHROPIC_API_KEY
infer compute clusters list
infer compute clusters status            # or: status k3d-agents
infer compute clusters remove k3d-agents

infer compute machines add workstation --address workstation.lan:52789 --token '${WORKSTATION_TOKEN}'
infer compute machines list
infer compute machines status
infer compute machines remove workstation| Command | Flags |
|---|---|
clusters add <name> | --namespace (required), --context, --kubeconfig, --mode (standard or all-in-one), --gateway-env |
machines add <name> | --address (required), --token, --ca-file, --cert-file, --key-file |
clusters status checks every cluster at once: whether it is reachable, whether it runs the operator, its Kubernetes version, and how many sessions the workspaces on it run. machines status probes each machine the way the daemon probes a kind: daemon workspace, over TLS with this daemon's identity. One unreachable entry never holds up the report on the others. machines list never prints a token.
infer compute gpus
infer compute gpus rents an on-demand cloud GPU running a llama.cpp server, so you pay only for the hours used. RunPod is the one provider today.
infer compute gpus provision --model "bartowski/Qwen2.5-7B-Instruct-GGUF:Q4_K_M" -y
infer compute gpus list
infer compute gpus status <instance-id> --wait
infer compute gpus destroy <instance-id> -y| Command | What it does |
|---|---|
provision | Provision an instance. Without --gpu-type it opens an interactive picker with live pricing, cheapest first, then waits until the model answers |
list | List the instances infer provisioned, with status, hourly cost and uptime |
status <instance-id> | State, uptime, hourly cost, estimated total and the endpoint. --wait blocks until llama.cpp answers |
destroy <instance-id> | Destroy an instance, which stops billing |
provision takes --gpu-type <id>, --model <repo>:<quant> (a Hugging Face GGUF) and -y, --yes to skip the confirmation. destroy takes -y, --yes.
A ready instance is handed over through the standard llamacpp provider variables, which makes it indistinguishable from any other llamacpp backend:
LLAMACPP_API_URL=https://<instance>-8080.proxy.runpod.net/v1
LLAMACPP_API_KEY=<token generated for the instance>
The key is generated per instance and passed to llama.cpp as its --api-key, so the server is not open to whoever finds the URL. Point the gateway at the two values and the model is just another one in the catalogue - see the llama.cpp provider.
The RunPod API key is management-plane only, used for the create, list and destroy calls. It is read from RUNPOD_API_KEY in the environment or ~/.infer/auth.yaml, and asked for and saved to auth.yaml on first use. The older provisioner block in config.yaml and its provisioner.runpod.api_key still work with a deprecation warning that points at compute.yaml and auth.yaml.
max_hourly is a spending cap. Provisioning fails before anything is created when the chosen GPU costs more per hour than gpus.max_hourly. A zero or absent cap allows any price. An instance keeps billing until it is destroyed, so infer compute gpus list is worth a look before you walk away.
infer gpustill works as a hidden, deprecated alias ofinfer compute gpus.
Web Terminal
The web terminal is this chat TUI in a browser tab, served by infer daemon over xterm.js. It exists so you can reach your sessions from a phone, a tablet or another machine without installing anything, and keep them running after the tab closes.
infer chat --webThe command starts the local daemon when none is listening, prints http://127.0.0.1:<port>/terminal/?token=<token> and opens it. Each tab runs one infer chat --daemon in a PTY on the daemon, which is the same client a terminal is. Click + for another tab and close one whenever you like: the session keeps running in the daemon, and infer chat --daemon --session-id <id> reattaches to it from a terminal.
browser (xterm.js) ── /terminal/ws ──┐
                                     ├── infer daemon ── PTY: infer chat --daemon ── session worker,
desktop app, extension ── /ws ───────┘                                              or the workspace that owns the session
Everything the daemon chat does applies to a tab, including /teleport <workspace>, which moves the tab's session to another machine or a Kubernetes pod between turns.
Where the Web Terminal Is Served
The page lives at /terminal/ on the daemon's binding listener, next to /ws, /artifacts/ and /a2a, so its host, port, token and TLS are the binding's (~/.infer/daemon.yaml, or the INFER_DAEMON_BINDING_* overrides). The daemon logs the URL as web terminal available when it starts.
The page sends the token once, in the first frame of each tab's socket, and keeps it in the browser's session storage after the first load, so a URL without the token works in the same browser session. A socket without the token, or without a verified client certificate when the binding requires one, is closed. A browser that cannot present the client certificate tls.mode: ca requires is served the page but opens no tab.
A binding on any host but loopback must serve TLS. Point binding.host at 0.0.0.0 with tls.mode: files and a certificate, then open the URL with this machine's address:
# ~/.infer/daemon.yaml
binding:
  enabled: true
  host: 0.0.0.0
  port: 52789
  token: <shared secret>
  tls:
    mode: files
    cert_file: ~/.infer/tls/server.crt
    key_file: ~/.infer/tls/server.key
The token grants every holder a shell as your user wherever the session runs, so treat it like an SSH key: keep the binding on loopback or a VPN interface, and never put it behind a proxy that strips TLS.
The Screen View
With Computer Use streaming on (computer_use.screenshot.streaming_enabled), the Screen button shows what the tab's session sees. The daemon asks the session's worker for its latest frame and serves it at /screen/?id=<session>, which the page polls every two seconds.
The frame comes from wherever the session runs, so after a /teleport to a desktop workspace the view shows that desktop, relayed through this daemon. Nothing else needs to be installed in the browser: the Screen view is a polled image, not a remote-desktop client.
How fresh that latest frame is depends on the worker's capture pace, not on the poll: outside a take-over the worker captures one frame every computer_use.screenshot.capture_interval seconds, 3 by default, so polling faster than that returns the same image.
An unchanged screen costs nothing to poll. Each image is served with its frame id as an ETag, and the page names the frame it already shows on the next poll, so a screen that has not changed answers 304 Not Modified and the picture on the page stays as it is instead of being downloaded again. A frame's id changes only when the picture does - a capture that shows what the latest frame already shows is not stored again, so a still screen keeps one frame however long it stands.
Take-over Mode
When the agent reaches a step only a person can do - a login, a two-factor code, a CAPTCHA, a cookie dialog the judge keeps rejecting - press Take over in the Screen view. The image takes focus, and clicks, drags, wheel and keys inside it drive the session's screen directly, with the poll dropping to 250 ms. Done, or Esc twice, hands the screen back.
What makes typing feel live is the capture pace, not the poll. While you hold the screen the worker captures twice a second instead of once per capture_interval, and takes one more frame right after each input you send. A frame read that follows an input waits up to one second for that capture, so the image you get back shows what the input did rather than the screen before it. After the hand-back the configured capture_interval applies again, so an idle computer does no more work than before.
| Step | What happens |
|---|---|
| Take over | The screen is claimed for you. A second claim, from another tab or viewer, is refused while you hold it |
| While you hold it | The agent is held: its input actions wait for the hand-back, its observations keep working, and every client sees who drives on the run state |
| Done | The screen is released and one continue message is queued, so the agent's next turn starts from a fresh screenshot of what you left behind |
An open approval box for a Computer call is resolved as rejected by the take-over, because you are about to do that step yourself. See Escalating a rejection for the other way an agent asks a person to step in.
The desktop app drives the same take-over from its Computers view, for an agent that runs on a workspace of its own - see Agent computers.
Dragging
A person holding the screen can press a button down, move, and release, so the steps a single click cannot do - dragging a window, moving a file, selecting text with the pointer, pulling a slider - are in reach. The screen_input kinds for it are mouse_down, which holds a button down at a position, and mouse_up, which lets it go at a position. Both take x, y and an optional button, left by default, or right or middle. A mouse_down, one or more move inputs and a mouse_up make a drag.
A button still held at the hand-back is released first, so the agent never gets the screen back mid-drag.
The agent's own Computer tool has no press and release: only a person's inputs during a take-over can hold a button down. Whether a client offers dragging is up to that client - the desktop app sends them from its Computers view.
Inputs During a Take-over Never Enter the Conversation
What you type while you hold the screen is yours alone. Those inputs drive the display directly, which means they create:
- no approval prompt - they are not tool calls
- no judge call - there is nothing for a judge to decide
- no conversation entry - a password or a one-time code typed during a take-over never reaches the transcript, the model's context or the session history
Only the frame the agent captures after the hand-back shows what changed, so keep a credential entry off the screen the agent will screenshot next if the page echoes it back in plain text.
Walkthrough: a Browser on a Remote Desktop
The CLI repository's examples/computer-use runs this end to end with Docker Compose and a mock model, so it needs no API key. Two daemons stand in for your laptop and a remote Linux desktop: laptop serves the web terminal, and desktop runs Xvfb with Chromium and Computer Use enabled, registered on the laptop as a kind: daemon workspace.
docker compose up --buildOpen the laptop's terminal URL, accept its self-signed certificate, click + for a tab, then:
/teleport desktop. The status bar flips to⇄ desktoponce the session lands there.- Click Screen. The view shows Chromium on the desktop container, refreshed every two seconds.
browse to example.com. The model takes a screenshot, clicks into the browser, pressesctrl+l, types the URL and pressesenter- each one aComputercall on the desktop, with the Screen view following along.- The run stops at the site's cookie dialog, which the agent cannot get past. Click Take over, dismiss the dialog yourself in the image, then click Done. The agent continues from a fresh screenshot of the page you left behind.
The same example also ships a real-model variant that runs the agent in Auto+Judge with a decision model approving each click.
Screen Protocol Frames
Integrators that drive the screen themselves use the same frames the web terminal does, on the daemon binding, authenticated with the binding's bearer token.
Read the latest frame:
{ "type": "read_frame", "project_dir": "/abs/path/to/project", "id": "<conversation id>" }{
"type": "frame",
"id": "<conversation id>",
"frame": {
"id": "f-1",
"timestamp": "2026-11-04T12:00:00Z",
"data": "<base64>",
"width": 1280,
"height": 800,
"format": "jpeg"
}
}A client that already holds a frame can name it with the optional have, the id of the frame it shows, and skip the transfer when nothing newer exists:
{
  "type": "read_frame",
  "project_dir": "/abs/path/to/project",
  "id": "<conversation id>",
  "have": "f-1"
}{ "type": "frame", "unchanged": true }The reply carries no frame in that case, so the client keeps the picture it has. Without have the full frame is sent as before.
The same listener takes the take-over over POST /screen/?id=<conversation id>, whose body accepts screen_control and screen_input:
{
  "type": "screen_control",
  "project_dir": "/abs/path/to/project",
  "id": "<conversation id>",
  "action": "take_over"
}{ "type": "screen_result", "id": "<request id>", "held": true }| Frame | Meaning |
|---|---|
read_frame | The latest frame of the screen the session's worker streams. With project_dir it runs on the thread of the session id names, relaunching that session's worker when it is not running. The optional have, the frame id the client shows, answers unchanged: true with no frame when the latest frame is still that one. error replaces frame when the worker streams no screen or captured nothing yet |
screen_control | action: take_over claims the screen and resolves an open Computer approval as rejected. A second claim while it is held errors. action: hand_back releases any button still held, releases the screen and queues the worker's continue message |
screen_input | One person input in the frame space the GET image answers in: {"kind": "move" | "click" | "double_click" | "mouse_down" | "mouse_up" | "scroll" | "type" | "key", "x", "y", "text", "combo", "button", "direction", "amount"}. mouse_down and mouse_up bracket a drag - see Dragging. It drives the display directly, with no approval, no judge and no conversation entry |
screen_result | One reply per request id, carrying held |
An input for a screen nobody holds errors, and the HTTP POST answers it with 409 Conflict, so a stale tab cannot drive what it handed back.
Computer Use
GUI automation and visual understanding capabilities for interacting with applications and desktop environments.
The computer image
ghcr.io/inference-gateway/computer is the published desktop a computer-use workspace runs, released with the CLI under the same tags (latest and <version>). It is a minimal Ubuntu 26.04 desktop:
infer daemonruns on a headless GNOME Shell session (Wayland, 1280x800) in Ubuntu mode, with the dock, the Yaru theme, Files, Terminal and Text Editor.- The session runs under a UTF-8 locale (
LANG=C.UTF-8), so the session D-Bus and every app it activates - gnome-terminal and the other GTK apps - render non-ASCII text instead of mangling it the way the POSIX locale does. DISPLAY=:0is set alongsideWAYLAND_DISPLAY=wayland-0, so X11-only applications reach Xwayland from the agent's Bash tool without exporting a display first.- No browser ships with it. Clients install what the agent needs with
user_datainstead of building an image of their own. - Closing an application leaves the agent on the desktop, not on a black screen.
The entrypoint is the container's stand-in for cloud-init: started as root it runs the seed script, then drops to the infer user and starts the desktop.
# ~/.infer/daemon.yaml
workspaces:
  - name: ubuntu-desktop
    kind: kubernetes
    namespace: agents
    image: ghcr.io/inference-gateway/computer:latest
    env:
      INFER_COMPUTER_USE_ENABLED: 'true'
    user_data: |
      #!/bin/sh
      set -e
      apt-get update
      apt-get install -y --no-install-recommends gimp
      cp /usr/share/applications/gimp.desktop /etc/xdg/autostart/
Copying a .desktop file into /etc/xdg/autostart is what opens that application when the computer boots. The image is published from infer v0.251.0.
GPU acceleration on a computer
Vulkan is on the image from infer v0.256.0: libvulkan1, mesa-vulkan-drivers and vulkan-tools. An app on a computer uses the host's GPU when the pod has one and renders on the CPU when it does not, with nothing installed through user_data first. vulkaninfo --summary on the computer reports which device an app gets.
On arm64 the Venus driver is built with a downstream change for the 16 KiB memory pages of an Apple silicon host, where the driver Ubuntu ships fails. amd64 keeps Ubuntu's driver.
The image does not give a pod a GPU by itself. Whatever runs the pod has to hand it the device - for the operator that is resources.limits on the Orchestrator, alongside the device plugin for your hardware. The desktop app's local cluster does not pass a device through yet.
A GPU does not make every app faster. Video decoding and encoding stay on the CPU in a Linux VM on a Mac.
Display Server Support
Automatic display server detection - no configuration needed:
| Platform | Supported Servers | Notes |
|---|---|---|
| macOS | Quartz (native), X11 (XQuartz) | Quartz automatically detected and used |
| Linux | X11, Wayland | Auto-detection handles both protocols |
| Windows | Native | No configuration required |
Display server type is automatically detected at runtime. No manual configuration required.
Computer Use Tools
Computer use exposes two tools: Computer, an action-based desktop tool, and GetLatestFrame, registered whenever a frame source exists (screenshot streaming, or a directory source under vision.sources).
Computer takes an action:
| Action | Description |
|---|---|
accessibility | Preferred first observation. Returns compact {role,label,state,bbox} elements from the accessibility tree. Read-only. |
press | Presses the first element whose label matches exactly, via its accessibility action - the cursor never moves. |
screenshot | Captures the screen, or a native-resolution region. Use when the accessibility tree is empty or insufficient. |
cursor | Reports the current pointer position. |
move, click, double_click, triple_click, scroll | Pointer control. |
type, key | Type text or send key combinations (Ctrl+C, Cmd+V). |
Targets. accessibility and press accept an optional target: frontmost (default), dock, menubar, pid:<N>, app:<name>, or a bare application name. Application identifiers are pid:<N> on every platform - the macOS bundle ID form is gone, as are the older GetFocusedApp and ActivateApp tools.
Coordinate space. Accessibility bounding boxes use the same frame coordinate space as screenshots and pointer actions, so an element's center can be passed straight to a click.
Pressing beats clicking. press is the reliable way to activate dock items, buttons, and menu titles: it drives the element's own accessibility action instead of aiming the pointer at a coordinate, and it takes no screenshot.
macOS Accessibility permission. The AX tools return elements only after infer is granted permission in System Settings > Privacy & Security > Accessibility. Without it - or on a helper crash, timeout, or unavailable tree - the tool returns screenshot fallback guidance to the agent rather than failing the run. The macOS bridge is pure Go (PureGo calling CoreFoundation, CoreGraphics, and AXUIElement) running in a short-lived helper process; there is no cgo, Swift, or Objective-C.
Linux and Windows. AT-SPI and UIA providers are not implemented yet: accessibility and press report unsupported; use screenshot there, while every other Computer action works normally.
Clipboard. Clipboard support is text-only; image clipboard was removed with the cgo-free rewrite.
Screen Recording
Two tools record the screen to an MP4 file (H.264, yuv420p - it plays in browsers and QuickTime):
RecordStart- begins a recording of the whole primary screen, a single window, or a region, and returns the output path and the captured rectangle. Recording continues in the background.RecordStop- finalizes the recording and returns the path, duration and file size.
Typical uses are an unattended audit trail of a computer-use run, and recording a tutorial or a bug reproduction while the agent drives the desktop.
Disabled by default. While
computer_use.recording.enabledisfalse, neither tool is registered, so they cost zero prompt tokens. Recording captures whatever is on your screen - that is why it is opt-in.
Recording lives under recording in .infer/computer_use.yaml (project) or ~/.infer/computer_use.yaml (user). It works on its own - computer_use.enabled is not required.
# .infer/computer_use.yaml
recording:
  enabled: true # register the RecordStart/RecordStop tools (default: false)
  max_duration: 120 # seconds; the recording stops and finalizes itself at this cap
  output_dir: '' # empty = recordings/ under the media root
  framerate: 24 # frames per second
Every key has an INFER_COMPUTER_USE_RECORDING_-prefixed environment variable that takes precedence over the YAML value.
| Config key | Environment variable | Type | Default | Notes |
|---|---|---|---|---|
computer_use.recording.enabled | INFER_COMPUTER_USE_RECORDING_ENABLED | bool | false | Feature flag - both tools are absent from the LLM payload when false |
computer_use.recording.max_duration | INFER_COMPUTER_USE_RECORDING_MAX_DURATION | int | 120 | Seconds; the recording finalizes itself at the cap. Must be positive |
computer_use.recording.output_dir | INFER_COMPUTER_USE_RECORDING_OUTPUT_DIR | string | recordings/ under the media root | Where MP4s are written, as <timestamp>.mp4; created on first use |
computer_use.recording.framerate | INFER_COMPUTER_USE_RECORDING_FRAMERATE | int | 24 | Capture frame rate. Must be positive |
Requirements. The recorder shells out to ffmpeg with libx264 and the platform's screen grabber, found on PATH - for example brew install ffmpeg (macOS) or apt install ffmpeg (Debian/Ubuntu). A minimal ffmpeg build without the encoder or the grabber cannot record.
| Platform | Grabber | Extra requirements |
|---|---|---|
| macOS | avfoundation | Your terminal app needs Screen Recording permission, plus Accessibility for window mode (System Settings > Privacy & Security) |
| Linux | x11grab | An X11 session. Wayland is not supported yet |
| Windows | gdigrab | None |
Capture modes. RecordStart takes an optional mode:
screen(default) - the entire primary display.window- a single window, selected bywindow:frontmost(default),app:<name>,pid:<number>, or a bare application name. This is the same target syntax as theComputertool.region- a rectangle, given asregionwithx,y,widthandheightin the frame coordinate space (the same space asComputerscreenshots and accessibility bounding boxes).
{ "mode": "screen" }
{ "mode": "window", "window": "app:Safari" }
{ "mode": "region", "region": { "x": 0, "y": 80, "width": 1280, "height": 720 } }
window mode captures the window's bounds at the moment the recording starts: anything drawn over that area is recorded too, and moving the window afterwards does not move the capture.
Behaviour. RecordStart returns the file path and the captured rectangle and leaves ffmpeg running in the background. RecordStop takes no arguments and returns the path, duration and size.
- One recording at a time, machine wide. While ffmpeg runs, the recording holds
~/.infer/run/screen-recording.lock. ARecordStartfrom any otherinferprocess - another chat, a Desktop app session, a channel run - fails with an error naming the owning pid, and the active recording is left alone.RecordStopwith nothing recording is an error too. - Self-finalizing. A recording stops and finalizes itself at
max_duration(120s by default);RecordStopstill returns that file. One that stops on its own - the cap, an ffmpeg exit, or a stop from/tasks- queues a note asking the agent to collect it withRecordStop. - Clean exit. On normal exit, Ctrl+C or SIGTERM the CLI finalizes an active recording and leaves no ffmpeg process behind. Call
RecordStopin the same session; channel and scheduled runs each start a fresh process. - Visibility. The chat status bar shows a
RECbadge while a recording runs, and the recording is listed in/tasksunder Screen Recordings as a background job of kindrecording. infer tools executerefuses both tools.
Approval. RecordStart always requires approval, except in auto-accept (auto) mode:
- In chat you get the usual approval prompt.
- In headless mode it follows
approval_behaviour: sent over IPC when the run has--require-approval, decided by the LLM judge inauto-with-judgemode, otherwise blocked.
RecordStop follows computer_use.approval: under never (the default) and destructive it runs without a prompt - it counts as an observation - and only always asks.
Headless and AG-UI hosts. A running recording is a background job, so infer headless waits for it (up to a2a.task.agent_mode_max_wait_seconds, 300s by default) instead of exiting and cutting it short. How the stop request reaches the recording depends on the caller:
- Desktop app and other stdin hosts send a
user_messageline on stdin, which reachesRecordStopin the same process. - Channel, scheduled and heartbeat runs do not forward follow-up messages into a running process, so there a recording runs until
max_durationand the agent collects the file afterwards.
With --format ag-ui (the format the desktop app consumes):
| Event | Payload |
|---|---|
STATE_DELTA on screenRecording - on RecordStart, RecordStop, or max_duration | active, plus path, region and frameWidth/frameHeight while it runs - see state |
STATE_DELTA on backgroundTasks | The recording appears among jobs with kind recording |
approval_request | RecordStart when the run has --require-approval; without an approver it is blocked |
A recording still running when the run ends is finalized after the terminal event, so no screenRecording patch with active: false follows it - clear the indicator on RUN_FINISHED or RUN_ERROR.
Screenshot Tool Features
Streaming Mode:
- Maintains circular buffer of recent screenshots
- Configurable buffer size (default: 60)
- Configurable capture interval (default: 3 seconds)
- Efficient memory management
- Fast access to recent captures
Image Optimization:
- Automatic resolution scaling to fit the target box (default: 1024x768), preserving the aspect ratio so coordinates map back to the screen
- JPEG compression with configurable quality (default: 85%)
- Reduces bandwidth and storage requirements
Region Selection:
- Full screen capture
- Custom region coordinates (x, y, width, height)
- Multiple monitor support
Visualizing Agent Activity
The desktop app is the visualization layer for computer use: it shows the live screen monitor, the on-screen action overlay, and the approval prompts driven by computer_use.approval. Run the CLI from the desktop app to watch a computer-use run as it happens.
The web terminal shows the same screen in a browser tab, from wherever the session runs: with computer_use.screenshot.streaming_enabled on, its Screen view polls the session's latest frame.
A person watching that view can also drive the screen directly, outside the tool layer, for the steps an agent cannot do on its own - see take-over mode. Their inputs create no approval prompt, no judge call and no conversation entry, so a credential typed during a take-over never enters the transcript.
The CLI's own macOS floating window was removed. The computer_use.floating_window config section and the INFER_COMPUTER_USE_FLOATING_WINDOW_* environment variables no longer exist - existing config files that still carry those keys keep loading, the keys are simply ignored.
Computer Use Configuration
Computer use has its own file, .infer/computer_use.yaml, seeded by infer init. It is off by default; missing keys fall back to the in-code defaults shown here.
# .infer/computer_use.yaml
---
enabled: true
approval: never # never | destructive | always
screenshot:
  enabled: true
  target_width: 1024
  target_height: 768
  format: jpeg
  quality: 85
  streaming_enabled: true # also registers the GetLatestFrame tool
  capture_interval: 3 # seconds between frames outside a take-over
  buffer_size: 60
  temp_dir: '' # empty = screenshots/ under the media root
rate_limit:
  enabled: true
  max_actions_per_minute: 60
  window_seconds: 60
capture_interval sets the worker's capture pace outside a take-over. While a person holds the screen the worker captures twice a second regardless of this value, and the configured interval applies again after the hand-back - see Take-over Mode.
Computer Use Approval
computer_use.approval decides which computer-use actions go through the approval gate before they run. It applies to both interactive chat and infer headless.
| Value | Behavior |
|---|---|
never | Default. Computer-use actions bypass the approval gate and run immediately. |
destructive | The observations accessibility, screenshot, and cursor bypass approval; press and the input actions require it. |
always | Every computer-use action requires approval. |
# .infer/computer_use.yaml
approval: destructiveexport INFER_COMPUTER_USE_APPROVAL=always- Env override:
INFER_COMPUTER_USE_APPROVALtakes precedence over the YAML value. - Fail closed: an unknown value is rejected at config load with a validation error, and if one ever reaches the approval policy it is treated as
alwaysrather than silently bypassing the gate. - Under
destructiveoralways, a headless run needs an approver reachable over IPC - otherwise the gated calls are blocked, same as any other approval-requiring tool. See Headless secure-by-default.
Safety and Rate Limiting
Rate Limiting:
- Default: 60 actions per minute
- Prevents runaway automation
- Configurable threshold
Safety Controls:
- Approval prompts in Standard Mode
- Auto-approve in YOLO mode
- Activity logging for audit trails
- Command execution monitoring
Best Practices:
- Use Standard Mode for initial exploration
- Enable logging for debugging
- Set appropriate rate limits
- Monitor activity logs
- Test in safe environments first
Example Use Cases
infer chat
> "Take a screenshot and analyze the error dialog"
> "Click the Submit button in the center of the screen"
> "Type 'Hello World' and press Enter"
> "Switch to the Terminal app and run ls command"
> "Find the Save button and click it"
Frame Sources and Vision Annotation
Frame sources feed images to the agent, and a pluggable annotator turns each frame into text so that cheap or text-only models (DeepSeek, small local models) can still work from what is on screen or in front of a camera.
- The built-in
screensource is computer-use screenshot streaming, registered whenever screenshot streaming is on. - Directory sources watch a folder and serve the newest image file by modification time - whatever your camera or capture process writes there.
GetLatestFramereads the current frame from a source. For an arbitrary image file on disk, a vision model usesReadand a text-only model usesImageDecode.
The annotator produces a scene summary plus a numbered element list with bounding boxes: a vision model gets the image, a text-only model gets the text. Annotation is a side-call through the gateway, so any vision model the gateway serves works - including a fully local one through Ollama, which keeps annotation offline.
# .infer/config.yaml
vision:
  annotator:
    enabled: true # default: false
    model: anthropic/claude-haiku-4-5-20251001 # any vision model your gateway serves
    max_tokens: 4096
    timeout: 120
  sources:
    camera-front:
      type: directory
      path: .infer/frames/front # wherever your camera process writes frames
      prompt: 'Describe the workbench and any visible part numbers.' # optional per-source override
      retention:
        max_files: 100
        max_age: 24h
With vision.annotator.enabled: true, GetLatestFrame defaults to annotated text output and ImageDecode adds a text description to the image it returns - no per-model configuration. ImageDecode itself is always available - it is the path for a text-only model, and for a text description on top of an image a vision model can already see (see Vision-capable models and ImageDecode). retention prunes the source directory after reads.
Not to be confused with the gateway-side gateway.vision_enabled flag, which is unrelated.
Tools & Capabilities
When tools are enabled, LLMs have access to a comprehensive suite across multiple categories.
Tool Categories
| Category | Tools | Description |
|---|---|---|
| File System | Read, Write, Edit, MultiEdit, Delete, Tree, Grep | File operations and search with safety controls |
| Command Execution | Bash, BashOutput, KillShell, ListShells, Wait | Allow-listed shell execution (including gh for GitHub), background shell control, and blocking wait for conditions |
| Web | WebSearch, WebFetch | Internet research and content fetching |
| Workflow | TodoWrite, Schedule, RequestPlanApproval, AskUserQuestion, RequestApproval, Memory | Task tracking, cron jobs, plan-mode approval, clarifying questions, judge-rejection escalation, and persistent cross-session memory |
| A2A Integration | A2A_QueryAgent, A2A_SubmitTask, A2A_QueryTask | Delegate to external specialized agents - see A2A |
| Local Subagents | Agent | Fan out short-lived local subagents in parallel - see Local Subagents |
| Computer Use | Computer, GetLatestFrame, RecordStart, RecordStop | Accessibility-tree reads, presses, screenshots, and pointer/keyboard control - see the Computer Use section above; screen recording is opt-in via computer_use.recording.enabled, see Screen Recording |
| Image | ImageGeneration, ImageEdit, ImageVariation | Generate, edit, and vary images using the configured image model - independent of the chat session model |
| Audio | TextToSpeech, TextToMusic, TextToSFX | Local speech synthesis and voice cloning - opt-in via text_to_speech.enabled, see Text-to-Speech; music composition and sound-effect generation through the gateway - opt-in via text_to_music.enabled and text_to_sfx.enabled |
| Video | TextToVideo, CreateAvatar | Prompt and lip-synced avatar renders through the gateway, plus avatar-library creation - opt-in via text_to_video.enabled and text_to_video.create_avatar, see Text-to-Video and Avatars |
| MCP | MCP_<server>_<tool> | Dynamically registered tools from MCP servers - see MCP |
| Custom | Any name you give them | Tools you add yourself with one YAML manifest per tool, run as a program with the arguments as JSON on stdin - see Custom Tools |
File System Tools
In Plan Mode, Write, Edit, MultiEdit and Delete execute only inside the scratchpad - every other path stays read-only until the plan is approved.
Read
Read a file from the local filesystem with an optional line range. Handles text files, PDFs and images.
- Parameters:
file_path(required, absolute or relative),limit(default 2000 lines),offset(default 1) - Approval: not required (read-only)
- Notes: lines longer than 2000 characters are truncated - output is returned in
cat -nformat
An image file - png, jpg, jpeg, gif or webp, or a file without an extension whose bytes are an image - is attached to the model's next message when the gateway lists image input among the model's modalities. The tool result carries the path and the pixel size:
Read image 1920x1080 screenshot.pngA text-only model, or a session with no image service, gets an error pointing at ImageDecode instead, which describes the image in words through the vision annotator:
This is an image and the model cannot see images. Use ImageDecode on the path to get a description of it.A missing file does not return a bare NOT_FOUND. The error appends up to five candidate paths so the next call can correct a typo or a wrong directory instead of retrying the same path: siblings of the nearest existing directory ranked by name similarity, plus - when no sibling carries the missing base name - files with that base name found under the allowed sandbox directory containing it.
NOT_FOUND: /home/user/project/internal/tools/reader.go

Did you mean one of:
  /home/user/project/internal/tools/read.go
  /home/user/project/internal/tools/read_test.go
  /home/user/project/internal/tools/registry.go
Write
Write content to a file on disk. Overwrites the existing file at the given path.
- Parameters:
file_path(required, absolute),content(required) - Approval: required by default
- Notes: if the file exists, the Read tool must have been used first; respects configured path exclusions (
.git/,*.env,.infer/)
Edit
Perform an exact string replacement in a single file.
- Parameters:
file_path(required),old_string(required - must match exactly and be unique unlessreplace_allis set),new_string(required - must differ fromold_string),replace_all(defaultfalse) - Approval: required by default
- Notes: the file must have been Read at least once in the conversation; indentation must be preserved exactly
MultiEdit
Apply a sequence of edits to a single file atomically - either all succeed or none are applied.
- Parameters:
file_path(required),edits(required array; each item hasold_string,new_string, optionalreplace_all) - Approval: required by default
- Notes: edits are applied in order, each operating on the result of the previous one - plan them so earlier edits don't invalidate later matches
Delete
Delete a file or directory. Wildcards are supported when enabled.
- Parameters:
path(required - supports patterns like*.txtortemp/*),recursive(defaultfalse),force(defaultfalse),format(textorjson) - Approval: required by default
- Notes: restricted to the current working directory for safety
Tree
Display a directory tree, similar to the Unix tree command.
- Parameters:
path(default.),max_depth(1-10, default 3),max_files(1-1000, default 100),respect_gitignore(defaulttrue),show_hidden(defaultfalse),format(textorjson) - Approval: not required
- Notes: uses the system
treebinary when available, otherwise falls back to a built-in implementation
Grep
Powerful regex search across files. Uses ripgrep when available, otherwise a built-in Go implementation.
- Parameters:
pattern(required regex),path(default cwd),glob(e.g.*.ts,**/*.tsx),type(e.g.go,py,rust),output_mode(content|files_with_matches|count, defaultfiles_with_matches),-i,-n,-A,-B,-C,multiline,head_limit - Approval: not required
- Backend: configurable via
tools.grep.backend(auto|ripgrep|go) - Notes: respects
.gitignore; auto-excludes.git,node_modules,.infer,vendor,dist,build,target
Command Execution
Bash
Execute a bash command that matches the active mode's allowed-list. Matching is default-deny: a command auto-runs only when it matches the allowed-list for the current agent mode. Anything unmatched falls through to an approval prompt in chat, or is rejected with an actionable hint in headless mode. There is no separate deny list.
- Parameters:
command(required),format(textorjson) - Approval: configurable via
tools.bash.require_approval
Per-mode allowed-list
The allowed-list is configured per agent mode under tools.bash.mode.<mode>.allow in ~/.infer/tools.yaml. The effective list for a mode is mode.all.allow (the every-mode baseline) unioned with that mode's own entries:
# ~/.infer/tools.yaml
tools:
  bash:
    enabled: true
    require_approval: false
    mode:
      all: # baseline applied in every mode
        allow:
          - ls( .*)?
          - pwd( .*)?
          - git status( .*)?
          - git diff( .*)?
      plan: # commands run pinned to the scratchpad - empty by default
        allow: []
      standard: # default interactive mode
        allow:
          - npm (install|test|run).*
      auto: # Auto-Accept / YOLO mode
        allow:
- .* # unrestricted sentinel- Default-deny. Out of the box only
mode.autoships the.*sentinel;mode.planandmode.standardadd nothing on top ofmode.all, so they reduce to the baseline. In plan mode those baseline commands run with their working directory pinned to the scratchpad, not the project - see the opt-in below. GitHub writes (gh issue/pr create|edit|comment),git push, andgit commitare not in the defaults - they fall through to approval until you add them. - Full-command matching. Each entry matches the whole command, so a bare token like
ghallows onlygh- nevergh issue list. Opt into arguments explicitly with a pattern (gh issue.*,npm (install|test|run).*); the default entries use a( .*)?suffix to allow trailing arguments. - The
.*sentinel means unrestricted: any single command runs and the clean-command guard below is skipped. It is the default formode.auto(chat's Auto-Accept mode, toggled with Shift+Tab) and is an explicit opt-in - never a headless default.
Since plan-mode commands run in the scratchpad on scratch copies, verification builds and tests are reasonable to let run unattended there:
# ~/.infer/tools.yaml - opt into unattended verification in plan mode
tools:
  bash:
    mode:
      plan:
        allow:
          - go build.*
          - go test.*
Allowed-list entries for commands that create paths (mkdir, ln -s) pass through the scratchpad gate as well, so an absolute path into the project falls through to approval instead of auto-running.
Clean-command guard
For every mode except the .* sentinel, each command passes a clean-command guard before the allowed-list is consulted. The guard rejects, regardless of the list:
- Command substitution -
$(...), backticks,<(...),>(...). - Multi-command chains and pipelines - a top-level
|,&&,||,;,&, or newline. Operators inside quotes don't count, sojq '.a | .b'stays a single command. (This closes the oldecho x | xargs rmprefix hole.) - File-write redirections -
>and>>. Benign stream redirects (2>&1,>/dev/null) are stripped first and remain allowed. - Dangerous
findactions --exec,-delete, and the like. A barefindfor read-only discovery is fine. - Environment-variable leaks - a printing or publishing command (
echo,printf,gh issue|pr create|comment|edit) may not expand$VAR. Soecho $AWS_SECRET_ACCESS_KEYis blocked, whilels $DIRstays allowed. A single-quoted or escaped$is treated literally.
A rejected command returns an actionable hint naming what tripped the guard; the model is told to stop and ask, or use an allowed alternative, rather than retry the same call.
Append-only override (CI)
The mode.all baseline takes an append-only override so CI can add a few safe commands without rewriting config or shipping .*:
# Comma- or newline-separated; the env var wins over the flag
export INFER_TOOLS_BASH_ALLOW_APPEND="git commit,git push"

# Flag form
infer headless "Release the changelog" --tools-bash-allow-append "git commit,git push"
The extra commands merge onto mode.all.allow, so they auto-run in every mode. There is no replace override - the old tools.bash.whitelist.commands key, the INFER_TOOLS_BASH_WHITELIST_COMMANDS[_APPEND] env vars, and the --tools-bash-whitelist-commands* flags were removed.
BashOutput, KillShell, ListShells
Background-shell management. These tools are only registered when tools.bash.background_shells.enabled: true.
- BashOutput -
bash_id(required),filter(optional regex). Returns only new output since the last read. - KillShell -
shell_id(required). Sends SIGTERM, then SIGKILL after 5 seconds if the shell doesn't exit. - ListShells - no parameters. Lists all running and recently completed background shells with their IDs, state, and elapsed time.
Approval: BashOutput and ListShells are read-only monitoring of shells the session already approved when it started, so they never ask - like Wait. That keeps follow-up reads working in unattended runs (CI, headless) where no approver is reachable. KillShell terminates a process and follows the normal approval rules.
Wait
Block inside a single tool execution until a condition is met (shells exit, file event, or check command succeeds), then return once with the outcome. Waiting costs zero chat completions - no LLM round-trip per iteration.
- Approval: not required (passive utility tool - no side effects)
- Enabled by default: yes (gated by
tools.wait.enabled) - Common parameters:
timeout_seconds(required, number) - maximum time to wait in seconds, bounded by the config ceiling (tools.wait.max_timeout_seconds, default 600)
Return value: A structured result with condition (the condition type), reason (outcome: condition_met, timeout, cancelled, check_failed, no_shells, error, not_allowed), elapsed_seconds (time spent waiting), and condition-specific details (exit codes, last output, shell states) - included even on failure so the model can see why the wait ended.
Cancellation: Pressing Esc in chat or session cancel interrupts the wait immediately (reason: cancelled).
Condition: Shells (condition=shells)
Block until the given background shell ID(s) exit. When shell_ids is omitted, waits for all currently running background shells.
- Parameters:
shell_ids(optional, array of strings) - specific shell IDs to wait for. Omit to wait for all pending background shells. - Returns: Exit codes and tail output (last 4096 bytes) for each shell.
Use cases:
- Wait for a long-running build or test to finish
- Wait for multiple parallel background tasks to complete
- Coordinate sequential steps that depend on background work
Condition: File (condition=file)
Block until a file path is created, modified, or removed (uses fsnotify for efficient inotify/FSEvents-based watching).
- Parameters:
path(required, string) - file path to watch.event(optional, string, enum:create,modify,remove,any) - file event to wait for. Default:any. - Behavior: For
create: checks if the file already exists first (returns immediately if so). Watches the parent directory for the target filename. Uses OS-native file system notifications (no polling).
Use cases:
- Wait for a download to complete
- Wait for a log file to be created
- Wait for a lock file to be removed
- Wait for a build artifact to appear
Condition: Command (condition=command)
Re-run a check command server-side at a fixed interval until it exits 0. The check command goes through the same bash allow-list as the Bash tool.
- Parameters:
command(required, string) - check command to re-run until it exits 0.pending_exit_codes(optional, array of numbers) - non-zero exit codes that mean "still pending, keep polling". Any other non-zero exit ends the wait immediately with reasoncheck_failed. - Behavior: First run happens immediately (no initial delay). Subsequent runs at
command_poll_interval_msinterval (default 2s). Each run has a 30-second per-execution timeout. Not available on Windows (requires bash). - Exit code classification:
- Exit 0:
condition_met- success - Exit in
pending_exit_codes: keep polling - Exit non-zero (not in pending):
check_failed- ends immediately - No pending_exit_codes specified: keep polling on any non-zero exit
- Exit 0:
Use cases:
- Wait for a service to become healthy:
curl -sf localhost:8080/health - Wait for CI to complete:
gh pr checkswithpending_exit_codes=[8] - Wait for a file to contain specific content:
grep -q 'ready' /var/log/app.log - Wait for a port to open:
nc -z localhost 3000
Configuration
# ~/.infer/tools.yaml
tools:
  wait:
    enabled: true # Enable/disable the Wait tool
    max_timeout_seconds: 600 # Maximum allowed timeout (ceiling)
    command_poll_interval_ms: 2000 # Poll interval for command condition (ms)
Examples
# Wait for background build to finish
Wait(condition=shells, shell_ids=["build-1"], timeout_seconds=300)

# Wait for a file to be created
Wait(condition=file, path="/tmp/result.json", event="create", timeout_seconds=60)

# Wait for service health
Wait(condition=command, command="curl -sf http://localhost:8080/health", timeout_seconds=120)

# Wait for CI checks with pending exit codes
Wait(condition=command, command="gh pr checks 792 --repo inference-gateway/cli", pending_exit_codes=[8], timeout_seconds=600)

# Wait for all background shells
Wait(condition=shells, timeout_seconds=300)
Web Tools
WebSearch
Search the web via DuckDuckGo or Google.
- Parameters:
query(required),engine(duckduckgo|google, defaults to the configured engine),limit(1-50, defaults to configuredmax_results),format(textorjson)
# ~/.infer/tools.yaml
tools:
  web_search:
    enabled: true
    default_engine: duckduckgo
    max_results: 10
    engines: [duckduckgo, google]
    timeout: 10
WebFetch
Fetch content from an allowed URL. Optionally save the response to disk.
- Parameters:
url(required),format(textorjson),download(defaultfalse- whentrue, saves under.infer/artifacts/<session-id>/) - Notes: only allowed domains can be fetched; responses are cached (default 15-minute TTL)
# ~/.infer/tools.yaml
tools:
  web_fetch:
    enabled: true
    allowed_domains:
      - golang.org
      - github.com
      - agents.md
    safety:
      max_size: 8192
      timeout: 30
    cache:
      enabled: true
      ttl: 3600
Image Tools
ImageGeneration, ImageEdit, and ImageVariation all write their PNG to the session artifacts directory - .infer/artifacts/<session-id>/image-<timestamp>.png - so the images produced by a conversation stay grouped together. See Artifacts directory.
ImageEdit Tool
Edit an existing image and save the result as a PNG under .infer/artifacts/<session-id>/. The chat model calls the tool when the user asks to edit an image; the tool reads the input image from a local file path and sends a plain one-off request to /v1/images/edits using the configured image model - no system prompt, no tools, independent of the model selected for the chat session.
Parameters:
image(required): Local file path of the image to editprompt(required): Text description of the desired editmask(optional): Local file path to a PNG whose fully transparent areas (alpha = 0) mark the editable region; all other pixels are preserved exactly. Must be a PNG with the same dimensions as the input image. Non-PNG paths are rejected by tool validation. Omit to let the model localize the change from the prompt alone - useful for models that repaint areas the user did not ask to change, and required for dall-e-2 edits without transparency.quality(optional):auto(default),low,medium,high, orstandardsize(optional):1024x1024(default),1536x1024, or1024x1536
Configuration:
# ~/.infer/tools.yaml
tools:
  image_edit:
    enabled: true
    model: openai/gpt-image-2
    require_approval: false
Example with mask:
{
  "image": "photo.png",
  "prompt": "replace the sky with a sunset",
  "mask": "sky-mask.png"
}
ImageVariation Tool
Create a variation of an existing image and save the result as a PNG under .infer/artifacts/<session-id>/. The chat model calls the tool when the user asks for a variation; the tool reads the input image from a local file path and sends a plain one-off request to /v1/images/edits using the configured image model - no system prompt, no tools, independent of the model selected for the chat session.
Parameters:
image(required): Local file path of the image to base the variation onsize(optional):1024x1024(default),1536x1024, or1024x1536
Configuration:
# ~/.infer/tools.yaml
tools:
  image_variation:
    enabled: true
    model: openai/gpt-image-2
    require_approval: false
Vision-capable models and ImageDecode
Vision-capable models (those with the vision label in the model picker) see pasted or @-referenced images natively - the image data is sent directly to the model, which can inspect it without a separate tool call. For these models, the ImageDecode tool is hidden from the advertised tool list to avoid steering the model toward a text annotation when it can see the image directly.
The tool remains executable if called - a model that invokes it from conversation history or right after a model switch gets a working tool, not an error. Text-only models keep the tool and the "use ImageDecode to inspect it" note unchanged.
The same split applies to an image file on disk: a vision model reads it with Read, which attaches the image to its next message, while a text-only model is sent to ImageDecode for a description in words. ImageDecode works for every model either way.
Audio Tools
TextToSpeech Tool
Synthesize speech from text with a local TTS engine and save it as a WAV file. The chat model calls the tool when the user asks to say something aloud or to clone a voice; synthesis shells out to llama.cpp's llama-tts binary running Qwen3-TTS GGUF models, fully offline. Disabled by default - while text_to_speech.enabled is false, the tool definition is not sent to the LLM at all.
Parameters:
text(required): The text to speakvoice_sample(optional): Bare file name of a WAV of the target speaker (~10-30s of clean speech) to clone, resolved against the working directory first and then the voice samples library at~/.infer/models/tts/samples/; a name found in neither fails with an error listing both paths triedoutput_path(optional): Destination WAV; defaults to a timestamped file undertext_to_speech.output_dir(tts/in the media root)
Configuration:
text_to_speech:
  enabled: true
See Text-to-Speech for prerequisites, the full configuration reference, model presets, and voice-cloning guidance.
TextToMusic Tool
Compose a music clip from a text prompt and save it as an MP3 file. The chat model calls the tool when the user asks for background music, a loop, or a jingle. Generation goes through the gateway's Music API (POST /v1/audio/music) using the configured provider/model - the CLI holds no provider key, the gateway does, so requests show up in gateway logs and traces. Disabled by default - while text_to_music.enabled is false, the tool definition is not sent to the LLM at all.
Parameters:
prompt(required): Description of the music - genre, mood, instruments, temposeconds(optional): Clip length in seconds; omitted lets the provider pick a length that fits the promptinstrumental(optional):trueto guarantee the clip has no vocalsoutput_path(optional): Bare file name (no directories, no absolute paths) for the generated MP3, written insidetext_to_music.output_dir; defaults to a timestampedmusic-*.mp3
The clip is always MP3 - the format the gateway's music providers serve (ElevenLabs offers mp3, opus, and pcm, not wav). To place it elsewhere, compose first and copy the returned file.
Configuration:
text_to_music:
  enabled: true
  # model: elevenlabs/music_v2_5 # gateway provider/model id
  # output_dir: ~/.infer/projects/<project-slug>/tmp/media/music
  require_approval: false # optional; unset = no approval, like the image tools
Every key also has an INFER_TEXT_TO_MUSIC_-prefixed environment variable that takes precedence over the config file:
| Config key | Environment variable | Type | Default | Notes |
|---|---|---|---|---|
text_to_music.enabled | INFER_TEXT_TO_MUSIC_ENABLED | bool | false | Feature flag - must be true for the TextToMusic tool to reach the LLM |
text_to_music.model | INFER_TEXT_TO_MUSIC_MODEL | string | elevenlabs/music_v2_5 | Gateway provider/model id; a bare model name fails validation once the feature is enabled |
text_to_music.output_dir | INFER_TEXT_TO_MUSIC_OUTPUT_DIR | string | music/ under the media root | Where generated MP3s are written |
text_to_music.require_approval | INFER_TEXT_TO_MUSIC_REQUIRE_APPROVAL | bool | unset (no approval) | Tri-state: unset keeps the tool's own default, an explicit value pins the policy either way |
Gateway requirements: the music endpoint is part of the gateway's Audio API, so the gateway must run with AUDIO_ENABLED=true and hold credentials for the provider behind model (an ElevenLabs API key for the default). The CLI-managed local gateway is started with AUDIO_ENABLED=true automatically when text_to_music.enabled is on, and an already-running instance without the Audio API is restarted. Point the CLI at an externally managed gateway and you set AUDIO_ENABLED=true and the provider key there yourself.
A gateway without the endpoint, or a provider that rejects the request, fails the tool call with a one-line error naming the configured model (music generation with elevenlabs/music_v2_5 failed: ...). The agent run still completes and no partial file is left behind.
TextToSFX Tool
Generate a short sound effect or ambience clip from a text prompt and save it as a WAV file. The chat model calls the tool when the user asks for a whoosh, a click, a riser or room tone - non-speech audio that TextToSpeech (it would read the words aloud) and TextToMusic (it composes songs) cannot cover. Generation goes through the gateway's SFX API (POST /v1/audio/sfx) using the configured provider/model - the CLI holds no provider key, the gateway does, so requests show up in gateway logs and traces. Disabled by default - while text_to_sfx.enabled is false, the tool definition is not sent to the LLM at all.
Parameters:
prompt(required): Description of the sound - the event or atmosphere and its character (a whoosh, a click, a riser, room tone, distant thunder)seconds(optional): Clip length in seconds,0.5-30; omitted lets the provider pick a length that fits the promptloop(optional):truefor a clip that loops seamlessly - useful for ambience bedsoutput_path(optional): Bare file name (no directories, no absolute paths) for the generated WAV, written insidetext_to_sfx.output_dir; defaults to a timestamped file
The same output_path rule as TextToMusic applies: the clip always lands in the configured output directory. To place it elsewhere, generate first and copy the returned file.
Configuration:
text_to_sfx:
  enabled: true
  # model: elevenlabs/eleven_text_to_sound_v2 # gateway provider/model id
  # output_dir: ~/.infer/projects/<project-slug>/tmp/media/sfx
  require_approval: false # optional; unset = no approval, like the image tools
Every key also has an INFER_TEXT_TO_SFX_-prefixed environment variable that takes precedence over the config file:
| Config key | Environment variable | Type | Default | Notes |
|---|---|---|---|---|
text_to_sfx.enabled | INFER_TEXT_TO_SFX_ENABLED | bool | false | Feature flag - must be true for the TextToSFX tool to reach the LLM |
text_to_sfx.model | INFER_TEXT_TO_SFX_MODEL | string | elevenlabs/eleven_text_to_sound_v2 | Gateway provider/model id; a bare model name fails validation once the feature is enabled |
text_to_sfx.output_dir | INFER_TEXT_TO_SFX_OUTPUT_DIR | string | sfx/ under the media root | Where generated WAVs are written |
text_to_sfx.require_approval | INFER_TEXT_TO_SFX_REQUIRE_APPROVAL | bool | unset (no approval) | Tri-state: unset keeps the tool's own default, an explicit value pins the policy either way |
Gateway requirements: the SFX endpoint is part of the gateway's Audio API (gateway v0.54.0 or newer), so the gateway must run with AUDIO_ENABLED=true and hold credentials for the provider behind model (an ElevenLabs API key for the default). The CLI-managed local gateway is started with AUDIO_ENABLED=true automatically when text_to_sfx.enabled is on, and an already-running instance without the Audio API is restarted. Point the CLI at an externally managed gateway and you set AUDIO_ENABLED=true and the provider key there yourself.
A gateway without the endpoint, or a provider that rejects the request, fails the tool call with a one-line error naming the configured model (sfx generation with elevenlabs/eleven_text_to_sound_v2 failed: ...). The agent run still completes and no partial file is left behind.
Video Tools
TextToVideo Tool
Render a short video clip and save it as an MP4. The chat model calls the tool when the user asks for a video clip or for an avatar to say something. Rendering goes through the gateway's Videos API (POST /v1/videos, polled with GET /v1/videos/{id} and downloaded from GET /v1/videos/{id}/content) using the configured provider/model - the CLI holds no provider key, the gateway does. Disabled by default - while text_to_video.enabled is false, the tool definition is not sent to the LLM at all, because avatar renders send the user's face and voice to a third-party provider.
Two modes:
- Prompt render - a text prompt, optionally with a portrait used as the first frame, rendered with
text_to_video.model. - Avatar render (lip-sync) - a portrait plus a
.wavor.mp3clip, rendered withtext_to_video.avatar_modelso the face speaks the audio.
Parameters:
prompt(required for a prompt render): Description of the clip - subject, action, camera, moodavatar(optional): Name of an avatar folder in the avatar library at~/.infer/avatars/, or a local image file, used as the portrait. Withaudioit is the portrait to lip-sync (first image in sort order); withoutaudioa library avatar is sent as reference images instead, while a bare image file stays the first frameaudio(optional): Local path to a.wavor.mp3clip to lip-sync; providing it selects the avatar render mode and requires a portraitoutput_path(optional): Bare file name (no directories, no absolute paths) for the generated MP4, written insidetext_to_video.output_dir; defaults to a timestamped file
Configuration:
text_to_video:
  enabled: true
  # model: elevenlabs/veo-3.1-fast-generate-001 # prompt renders
  # avatar_model: elevenlabs/creatify-aurora # lip-synced avatar renders
  # size: '' # "widthxheight" passthrough
  # output_dir: ~/.infer/projects/<project-slug>/tmp/media/video
  # timeout: 900
  # poll_interval: 5
  # create_avatar: false # register the CreateAvatar tool as well
  require_approval: false # optional; unset = no approval, like the image tools
Gateway requirements: the gateway must run with VIDEOS_ENABLED=true (gateway v0.54.0 or newer) and hold credentials for the provider behind the configured models. The CLI-managed local gateway is started with VIDEOS_ENABLED=true automatically while text_to_video.enabled is on; an externally managed gateway is your responsibility.
The portrait and the audio clip travel in one request, so together they must fit the gateway's 10 MiB request body limit, and creatify-aurora renders 480p or 720p keeping the portrait's aspect ratio.
See Text-to-Video and Avatars for the full configuration reference, the INFER_TEXT_TO_VIDEO_* environment variables, the avatar library layout, and infer avatars.
CreateAvatar Tool
Build an avatar folder at ~/.infer/avatars/<name>/ from a photo - the agent-side twin of infer avatars create. It stores the photo as the primary image and generates extra views of the same face through the gateway's image edit API using tools.image_edit.model, so a portrait the agent just generated, a selfie sent over a channel, or a photo in the project can become an avatar without leaving the chat.
Opt-in twice. The tool is registered only when both text_to_video.enabled and text_to_video.create_avatar (INFER_TEXT_TO_VIDEO_CREATE_AVATAR) are true; create_avatar defaults to false. It requires approval by default - unlike the other media tools - and an explicit text_to_video.require_approval overrides that either way.
Parameters:
name(required): Avatar name, which becomes the folder name under~/.infer/avatars/photo(required): Bare file name of the source photo, looked up in the working directory and then in the session artifacts directory; absolute paths and..are rejectedangles(optional): Which extra views to generate - defaults to both three-quarter angles, left/right profiles are available, and[]stores the photo only, with no image-edit callquality(optional): Image quality passed to the image edit API; defaults tohighsize(optional): Size of the generated views; defaults to1024x1536
It never overwrites an existing avatar - a name already in the library fails the call - and there is no delete counterpart, so the agent cannot remove an avatar. A failed view generation removes the half-built folder.
Privacy: generating views sends the photo to the image-edit provider (OpenAI by default). Before anything is stored or uploaded, a JPEG is turned upright per its EXIF orientation and re-encoded without its metadata, so camera and GPS tags never reach the library or a provider. PNG and WebP pass through unchanged.
GitHub Operations
There is no built-in GitHub tool. The agent performs all GitHub work - issues, pull requests, releases, repository metadata, and the raw API - through the gh CLI run via the Bash tool.
# Issues and pull requests
gh issue view 123
gh issue list --state open
gh pr create --title "fix: handle nil channel" --body "Closes #123"
gh pr diff 456

# Raw API (read-only / GET)
gh api repos/inference-gateway/cli/issues
gh api user --jq .login
Requirements: gh must be installed and authenticated. It uses the standard gh credential chain - run gh auth login, or set GITHUB_TOKEN (or GH_TOKEN). No separate token configuration exists anymore.
Default gh allowed-list
GitHub operations run through Bash, so they obey the Bash allowed-list. The default mode.all baseline auto-approves common read-only gh commands only:
| Auto-approved by default | Examples |
|---|---|
| Read-only reads | gh issue list, gh pr view 5, gh pr diff, gh repo view, gh release view v1 |
| Auth status | gh auth status |
| Search | gh search issues kind:bug, gh search code "func main" |
| Read-only project boards | gh project list, gh project view 3, gh project item-list 3 |
GitHub writes and destructive operations are deliberately left off the defaults. They are not auto-approved - they fall through to the standard approval prompt (in chat) or are blocked (in headless mode) until you add them to an allowed-list:
- Issue / PR writes -
gh issue create|edit|comment,gh pr create. - Project writes -
gh project item-add|item-edit. - Destructive -
gh pr merge,gh pr close,gh issue delete,gh repo delete,gh release create,gh run cancel,gh auth login. - Raw
gh api- any call. The previous GET-wildcard auto-approval was dropped; a raw-API need is now opt-in per repo.
Behavior change. Earlier defaults auto-approved
gh issue/prwrites and read-onlygh api. They now require approval - add the specific commands you trust to an allowed-list, or use the append override.
The shipped mode.all baseline:
# ~/.infer/tools.yaml
tools:
  bash:
    mode:
      all:
        allow:
          - gh (issue|pr|repo|release|run|workflow) (list|view|status|diff|checks)( .*)?
          - gh auth status( .*)?
          - gh search (issues|code|prs|repos|commits)( .*)?
          - gh project (list|view|item-list|field-list)( .*)?
Migration: the built-in GitHub tool was removed
Breaking change. The built-in
Githubtool was removed in favor of theghCLI. Thetools.githubconfig block and theinfer config tools githubcommands no longer exist. Existing configs that still contain atools.githubsection are ignored - unknown keys are dropped, so they do not error and need no manual cleanup. Replace any scripted use of the old tool with the matchingghcommand (for examplegh issue view,gh pr create,gh api).
Workflow Tools
TodoWrite
Create and update a structured task list for the current session. Use for complex multi-step work to track progress and surface intent to the user.
- Parameters:
todos(required array; each item hascontent,status∈pending|in_progress|completed, and optionalid) - Approval: not required
- Best practice: keep at most one task in
in_progressat a time; mark itemscompletedimmediately on finishing
Schedule
Create, list, get, update, or delete cron jobs that fire on a schedule. Jobs are persisted as YAML under ~/.infer/schedules/ and executed by the infer daemon (which reconciles its cron entries against storage every 2 seconds, so new or hand-edited jobs are picked up without a restart). When created from a channel session (e.g. Telegram), output is delivered back to that channel; otherwise the job is record-only - run history is persisted and viewable through the configured storage backend.
- Parameters:
operation(required:create|list|get|update|delete),job_id(required for get/update/delete),cron_expression(5-field crontab or@every <duration>),prompt,run_once(defaultfalse- whentrue, the job is deleted after firing once),name,description,model(optional model override) - Approval: required by default
- Notes: each fire creates a brand-new agent session - no context is carried between runs. Every fire persists a
RunRecord(session_id,job_id,status,error,started_at,finished_at) through the configured storage backend; the newest 200 records are retained.channelandrecipient_idon a job are optional delivery targets derived from the session, never passed by the LLM.
"0 8 * * *"      every day at 08:00
"*/15 * * * *"   every 15 minutes
"0 9 * * 1-5"    weekdays at 09:00
"@every 1h"      every hour
Jobs can also run in the cloud instead of the local daemon: set
scheduler.backend: githubto materialize each job as a GitHub Actions scheduled workflow. See Scheduling.
AskUserQuestion
Pause and ask the user 1-4 multiple-choice clarifying questions as an interactive, keyboard-driven form. The agent reaches for this whenever a task is ambiguous - in Plan Mode it resolves the ambiguity before it calls RequestPlanApproval, so your answers feed straight back into the plan it then proposes; in the other interactive modes the answers come back mid-task. It is read-only with no approval gate.
- Parameters:
questions(required array, 1-4 items). Each question has:header(required) - short chip label shown above the question, <= 12 charactersquestion(required) - the full question textoptions(required array, 2-4 items) - each option is{ label, description }multiSelect(optional, defaultfalse) - allow more than one answer to be selected
- Approval: not required (read-only)
- Availability: every interactive mode - Plan, Standard, Auto-Accept and auto-with-judge - when
tools.ask_user_question.enabledistrue. Headless runs have no interactive form and get the plain-text degradation below instead.
The form always appends an "Other" free-text choice to every question, so the user can answer outside the offered options. Suffix a label with (Recommended) to preselect that option when the question opens.
{
  "questions": [
    {
      "header": "Datastore",
      "question": "Which datastore should the new service use?",
      "multiSelect": false,
      "options": [
        {
          "label": "PostgreSQL (Recommended)",
          "description": "Relational, strong consistency, already used by the gateway."
        },
        { "label": "MongoDB", "description": "Document store with a flexible schema." },
        { "label": "Redis", "description": "In-memory, best for ephemeral or cache data." }
      ]
    }
  ]
}
Keyboard controls:
| Key | Action |
|---|---|
Up / Down | Move between options. For single-select questions the radio selection follows the cursor. |
Space | Toggle the highlighted option (multi-select questions). |
Enter | Confirm the current question and advance - or submit on the last question. |
Esc / Ctrl+C | Cancel the whole prompt. |
Headless graceful-degrade. When no interactive user is reachable to answer - a CI run, a heartbeat, or a scheduled job - the tool does not block. It returns a "proceed with assumptions" result so the agent keeps moving and picks a reasonable default instead of hanging.
RequestPlanApproval
Submit a completed plan for user approval. Available only in Plan Mode.
- Parameters:
plan(required - the complete, detailed plan text) - Behavior: pauses execution and offers three choices (see Approving a plan) - Accept (
Enter/y) switches to Auto-Accept mode and executes with no per-action approval, Approve Each Step (s) executes in Standard mode with approval on each action, and Reject (n) ends the session so you can reply with feedback.
RequestApproval
Ask the user to override an LLM judge rejection so the rejected tool call can run once. The agent reaches for it after a judge rejection (in auto-with-judge mode or under tools.safety.approval_behaviour: judge) - the rejection result itself hints that the path exists.
- Parameters:
tool(required - name of the rejected tool),arguments(required object - the exact arguments of the rejected call;{}for a call without arguments),what(required - what permission is needed, one sentence),why(required - why the action serves the user's request) - Behavior: shows the rejected call in the regular approval box with the judge's reason and the agent's justification. Approve runs that exact call once with the judge bypassed; Reject or dismissal denies and the turn continues with the decision in context.
- Eligibility: only calls the judge actually rejected can be escalated, and each one only once - anything else returns
not_rejectedoralready_escalated. The tool is advertised in every mode (a mode switch never invalidates the prompt cache), but outside judge mode nothing is ever rejected, so it has nothing to escalate. - Headless graceful-degrade: with no interactive approver (CI, headless, channels without an approval form) it returns a distinguishable "no approver reachable" result instead of blocking.
See Escalating a rejection for the full flow.
Local Subagents (Agent tool)
The Agent tool lets the main agent - in chat or headless mode - spawn one or more local subagents that run work in parallel and fold their results back into the main conversation. A subagent is just an infer headless subprocess with its own isolated session, so it is cheap, isolated, and session-persisted. The tool is enabled by default and gated by the tools.agent.* config block.
This is the lightweight, local complement to the A2A tools (A2A_SubmitTask / A2A_QueryTask / A2A_QueryAgent), which target external A2A servers:
| Reach for... | When |
|---|---|
| Agent (local subagents) | Short-lived helpers for the task at hand - parallel exploration, fan-out edits, scoped research - with no server to run. Each is a local infer headless subprocess. |
A2A tools (A2A_SubmitTask, ...) | Delegating to external, long-running, specialized A2A servers (calendar, docs, ...) discovered over the network. See A2A. |
Tool parameters
The model calls the tool with either a batch of tasks or a single description:
tasks- an array of subagent tasks run in parallel, each with:description(required) - the task for that subagentlabel(optional) - short label shown in progress output / tmux panesmodel(optional) - per-subagent model overridesystem_prompt(optional) - gives that subagent a specialized role/personaagent(optional) - name of a Markdown subagent preset that supplies the system prompt, model, and tool allowlist
description(optional) - shorthand for a single-task call (an alternative totasks)system_prompt(optional) - system prompt for the single-descriptionformagent(optional) - preset name for the single-descriptionform
Each subagent runs in its own isolated session id of the form subagent-<parentSession>-<uuid>. One call dispatches at most max_parallel subagents (default 10). Tasks past the cap are dropped, not queued, and the tool result says how many.
Markdown subagent presets
Instead of spelling out a system prompt on every call, a subagent can be defined once as a Markdown file with YAML frontmatter and delegated to by name through the agent parameter. The format is the same one Claude Code (.claude/agents/*.md) and Gemini CLI (.gemini/agents/*.md) use, so an existing agent file from either tool loads unchanged once copied in. Every preset shows up as a local row in the /agents view.
---
name: code-reviewer
description: Reviews a diff for correctness bugs. Use after making code changes.
model: deepseek/deepseek-v4-pro
tools: Read, Grep, Tree
---

You are a senior reviewer. Read the changed files and report findings as a
numbered list ordered by severity.
The Markdown body is the subagent's system prompt. Frontmatter keys:
| Key | Required | Meaning |
|---|---|---|
name | yes | Identifier passed as the agent argument. Lowercase letters, digits, -, _; up to 64 characters |
description | yes | Shown to the main agent so it knows when to delegate |
model | no | provider/model, or inherit to use the parent turn's model |
tools | no | Tools the subagent may use - a YAML list or a comma-separated string. Omitted means inherit all |
disallowedTools | no | Tools removed from the resolved list. Same format as tools |
mcpServers | no | Names of the MCP servers the agent brings up. See below |
Any other key (color, temperature, max_turns, permissionMode, ...) is accepted and ignored, so files written for other orchestrators load as-is. These are presets for the Agent tool, entirely separate from .infer/agents.yaml, the A2A agent registry.
Locations and precedence. Definitions are looked up in this order, first match wins on a name collision:
- Project:
.infer/agents/<name>.md- commit it to share the agent with the repository - Project, open standard:
.agents/agents/<name>.md- the shared.agents/convention, so a community agent file works where it already lives - User-global:
~/.infer/agents/<name>.md- stays personal - User-global, open standard:
~/.agents/agents/<name>.md- listed asuserin the/agentsview
A project preset therefore overrides a personal one of the same name, exactly like skills. This is the same layout skills and custom tools use, so a preset is seen both by the Agent tool and by a daemon thread opened as that agent.
Tool allowlist. The resolved allowlist is enforced inside the spawned subagent in one place: a disallowed tool is neither offered to the model nor executable by naming it. Unknown tool names (for example Claude's Glob) log a warning and are dropped, disallowedTools entries are always honored, and a restriction that resolves to no known tool skips the file rather than silently falling back to all tools. The preset's capability follows from the allowlist - read-only when every allowed tool is read-only, otherwise read-write (mutations still go through approval). Listing Agent itself lets a preset spawn subagents, still bounded by max_depth.
Model resolution. The file's model wins over a per-task model argument. A value without a provider prefix - a Claude alias such as sonnet, or a bare model ID - logs a warning and falls back to inherit. When the file sets no model, the normal order applies: per-task model, then tools.agent.model, then the parent turn's model.
MCP servers. mcpServers lists the MCP servers the agent brings up, by the names they have in the mcp.yaml of the computer the agent runs on - the file never carries a URL, a header or a secret of its own:
---
name: timekeeper
description: Tells the current time in any timezone.
mcpServers:
  - demo-server
---

You answer questions about the current time with the get_time tool.- Without the key the agent gets every enabled server, like any chat. An empty list (
mcpServers: []) gives it none. - Only the named servers are connected, and only those of them with
run: trueare started, so an agent never starts a container it does not use. - A named server comes up even when
mcp.yamlsetsenabled: falsefor it, so a server can stay off for every chat and serve one agent. A top-levelenabled: falseinmcp.yamlstill turns MCP off for every agent. - A name the computer's
mcp.yamldoes not have is skipped with a warning, and the agent still runs. - An inline server definition, which Claude Code also accepts, is ignored with a warning - define the server in
mcp.yamland name it here.
The list applies both to a subagent the Agent tool starts and to a daemon thread opened as that agent, and reaches the agent's process as INFER_AGENT_MCP_SERVERS. A session that moves to another workspace keeps the list and brings those servers up from that workspace's mcp.yaml. A tools list hides every MCP tool it does not name, so leave tools out to give the agent all the tools of its servers.
Files are scanned once per session. A file with broken frontmatter, a missing or invalid name/description, or an unusable tools list is skipped with a warning naming the file and the reason - an invalid preset never fails startup.
v1 limits.
.claude/agents/and.gemini/agents/are not read in place (copy or symlink the files into.infer/agents/), there is no hot reload, and per-agenttemperature,max_turns,permissionMode, and tool wildcards such asmcp_*are not honored. For a subagent the Agent tool starts, MCP tools register after session start, so MCP tool names in atoolslist are dropped as unknown - a daemon thread opened as the agent keeps them.
Result modes: async and wait-all
- Async (
wait: false) - the shipped default. The call returns immediately with the subagent ids, so later tool calls in the same turn run right away; when each subagent finishes a turn, its result is injected back into the main conversation (mirroringA2A_SubmitTasknotify behavior) and a headless subagent then stays alive for follow-ups. In chat, running/completed status is surfaced in the sticky progress area. - Wait-all (
wait: true) - the call blocks until every spawned subagent reaches a terminal state, then returns the aggregated results in one tool result. A blocking subagent returns its first turn and is not kept alive.
Execution surfaces: headless and interactive (tmux)
The mode controls where subagents run. Either way the result aggregates back into the main context exactly the same - interactive is "headless plus a tmux pane attached to the live process":
headless(the shipped default) - each subagent runs in the background as aninfer headless --keep-alivesubprocess whose stdin the parent holds open; results aggregate back into the main context.interactive- each subagent runs in a live tmux pane/window you can watch while it works.
tmux is an optional runtime dependency, required only for interactive mode (headless needs nothing extra). Interactive mode must be run from inside tmux ($TMUX set). Panes always open as a vertical split, and when you are not inside tmux (or tmux is not installed) the call warns and runs headless - there is nothing to configure either way.
In chat, a headless subagent is listed in the background job list under the composer while it works, with its run stats counting up. Select its row and press Enter to read its conversation so far, refreshed every second.
Headless keep-alive lifecycle
A headless subagent is a conversation, not a one-shot: the delegated task is its first turn, and it stays alive afterwards so the main agent can talk to it without respawning and losing its context.
- One completion note per finished turn. Each turn that ends delivers a
[Subagent Completed: <label>]note carrying that turn's final message and the run stats; a turn that ended in an error arrives as[Subagent Failed: <label>]with the error. The stats cover the whole subagent session - every turn it ran, not just the one that produced the note. - Follow-ups with
SendSubagentInput. Passingtextsends the subagent a message - new information, a correction, a question about its result - which it runs as its next turn in the same session, with a new completion note when that turn ends. A message sent while the subagent is mid-turn is queued and runs next, so nothing is lost and no note is duplicated. - Idle auto-close. A subagent that sits idle for
tools.agent.idle_timeoutseconds after a completed turn is closed with one[Subagent Closed: <label>]note carrying its last message.0disables the auto-close. There is no[Subagent Idle]warning for a headless subagent: every turn reports done, so the completion note itself is the cue that it awaits a follow-up. CloseSubagentstops a headless subagent at once, whether it is idle or running.- An idle subagent does not keep a headless parent alive. A one-shot
infer headlessrun that delegated work exits once its own turn is done.
SendSubagentInput works for both execution surfaces: text is the message in either mode, while keys and submit: false drive an interactive pane's TUI and fail for a headless subagent.
Done signal and idle auto-close (interactive panes)
An interactive pane is not a REPL you keep open. Each subagent reports completion and the parent closes the pane for you:
- Done signal. On its task turn - and on a failed terminal turn - the subagent writes
done: trueinto the result file behindINFER_SUBAGENT_RESULT_FILE. The parent monitor sees it, closes the pane, and emits exactly one[Subagent Completed: <label>]note (carrying the error text when the turn failed). - Every completed turn with text counts as done, including one that ends with a question. Write self-contained task descriptions: a subagent that stops to ask for more detail is treated as finished, not as waiting.
- Idle auto-close. A subagent that never reports done - a turn that ended without any text, a hung TUI, a pane running an older binary - is closed after
tools.agent.idle_timeoutseconds of inactivity. You get an early[Subagent Idle: <label>]warning, then[Subagent Closed: <label>]when the pane is closed. - The clock pauses for approvals and is reset by
SendSubagentInputtyping, so a subagent waiting on your approval is never closed out from under you. CloseSubagentis only for stopping a subagent early. The main agent does not need it in the normal case - completed and idle panes close themselves.
Agent tool configuration
The new tools.agent block in ~/.infer/tools.yaml, with its shipped defaults (regenerated by infer init):
# ~/.infer/tools.yaml
tools:
  agent:
    enabled: true
    require_approval: true # spawning work that can edit files is a mutating action
    mode: headless # headless | interactive (default when a call omits it)
    wait: false # return as soon as the subagents are dispatched; each reports back on its own
    max_parallel: 10 # cap on concurrent subagents per call
    max_depth: 1 # recursion guard; a subagent is itself an `infer headless`
    model: '' # default subagent model (inherits parent if blank)
    inherit_mock: true # when gateway.mock is on, spawn subagents against the embedded mock too
    idle_timeout: 300 # seconds a subagent may sit idle before the parent closes it (0 disables)
    completed_retention: 5 # finished subagent results kept for later retrieval
Idle timeout (idle_timeout, default 300). Seconds a subagent may sit idle before the parent closes it with one [Subagent Closed: <label>] note; 0 disables the auto-close. A headless subagent is idle from a completed turn until the next SendSubagentInput (see headless keep-alive lifecycle); an interactive pane is idle when it shows no harvested result turn, no pane change and no pending approval, which only catches a pane that never reported done. Approval prompts pause the clock and SendSubagentInput resets it. See Done signal and idle auto-close.
Every key has an INFER_TOOLS_AGENT_* environment-variable override, consistent with the rest of the config:
| Setting | Environment variable |
|---|---|
enabled | INFER_TOOLS_AGENT_ENABLED |
require_approval | INFER_TOOLS_AGENT_REQUIRE_APPROVAL |
mode | INFER_TOOLS_AGENT_MODE |
wait | INFER_TOOLS_AGENT_WAIT |
max_parallel | INFER_TOOLS_AGENT_MAX_PARALLEL |
max_depth | INFER_TOOLS_AGENT_MAX_DEPTH |
model | INFER_TOOLS_AGENT_MODEL |
inherit_mock | INFER_TOOLS_AGENT_INHERIT_MOCK |
idle_timeout | INFER_TOOLS_AGENT_IDLE_TIMEOUT |
completed_retention | INFER_TOOLS_AGENT_COMPLETED_RETENTION |
# ~/.infer/tools.yaml - toggle the tool, or switch the default execution
# surface to watchable tmux panes
tools:
  agent:
    enabled: true
    mode: interactive
Mock inheritance (inherit_mock, default true). When the parent CLI runs against the embedded mock gateway (gateway.mock: true), spawned subagents inherit mock mode: the CLI passes INFER_GATEWAY_MOCK=true to each subagent - both the headless environment and the interactive tmux-pane command - so they exercise the same mock instead of talking to the real gateway. Set tools.agent.inherit_mock: false (or INFER_TOOLS_AGENT_INHERIT_MOCK=false) to opt out and have subagents always target the configured gateway.
Approval and security
- Subagents run in standard bash mode (the restricted allowed-list), exactly like every other headless run - an off-list or mutating action is blocked in CI/heartbeat (no approver reachable) or sent for IPC approval under a channel (for example Telegram). See Headless secure-by-default.
- The Agent tool is in the approval policy and requires approval by default (
require_approval: true), with a per-tool override - consistent withA2A_SubmitTask. Spawning work that can edit files is treated as a mutating action. - A depth guard (
max_depth, default1) prevents subagent fork-bombs: a subagent cannot itself spawn further subagents at the default cap. - While the parent is in plan mode, every subagent is read-only, whatever its preset or derived allowlist says.
Tracing
When telemetry is enabled, a headless subagent inherits the caller's trace context (TRACEPARENT), so its own session span nests under the caller's execute_tool Agent span - the whole fan-out reads as one cross-process trace in infer traces:
session (standard, success)            152ms
|-- execute_tool Agent                  89ms
|   `-- session (readonly, success)     52ms
|       `-- chat openai/gpt-4o          13ms
Interactive (tmux-pane) subagents are not stitched into the caller's trace; use mode: headless when you need the subagent's spans in the same trace. See Trace context propagation to subprocesses for the full contract.
v1 scope. Subagents do not nest (depth capped at 1), a subagent's tool-approval prompt is not routed back to the main chat TUI, only tmux is supported (no screen/zellij), and there is no CLI command to list or create Markdown presets (the
/agentsview lists them read-only).
Security Features
- Command allow-listing: Default-deny, per-mode allowed-list for the Bash tool
- Approval Prompts: Safety confirmations for Write/Edit/Delete/Bash
- Path Protection: Sensitive paths denied by default (
.git/,*.env,*.key,.infer/) - File sandbox:
~/.infer/sandbox.yamlbounds which paths the file tools may read and write - Protected policy files:
~/.infer/tools.yamland~/.infer/sandbox.yamlare userspace-only and the agent's file tools refuse to write them - Domain allow-listing: Control web fetch access
- Diff Preview: Colored, syntax-aware diff before file modifications
- Project Tools Always Ask: Custom tools supplied by a repository need approval on every call, whatever their manifest says, except in
automode - Write-Protected Tool Directories: Write, Edit, MultiEdit and Delete refuse any path inside a custom-tool directory (
~/.infer/tools/,tools.custom_dir,.infer/tools/,.agents/tools/), including through symlinks - this cannot be switched off
Tool Configuration
The whole tools policy lives in a userspace-only policy file, ~/.infer/tools.yaml - not in config.yaml. The keys for every tool sit at the top of the file and each tool's section sits under tools:. infer config get and the INFER_TOOLS_* overrides name both kinds tools.<key>, for example tools.safety.require_approval and tools.bash.enabled:
# ~/.infer/tools.yaml
enabled: true # all tool execution for LLMs
safety:
  require_approval: true # approval before any tool runs
  approval_behaviour: judge # how an approval is delivered
custom_dir: /opt/my-app/tools # user custom tools from another directory
tools:
  bash:
    enabled: true
    require_approval: true # per-tool override of safety.require_approval
    mode:
      standard:
        allow:
          - make test
infer init seeds the file from the defaults, and --overwrite regenerates it. Like sandbox.yaml, it is userspace-only and agent-protected:
- Only
~/.infer/tools.yamlis read. A project.infer/tools.yamland atools:block in anyconfig.yamlhave no effect, so a checked-out repository cannot change tool approval. - The Write, Edit, MultiEdit and Delete tools refuse the file, so the agent cannot approve itself by writing one file.
infer config set tools.*is rejected with an error namingtools.yaml- edit the file instead.infer config get tools(andinfer config get tools.bash) still prints the effective value.- The
INFER_TOOLS_*environment overrides are unchanged, and a set-but-empty value wins (INFER_TOOLS_WEB_FETCH_ALLOWED_DOMAINS=empties the list).
# Edit the policy
$EDITOR ~/.infer/tools.yaml

# Or override a single setting for one run
INFER_TOOLS_ENABLED=false infer headless "Summarize the README"

# Inspect the effective tools config
infer config get tools
The file sandbox is not a tools config key either. It lives in its own policy file,
~/.infer/sandbox.yaml- see File sandbox.
Running Tools Directly
Run any enabled tool outside a chat session, or check whether a bash command would pass the allowed-list, with the top-level infer tools command.
# Execute a tool by name with JSON arguments (tool names are case-insensitive)
infer tools execute Read '{"file_path":"README.md"}'
infer tools execute grep '{"pattern":"func main","path":"."}'

# Validate whether a bash command is allowed (without running it)
infer tools validate "git status"

# Gate a command on the allowed-list
infer tools validate "$cmd" && eval "$cmd"
infer tools execute <tool> [json-args] resolves tool names case-insensitively in the CLI - the agent itself still uses the exact PascalCase names. infer tools validate <command> reports whether a bash command would be permitted by the configured allowed-list, without executing it.
infer tools validate exits non-zero when the command is not allowed or when tools are disabled, and prints the reason on stderr, so it can gate a shell conditional as above. An allowed command exits 0.
infer tools executeandinfer tools validatemoved fromconfig tools exec/config tools validateto the top-levelinfer toolscommand.
Custom Tools
Custom tools let you add tools written in any language to the CLI. Drop one YAML manifest per tool into ~/.infer/tools/, or into a project's .infer/tools/ or .agents/tools/, and the CLI offers the tool to the model next to the built-in ones. A call runs the manifest's command with the call's arguments as JSON on stdin, and whatever the command prints on stdout is the result. There is no SDK to import and no server to run.
A custom tool behaves like a built-in tool: the model sees it under its own name, you can run it yourself with !!Name(arg="v") in chat or infer tools execute Name '{...}', and it follows the same agent modes and approval flow.
For a runnable version, see
examples/toolsin the CLI repository - a user tool and a project tool driven by a scripted mock model, so it needs no API key.
Custom Tools Quick Start
A tool that counts the words in a file, written as a shell script.
~/.infer/tools/WordCount.yaml:
name: WordCount
description: Count the words in a text file.
command:
  - ./word-count.sh
parameters:
  type: object
  properties:
    path:
      type: string
      description: Path of the file to count
  required:
    - path
modes:
  - standard
  - auto
  - auto-with-judge
  - plan
  - readonly
require_approval: false
~/.infer/tools/word-count.sh (make it executable with chmod +x):
#!/bin/sh
path=$(jq -r .path)
wc -w < "$path"
Try it without the model:
infer tools execute WordCount '{"path":"README.md"}'User Tools and Project Tools
The CLI loads custom tools from three directories and merges them:
| Directory | Kind | Approval |
|---|---|---|
~/.infer/tools/ (or tools.custom_dir) | User tools, which you installed | As the manifest's require_approval says |
.infer/tools/ in the working directory | Project tools, which the repository supplies | Always, except in auto mode |
.agents/tools/ in the working directory | Project tools, which the repository supplies | Always, except in auto mode |
When two directories define a tool with the same name, the project tool wins over the user tool, and .infer/tools/ wins over .agents/tools/.
A project tool comes with whatever repository you cloned, so the CLI never lets it run silently. Every call needs approval, even when its manifest says require_approval: false and even in readonly mode, which runs every other tool it offers without asking. Only auto mode, which runs every call unapproved, runs a project tool without asking. !!Name(...) and infer tools execute count as your approval, as for any tool.
Custom Tool Manifest Reference
A custom tool manifest uses the same format as the manifests of the CLI's built-in tools, plus three fields that only custom tools have: command, timeout and enabled. Unknown fields are rejected, so a misspelled key fails loudly instead of silently falling back to a default.
| Field | Required | Default | Meaning |
|---|---|---|---|
name | yes | Tool name the model sees. Must match the file name (WordCount.yaml), start with a letter, and use only letters, digits and underscores, up to 64 characters. | |
description | yes | What the tool does and when to use it. The model reads this to decide when to call the tool. | |
command | yes | Program and fixed arguments, as a list. It runs without a shell, see below. | |
parameters | yes | JSON Schema of type object for the call's arguments, sent to the model unchanged. | |
modes | no | standard, auto, auto-with-judge | Agent modes that offer the tool, see Custom Tool Modes and Approval. |
require_approval | no | tools.safety.require_approval | Whether a call needs approval before it runs. |
timeout | no | 30 | Seconds before the call is killed. |
enabled | no | true | false keeps the manifest on disk without loading the tool. |
command[0] is resolved like this:
- A bare name such as
infer-desktop-toolsis looked up onPATH. - A path containing a slash such as
./word-count.shorbin/toolresolves against the manifest's directory, so a tool can ship next to its manifest. - An absolute path is used as is.
How a Custom Tool Call Runs
- The CLI checks the arguments against
parameters: everyrequiredproperty must be present and each property must have its declared type. A call that fails the check never starts the process. - It starts
commandwithout a shell, in the session's working directory, with the CLI's environment. - It writes the arguments to stdin as one JSON object, for example
{"path":"README.md"}, and closes stdin. - Exit code 0: stdout is the tool result, as text. Non-zero exit code: the call fails, and stderr (or stdout when stderr is empty) goes back to the model as the error.
- The process is killed when
timeoutexpires or the turn is cancelled. On Linux and macOS the whole process group is killed, so the children a script started die too. On Windows only the direct child is killed.
Like every tool result, the output the model sees is capped at tools.max_result_bytes.
Custom Tool Modes and Approval
Custom tools follow the same policy as built-in tools:
modeslists the agent modes that offer the tool. Without it the tool is offered instandard,autoandauto-with-judge, and hidden inplanandreadonly, like an MCP tool. A tool that only reads can list every mode, as theWordCountexample in Custom Tools Quick Start does. A call outside the tool's modes is refused.require_approvaldecides whether a user tool's call needs approval. Without it the tool follows the globaltools.safety.require_approval(defaulttrue). A project tool always needs approval, see User Tools and Project Tools. How the approval is asked for followstools.safety.approval_behaviour(prompt,ipc,judgeorblock) in both chat and headless mode.
Listing
readonlydeclares the tool safe. Read-only mode runs the tools it offers without asking for approval, so only listreadonly(andplan) for tools that do not change anything.
Approval applies to calls the model makes. !!Name(...) in chat and infer tools execute are started by you and count as approved, as they do for built-in tools. infer tools execute --format json still reports approval_required for callers that handle approval themselves.
tools.enabled: false turns custom tools off together with the other local tools. Markdown subagents (.infer/agents/*.md) can list custom tools in their tools: field.
Custom Tool Names
Custom tools get no prefix, so they look like built-in tools to the model. To keep that unambiguous, the CLI skips a manifest whose name:
- matches the name of any built-in tool, even one your configuration switches off, compared case-insensitively (
readis rejected because ofRead), or - starts with
MCP_, which is reserved for MCP tools.
A custom tool never replaces a built-in or MCP tool, and no built-in or MCP tool replaces a custom tool. Between custom tools, a project tool replaces a user tool of the same name.
Example: One Binary for Many Tools (Rust)
A compiled program can back several tools through subcommands, one manifest per tool.
~/.infer/tools/TakeScreenshot.yaml:
name: TakeScreenshot
description: Capture a screenshot of a desktop app window and return the PNG path.
command:
  - infer-desktop-tools
  - screenshot
parameters:
  type: object
  properties:
    window:
      type: string
      description: Title of the window to capture
  required:
    - window
timeout: 60
src/main.rs (with serde and serde_json as dependencies):
use serde::Deserialize;
use std::io::Read;

#[derive(Deserialize)]
struct ScreenshotArgs {
    window: String,
}

fn screenshot(args: ScreenshotArgs) -> Result<String, String> {
    let path = format!("/tmp/{}.png", args.window.replace(' ', "_"));
    // Capture the window here.
    Ok(path)
}

fn main() {
    let mut input = String::new();
    std::io::stdin().read_to_string(&mut input).expect("reading stdin");

    let result = match std::env::args().nth(1).as_deref() {
        Some("screenshot") => serde_json::from_str(&input)
            .map_err(|e| format!("invalid arguments: {e}"))
            .and_then(screenshot),
        other => Err(format!("unknown subcommand {other:?}")),
    };

    match result {
        Ok(output) => println!("{output}"),
        Err(message) => {
            eprintln!("{message}");
            std::process::exit(1);
        }
    }
}
Install the binary on PATH (or reference it by a path relative to the manifest), and every manifest pointing at it becomes a tool.
Custom Tools vs MCP
MCP servers also add tools in any language. Custom tools are the lighter option when you control the tool:
- No server to start or health-check. Nothing runs until a call is made, which keeps each
infer headlessstart cheap. - No prefix: the tool is
TakeScreenshot, notMCP_<server>_TakeScreenshot. - Per-tool
modesandrequire_approval. MCP tools are hidden in plan mode and use the global approval setting.
~/.infer/tools/ is yours. It is unrelated to ~/.infer/bin/tools/, which infer binaries owns and fills with the prebuilt helper programs the CLI itself uses (ffmpeg, whisper-cli, llama-tts).
Custom Tool Security
A custom tool runs with your permissions and can do anything you can. The file sandbox (~/.infer/sandbox.yaml) only restricts the CLI's built-in file tools, not the programs custom tools start. Only install manifests and programs you trust, keep require_approval on for tools that change things, and list plan/readonly in modes only for tools that do not.
- Project tools always ask. A cloned repository can offer tools, but none of them runs without your approval outside
automode. - The CLI never edits the tool directories. The Write, Edit, MultiEdit and Delete tools refuse any path inside
~/.infer/tools/,tools.custom_dir,.infer/tools/or.agents/tools/, also through a symlink or another spelling of the path, so the model cannot write itself a tool that skips approval. This cannot be switched off. The Bash tool is not covered: inautomode it runs any command. - A project cannot change the approval policy.
custom_dir, the Bash allow-list and the approval settings come from your own~/.infer/tools.yaml; a project.infer/config.yamlor.infer/tools.yamlcannot touch them.
Loading Custom Tools From Another Directory
Set custom_dir in ~/.infer/tools.yaml, or the INFER_TOOLS_CUSTOM_DIR environment variable, to load your user tools from another directory instead of ~/.infer/tools/. The project directories still load:
# ~/.infer/tools.yaml
custom_dir: /opt/my-app/toolsINFER_TOOLS_CUSTOM_DIR=/opt/my-app/tools infer headless "Take a screenshot of the editor"An app that embeds the CLI can use this to offer its own tools without adding them to the user's terminal CLI.
Custom Tools Troubleshooting
- The tool does not show up. The CLI skips an invalid manifest with a warning in its logs (
~/.infer/logs/) and starts anyway. The warning names the file and the reason, such as an unknown field, a name that does not match the file name, or a taken name. - Test a tool without the model.
infer tools execute Name '{"arg":"value"}'runs it directly and prints the result or the error. - The call fails with "executable file not found". A bare command name must be on the
PATHthe CLI runs with. Use a path relative to the manifest, or an absolute path, instead.
Configuration
Two-layer configuration system with precedence from highest to lowest:
Configuration Precedence
| Priority | Source | Example |
|---|---|---|
| 1 (Highest) | Environment Variables | INFER_GATEWAY_URL, INFER_AGENT_MODEL |
| 2 | Command Line Flags | --model, -v, --verbose |
| 3 | Project Config | .infer/config.yaml |
| 4 | User Config | ~/.infer/config.yaml |
| 5 (Lowest) | Built-in Defaults | Internal defaults |
Configuration Files
infer init seeds the userspace baseline in ~/.infer/ (config.yaml, tools.yaml, sandbox.yaml, mcp.yaml, prompts.yaml, agents.yaml, shortcuts/, skills/ and so on) and writes nothing into the project. Project-level overrides are created on demand with infer config set --project <key> <value>, or with --project on infer mcp / infer agents. Configuration is split across purpose-specific YAML files rather than one giant file:
| File | Scope | Purpose | Where it is documented |
|---|---|---|---|
config.yaml | Project/user | Main config - agent, gateway, storage, pricing, and everything config set touches. A tools: block here is ignored. | Configuration |
prompts.yaml | Project/user | System prompts (prompts.agent.system_prompt), per-mode adjustments, and tool descriptions (prompts.tools.<Tool>.description) - edited, not set. | Configuration Commands |
mcp.yaml | Project/user | MCP server definitions and connection settings. | MCP Integration |
keybindings.yaml | Project/user | Keybindings for the TUI and diff viewer (category diff_viewer). | Diff viewer and git staging |
hooks.yaml | Project/user | User-defined shell commands run at agent-loop hook points (feature-flagged off by default). | Command Hooks |
reminders.yaml | Project/user | System reminders injected into the conversation on a schedule. | System Reminders |
tools.yaml | User only | Tools policy - enablement, approval, per-mode bash allowed-lists, each tool under tools:. A project copy is ignored. | Tool Configuration |
sandbox.yaml | User only | File sandbox policy - filesystem.allowed and filesystem.denied. A project copy is ignored. | File sandbox |
judge.yaml | Project/user | LLM judge that decides approval-requiring tool calls (model, timeout, prompts, on_error). | Judge Mode |
daemon.yaml | Project/user | infer daemon itself - the AG-UI binding's own switch, port and token (binding.enabled, binding.port, binding.token), plus the workspace registry and the idle and away exits. | Starting the daemon |
compute.yaml | User only | What sessions and models run on - the clusters, machines and gpus workspaces and rented GPUs use. A project copy is ignored. | Compute |
memory.yaml | Project/user | Persistent, cross-session agent memory - fact-files plus the MEMORY.md index. | Persistent Memory |
shortcuts/*.yaml | Project | Custom slash shortcuts - simple commands, subcommands, and AI-powered snippets. | Custom Shortcuts |
skills/ | Project/user | Agent Skills folders (name/SKILL.md) discovered and injected on demand. | Agent Skills |
tools/ | Project/user | Custom tool manifests (Name.yaml), one per tool, also read from .agents/tools/. | Custom Tools |
schedules/ | User | Persisted cron jobs created by the Schedule tool, run by the daemon. | Schedule |
artifacts/ | Project/user | Agent deliverables, grouped per session. | Artifacts directory |
logs/ | User | CLI and gateway log files (~/.infer/logs, overridable via logging.dir). | Key Configuration Areas |
bin/ | User | Downloaded binaries - the gateway server, plus optional helpers like ffmpeg. | Key Configuration Areas |
insights/ | User | Saved infer insights reports. Written with secrets redacted, and kept by /reset. | Insights Shortcut |
avatars/ | User | Avatar portrait folders (avatars/<name>/*.png) used by TextToVideo lip-sync renders. Kept by /reset. | Text-to-Video |
auth.yaml | User | Fallback provider API keys, used when a key is not in the environment or the project .env. | Provider API keys |
tmp/ | User | Scratch space, including the tmp/media root for generated speech, music, video, recordings, screenshots and retained attachments. Wiped by /reset. | Media directories |
No migration.
logs/andbin/are userspace-only: they live under~/.infer/and are shared by every project. Older versions wrote them into the project's.infer/directory; those directories are orphaned by design and safe to delete. The.infer/.gitignoreseeded byinfer initno longer listsbin/orlogs/*.log.
Provider API keys
Provider API keys (ANTHROPIC_API_KEY, OPENAI_API_KEY, GROQ_API_KEY, ...) are resolved per key, first hit wins:
| Priority | Source | Notes |
|---|---|---|
| 1 (Highest) | System environment | Exported in your shell, CI secrets, and so on. |
| 2 | Project .env | .env in the project directory. |
| 3 (Lowest) | ~/.infer/auth.yaml | Userspace fallback, shared by every project. |
Because resolution is per key, sources mix: OPENAI_API_KEY can come from the environment while ANTHROPIC_API_KEY comes from auth.yaml in the same run. The fallback applies when the CLI starts the gateway in both container and binary modes, and to A2A agent containers.
auth.yaml is a flat YAML map of environment-variable names to values:
ANTHROPIC_API_KEY: sk-ant-...
OPENAI_API_KEY: sk-...
DEEPSEEK_API_KEY: sk-...
Create it once and keep it private:
mkdir -p ~/.infer
$EDITOR ~/.infer/auth.yaml
chmod 600 ~/.infer/auth.yaml- Permissions:
0600is recommended. Broader permissions still work but log a warning. - Sandboxed:
auth.yamlis on thefilesystem.deniedlist of the file sandbox - agent tools cannot read or edit it. - Graceful degradation: a missing or unreadable file changes nothing; a malformed file is ignored with a logged warning. Key resolution never fails because of
auth.yaml. - Legacy
auth.json: the old JSON file is still read as a fallback whenauth.yamlis absent, so existing credentials keep working. Move your keys intoauth.yaml- JSON is valid YAML, so the contents can be pasted as-is.
Artifacts directory
Files the agent produces for you land in .infer/artifacts/<session-id>/, under the project config dir when there is one and the userspace config dir (~/.infer/artifacts/) otherwise. Each conversation gets its own subdirectory, so a session's output stays grouped and is easy to find, keep, or delete as a unit.
What lands there:
- Images from the ImageGeneration, ImageEdit, and ImageVariation tools -
image-<timestamp>.png. - WebFetch downloads and binary fetches.
- Auto-downloaded A2A task artifacts.
.infer/artifacts is not the same as .infer/tmp:
| Directory | Contents | Lifetime |
|---|---|---|
.infer/artifacts | Intended agent deliverables, grouped by session | Yours to keep - nothing prunes it for you |
.infer/tmp | Internal scratch - chunk staging, skill downloads, pastes, and the media root holding screenshots and generated media | Disposable working data |
Session IDs are sanitized before use, so a directory can never escape the artifacts root. The file sandbox carves the artifacts directory out as writable, so tools can save there even when it sits outside the allowed list.
Media directories
Every generated and retained media file lives under one media root, with a subdirectory per kind. The root follows the open project:
- In a project -
~/.infer/projects/<project-slug>/tmp/media/. The desktop app runs a selected project's sessions there, so its media lands in that project's root too. - No project open -
~/.infer/tmp/media/, used when the working directory is$HOMEor the desktop's~/.infer/workspace.
| Subdirectory | Contents | Config default of |
|---|---|---|
tts/ | Generated speech WAVs | text_to_speech.output_dir |
music/ | Generated music MP3s | text_to_music.output_dir |
sfx/ | Generated sound-effect WAVs | text_to_sfx.output_dir |
video/ | Rendered MP4 clips | text_to_video.output_dir |
recordings/ | RecordStart screen recordings | computer_use.recording.output_dir |
screenshots/ | Browser and computer-use screenshots | computer_use.screenshot.temp_dir |
voice/ | Retained inbound voice recordings | speech_to_text.recordings_dir |
attachments/ | Retained inbound Telegram photos and videos | channels.telegram.media.dir |
The media root is agent-readable and writable by design - retained recordings and attachments are assets the agent consumes, and generated speech is output it can reference. The rest of ~/.infer/ is covered by the .infer/ denial in the file sandbox, which asks before every read and write. /reset empties both tmp trees through their tmp parents; the owning subsystems recreate the subdirectories on next use. Directories you explicitly point outside ~/.infer are left alone.
Existing installs. Older releases placed these directories directly under
~/.infer/or~/.infer/tmp/(tts/,voice/,media/, ...). Nothing migrates automatically - they hold only disposable output, so delete them, ormvtheir contents into the media root to keep the retained files. Explicitoutput_dir/recordings_dir/temp_dir/media.diroverrides are unaffected.
Gateway TLS
A gateway behind a private CA, or one that requires mutual TLS, is reached through gateway.tls. The settings apply to every gateway call - the agent loop, model listing, titles, summaries, media, the gateway version probe and A2A requests to the gateway. Daemon workers inherit them, because they read the same config and environment.
gateway:
  url: https://gateway.example.internal:8443
  tls:
    ca_file: ~/.infer/gateway-ca.crt
    cert_file: ~/.infer/gateway-client.crt
key_file: ~/.infer/gateway-client.key| Setting | Environment variable | Purpose |
|---|---|---|
gateway.tls.ca_file | INFER_GATEWAY_TLS_CA_FILE | PEM CA bundle trusted for gateway calls on top of the system roots, for a gateway certificate from a private CA. |
gateway.tls.cert_file | INFER_GATEWAY_TLS_CERT_FILE | Client certificate presented to a gateway that requires mTLS. Set together with key_file. |
gateway.tls.key_file | INFER_GATEWAY_TLS_KEY_FILE | Private key for that client certificate. Set together with cert_file. |
- Adding a private CA costs no trust elsewhere: the system roots stay in place, and every other HTTPS call is unaffected.
cert_fileandkey_fileare set both or neither - one without the other is rejected.- Paths may start with
~. - TLS material that cannot be loaded fails each gateway call with the reason, naming the setting, rather than silently falling back to a transport the gateway would reject.
The server side of mTLS is configured on the gateway, not the CLI: SERVER_TLS_CLIENT_CA_PATH names the CA bundle signing accepted client certificates (gateway v0.61.0, see Mutual TLS). On Kubernetes it is set for you from spec.server.tls.clientCARef on the Gateway CR (operator v0.31.0, see Mutual TLS (clientCARef and spec.client.tls)).
Key Configuration Areas
Gateway Settings:
- Gateway URL and API key
- Private CA and client certificate for the gateway connection:
gateway.tls(see Gateway TLS) - Timeout and retry configuration (see Client retry and stream reconnection below)
- OCI image for auto-running gateway
- Model filtering:
gateway.include_models(allowlist) andgateway.exclude_models(blocklist). Both default to[].gateway.exclude_modelsis opt-in - the model picker already hides non-chat-capable models via the gateway-reported modalities, so use it only to hide specific models the gateway reports (large or costly chat models, for example); there is no shipped default blocklist. Set exclusions are passed to the gateway as theDISALLOWED_MODELSenvironment variable.
The downloaded gateway binary lands at ~/.infer/bin/inference-gateway - one shared copy per machine, reused by every project (the staleness check still re-downloads when the pinned version changes).
Logging Configuration:
Logging settings control log output, file location, and automatic log archiving:
logging:
  debug: false
  dir: '' # Override log directory (defaults to ~/.infer/logs)
  stdout: false # Also write logs to stdout/stderr in addition to the log file
  archive:
    enabled: true # Automatically archive oversized log files (default: true)
max_size_mb: 1024 # Threshold in MB; files exceeding this are gzip-compressed and truncated (default: 1024 = 1 GB)- logging.debug: Enable debug logging for verbose output (
INFER_LOGGING_DEBUG). There is no--debugflag - the only verbosity flag is the global-v, --verbose. - logging.dir: Override the log directory. Defaults to
~/.infer/logs(INFER_LOGGING_DIR) - CLI and gateway logs are machine-scoped and never written to the project directory. - logging.stdout: Also write logs to stdout/stderr in addition to the log file (default:
false) - logging.archive.enabled: Enable automatic log archiving (default:
true). When enabled, log files exceeding the size threshold are gzip-compressed to a timestamped.gzarchive and the original file is truncated so logging continues at the same path. The check runs at process startup. Set viaINFER_LOGGING_ARCHIVE_ENABLED. - logging.archive.max_size_mb: Maximum log file size in MB before archiving is triggered (default:
1024, i.e. 1 GB). A value of0or less disables archiving. Set viaINFER_LOGGING_ARCHIVE_MAX_SIZE_MB.
Agent Configuration:
- Default model for operations
- System prompt (
prompts.agent.system_prompt) and per-mode adjustments (mode_adjustment_plan/mode_adjustment_auto, delivered by the mode-change reminder) - System reminders interval
- Max turns and tokens
agent.max_duration_minutes(INFER_AGENT_MAX_DURATION_MINUTES): wall-clock budget for one run in minutes, default0(no budget). Once spent, the run ends after the current tool call rather than mid-call, so the work so far stays on disk andinfer headlessexits3. It is the clock-based companion toagent.max_turns- a slow run (a flash-tier model, browser use) can burn an hour inside its turn budget, and only a wall-clock limit bounds that. Pair it with theelapsed_minutesreminder trigger to have the agent start wrapping up before the budget runs out- Parallel tool execution (default: 5 concurrent)
- Project instructions:
agent.agents_md.*injects the rootAGENTS.mdand points at nested ones (see How AGENTS.md reaches the model)
The built-in system prompt includes a Current date: line (date-only, no time) so provider-side prompt-prefix caching stays effective across turns. When the agent needs the current time, it runs the date command via Bash.
Tool Settings:
Tool settings live outside config.yaml, in ~/.infer/tools.yaml, which keeps the keys for every tool at the top and each tool's section under tools:
- Enable/disable individual tools
- Approval requirements per tool (whether) and delivery via
safety.approval_behaviour(how) - Per-mode bash allowed-lists (
tools.bash.mode.<mode>.allow) - The file sandbox has its own policy file too,
~/.infer/sandbox.yaml
Storage Backends:
- JSONL (default) - append-only files for portable, inspectable history
- PostgreSQL - shared database for teams
- Redis - high-performance caching
- SQLite - local file storage
- Cloudflare D1 - external SQLite-compatible store over HTTP (for ephemeral CI runners)
- In-memory - temporary sessions
Message Queue:
queue.typepicks the queue backend (memorydefault,sqlite,postgres,redis),queue.namescopes it andqueue.poll_intervalsets the cross-process wake-up cadence - see Message Queue
Conversation Features:
- Automatic history with search
- AI-generated titles
- Token optimization and compaction (see Compaction)
- Export/import capabilities
Compaction
Long sessions outgrow the context window. When compaction runs, it keeps the first compact.keep_first_messages messages verbatim and replaces the rest of the tail with one checkpoint user message, so the session continues within budget. It triggers on token usage crossing compact.auto_at percent of the context window, on a session sitting idle past compact.rollover_on_idle_minutes, and on a manual /compact in chat.
compact:
  enabled: true # automatic conversation compaction (default: true) - INFER_COMPACT_ENABLED
  auto_at: 80 # percent of the context window (1-80) that triggers compaction (default: 80) - INFER_COMPACT_AUTO_AT
  keep_first_messages: 2 # leading messages always preserved (values at or below zero fall back to 2) - INFER_COMPACT_KEEP_FIRST_MESSAGES
  strategy: summary # how a compaction seeds the continued session (default: summary) - INFER_COMPACT_STRATEGY
  rollover_on_idle_minutes: 30 # idle minutes before a rollover starts a fresh session (default: 30) - INFER_COMPACT_ROLLOVER_ON_IDLE_MINUTES
  summary_max_tokens: 1024 # token budget for the compaction summary (default: 1024) - INFER_COMPACT_SUMMARY_MAX_TOKENS
With the default summary strategy, one extra LLM call writes the checkpoint structured into the sections Objective, Important Details, Work State, Next Move and Relevant Files. An empty summary aborts the compaction and leaves the history untouched. With compact.strategy: pointer, no LLM call is made and no summary sections are generated: the continued session is seeded with a single message that opens with the same --- Context Summary --- marker and points back at the previous session:
--- Context Summary ---

The earlier part of this conversation, including tool results, is stored in session `12345678-1234-1234-1234-123456789abc`. Run `infer conversations show 12345678-1234-1234-1234-123456789abc` if you need details from it.
The previous session keeps its full history in the configured conversation storage, so under pointer the model reads back only what it needs with infer conversations show <session-id> instead of the summarizer deciding up front what matters. Choose summary when the continued session should stay self-contained - old sessions may be deleted, or live on non-durable backends such as memory. Choose pointer when keeping every detail beats spending a summarizer call - well suited to long-lived channel and headless sessions on durable storage such as jsonl or sqlite.
Both strategies re-inject skills whose SKILL.md was read in the replaced range after the checkpoint so the agent keeps following them. An unknown compact.strategy logs a warning and falls back to summary, and a pointer compaction with no session id to point at is skipped, leaving the history untouched.
Client Retry and Stream Reconnection
The CLI automatically reconnects when a stream stalls or drops, using the client.retry.* settings for exponential backoff and attempt limits. A stall is detected when no progress is made - no response while connecting, no SSE chunk while streaming - for longer than client.stall_threshold_sec.
# .infer/config.yaml
client:
  stall_threshold_sec: 30 # seconds without progress before reconnecting (0 disables)
  retry:
    enabled: true
    max_attempts: 5 # maximum number of retry attempts (default: 5)
    retryable_status_codes: [408, 429, 500, 502, 503, 504] # transient errors only
    initial_backoff_sec: 5
    max_backoff_sec: 60
    backoff_multiplier: 2
Settings:
- client.stall_threshold_sec: Seconds without progress - no response while connecting, no SSE chunk while streaming - before the CLI drops the connection and reconnects (default:
30,0disables). Reconnects reuseclient.retry.*for attempts and exponential backoff. Keep this above your provider's worst first-token latency, since a stall retry restarts the response from scratch. Set viaINFER_CLIENT_STALL_THRESHOLD_SEC. - client.retry.enabled: Enable automatic retries for failed requests (default:
true). - client.retry.max_attempts: Maximum number of retry attempts (default:
5). Set viaINFER_CLIENT_RETRY_MAX_ATTEMPTS. - client.retry.retryable_status_codes: HTTP status codes that trigger retries (default:
[408, 429, 500, 502, 503, 504]); non-transient errors such as 401 fail fast with their real message. Set viaINFER_CLIENT_RETRY_RETRYABLE_STATUS_CODES. - client.retry.initial_backoff_sec: Initial delay between retries in seconds (default:
5). - client.retry.max_backoff_sec: Maximum delay between retries in seconds (default:
60). - client.retry.backoff_multiplier: Backoff multiplier for exponential delay (default:
2).
Reconnecting indicator: In the chat TUI, the status bar shows a red Reconnecting... indicator when a stall is detected, then Reconnecting (N/M) per attempt (where N is the current attempt and M is max_attempts). Input is blocked until the stream recovers or all attempts are exhausted. See Status indicator row.
System Reminders
System reminders are YAML-configured prompts injected into the conversation on a schedule or in response to tool outcomes. They are defined in reminders.yaml (project or user scope) and can also be supplied inline or from an arbitrary path.
Reminders YAML Schema
# .infer/reminders.yaml (or ~/.infer/reminders.yaml)
enabled: true
reminders:
  - name: memory-consult
    hook: pre_tool
    trigger: always
    text: 'Consult the Memory tool before making changes.'
  - name: fail-nudge
    hook: post_tool
    trigger: on_failure
text: 'A failed call means the change did not happen. Re-try or ask the user.'| Field | Type | Description |
|---|---|---|
enabled | boolean | Master switch. Default true. Can also be toggled via INFER_REMINDERS_ENABLED. |
name | string | Unique identifier for the reminder. Used for deduplication and logging. |
hook | string | When the reminder fires. One of pre_tool (before each tool call) or post_tool (after each tool call completes). |
trigger | string | Condition under which the reminder fires. See Trigger catalog below. |
text | string | The reminder text injected into the conversation. Supports os.ExpandEnv environment variable interpolation ($VAR or ${VAR}). |
threshold | integer | Required (> 0) for on_repeated_failure - consecutive failures of the same call before the reminder fires - and for elapsed_minutes, where it is the number of minutes. |
guidance | map | on_mode_change only. Maps a mode key (standard, plan, auto) to the text substituted for the {guidance} placeholder in text. Omitted keys keep their built-in defaults. |
Trigger catalog
| Trigger | Hook requirement | Description |
|---|---|---|
always | Any | Fire on every hook invocation. |
on_failure | post_tool | Fire only when the tool call that just ran failed (returned an error). Requires hook: post_tool; validation rejects other hooks. |
elapsed_minutes | Any | Fire once, when the run has been going threshold wall-clock minutes. Requires threshold > 0. The clock-based twin of turns_before_max - set it below agent.max_duration_minutes so the agent is told to wrap up while it still has budget left. |
on_mode_change | Any | Fire when the agent mode changes (Shift+Tab). Used by the built-in mode-change-reminder, which is the sole carrier of mode-specific instructions - see How mode instructions are delivered. |
on_repeated_failure | post_tool | Fire when the same tool call has failed threshold times in a row (built-in default 3). Matching is on normalized arguments, not the raw string: offset, limit, key order and whitespace are ignored, so retries that only change pagination or re-serialize the same arguments still count toward the threshold. Read matches on the file_path alone. A success with the same key resets the counter. Requires hook: post_tool and threshold > 0. |
The built-in repeated-failure reminder uses this trigger and is appended to the failing tool result:
<system-reminder>
{tool_name} failed {count} times with the same arguments. Stop retrying - verify your assumptions (list or search first) and take a different approach.
</system-reminder>
{tool_name} and {count} are substituted from the tracked failure; both placeholders work in your own on_repeated_failure reminder text.
Configuration sources and precedence
Reminders are resolved with the following precedence (highest first):
| Priority | Source | Description |
|---|---|---|
| 1 (Highest) | INFER_REMINDERS_CONFIG | Inline YAML string. When set, it replaces all file-loaded reminders. |
| 2 | --reminders-file PATH | Load reminders from an arbitrary file path. Available on infer headless and infer chat. |
| 3 | Project config | ./.infer/reminders.yaml |
| 4 | User config | ~/.infer/reminders.yaml |
| 5 (Lowest) | Built-in defaults | The CLI ships a built-in memory-consult reminder that nudges the agent to consult the Memory tool, and a repeated-failure reminder that fires on the third failure of the same call. |
INFER_REMINDERS_ENABLED toggles the master switch on top of all sources — set it to false to disable all reminders regardless of the resolved config.
Disabling reminders drops mode instructions. The mode-change reminder is the only carrier of per-mode instructions, so with
enabled: false(orINFER_REMINDERS_ENABLED=false) the Plan and Auto-Accept guidance - including the destructive-action policy - is never delivered. Mode tool restrictions are unaffected.
INFER_REMINDERS_CONFIG
Set this environment variable to supply the full reminders YAML inline, without writing a reminders.yaml file. This is especially useful for CI/CD and embedded consumers (e.g. infer-action) that cannot write to ~/.infer/.
export INFER_REMINDERS_CONFIG='enabled: true
reminders:
  - name: fail-nudge
    hook: post_tool
    trigger: on_failure
    text: "A failed call means the change did not happen"
'
When INFER_REMINDERS_CONFIG is set, it replaces the file-loaded config entirely — it is not merged. To disable it and fall back to file-based config, unset the variable.
--reminders-file
The --reminders-file PATH flag is available on infer headless and infer chat. It loads reminders from an arbitrary YAML file path, bypassing the default file resolution.
infer headless "Refactor the module" --reminders-file /path/to/custom-reminders.yaml
infer chat --reminders-file ./ci-reminders.yaml
Example: CI with inline reminders
INFER_REMINDERS_CONFIG='enabled: true
reminders:
  - name: fail-nudge
    hook: post_tool
    trigger: on_failure
    text: "A failed call means the change did not happen"
' INFER_REMINDERS_ENABLED=true infer headless "..."
Essential Environment Variables
export INFER_GATEWAY_URL="http://localhost:8080"
export INFER_GATEWAY_API_KEY="your-api-key"

# Gateway TLS (see Gateway TLS): private CA bundle, plus a client certificate for mTLS
export INFER_GATEWAY_TLS_CA_FILE="$HOME/.infer/gateway-ca.crt"
export INFER_GATEWAY_TLS_CERT_FILE="$HOME/.infer/gateway-client.crt"
export INFER_GATEWAY_TLS_KEY_FILE="$HOME/.infer/gateway-client.key"

export INFER_AGENT_MODEL="deepseek/deepseek-v4-flash"
export INFER_LOGGING_DEBUG="true"
export INFER_LOGGING_ARCHIVE_ENABLED="true"
export INFER_LOGGING_ARCHIVE_MAX_SIZE_MB="1024"
export INFER_CLIENT_STALL_THRESHOLD_SEC="30"  # seconds without stream progress before reconnecting (0 disables)
export GITHUB_TOKEN="your-github-token"  # used by the gh CLI credential chain for GitHub operations

# Message queue backend (see Message Queue): memory (default), sqlite, postgres or redis
export INFER_QUEUE_TYPE="redis"
export INFER_QUEUE_NAME="my-shared-queue"  # empty scopes the queue to this process's session id
export INFER_QUEUE_POLL_INTERVAL="2s"

# Append a few commands onto the bash allowed-list baseline (comma- or newline-separated)
export INFER_TOOLS_BASH_ALLOW_APPEND="git commit,git push"

# How a needed approval is delivered: prompt | ipc | judge | block
export INFER_TOOLS_SAFETY_APPROVAL_BEHAVIOUR="prompt"

# Load user custom tools from another directory instead of ~/.infer/tools
export INFER_TOOLS_CUSTOM_DIR="/opt/my-app/tools"

# Inline reminders YAML (replaces file-loaded reminders)
export INFER_REMINDERS_CONFIG='enabled: true
reminders:
  - name: fail-nudge
    hook: post_tool
    trigger: on_failure
    text: "A failed call means the change did not happen"
'

# Master switch for reminders (default: true)
export INFER_REMINDERS_ENABLED=true

# Per-mode adjustment instructions, delivered by the mode-change reminder
# (supersede the deprecated INFER_PROMPTS_AGENT_SYSTEM_PROMPT_PLAN / _AUTO)
export INFER_PROMPTS_AGENT_MODE_ADJUSTMENT_PLAN="Investigate first; do not propose edits."
export INFER_PROMPTS_AGENT_MODE_ADJUSTMENT_AUTO="Confirm before any irreversible operation."

# Opt-in next-step suggestions (see Next-Step Suggestions)
export INFER_CHAT_SUGGESTIONS_ENABLED="true"
export INFER_CHAT_SUGGESTIONS_MODEL="deepseek/deepseek-v4-flash"  # empty falls back to the chat model
export INFER_CHAT_SUGGESTIONS_CONTEXT_MESSAGES="4"
export INFER_CHAT_SUGGESTIONS_MAX_TOKENS="512"
export INFER_CHAT_SUGGESTIONS_TIMEOUT="10"
export INFER_CHAT_SUGGESTIONS_LOGS_ENABLED="true"   # session warnings/errors ground the suggestion
export INFER_CHAT_SUGGESTIONS_LOGS_MAX_LINES="5"
export INFER_CHAT_SUGGESTIONS_LOGS_MAX_CHARS="600"
export INFER_PROMPTS_CHAT_SUGGESTIONS_SYSTEM_PROMPT="Suggest one short next step."
Configuration Commands
Configuration uses a generic key/value interface. infer config get reads the effective value of any key; infer config set writes one to the userspace baseline (~/.infer/config.yaml) by default, or to the project config (./.infer/config.yaml) when you pass --project. Keys are dotted paths into the config (for example agent.model, gateway.url). tools.* keys are read-only here - they live in ~/.infer/tools.yaml, so config get tools.bash works but config set tools.* is rejected.
# Initialize configuration
infer config init

# Print the whole effective config (defaults + ~/.infer + .infer + INFER_* env)
infer config get

# Print a single key
infer config get agent.model

# Print as JSON instead of YAML
infer config get --format json

# Set a value - parsed to the field's type (bool, integer, number, or string),
# then validated by loading the config back before the write is kept
infer config set agent.model deepseek/deepseek-v4-flash
infer config set agent.max_turns 50
infer config set agent.verbose_tools true

# List-valued keys take a comma-separated value (the whole list is replaced)
infer config set gateway.exclude_models "openai/gpt-4o,groq/llama-3"

# tools.* is rejected - the tools policy lives in ~/.infer/tools.yaml
# (config get tools still prints the effective values)
infer config get tools.bash

# config set writes the userspace baseline (~/.infer/config.yaml) by default
infer config set agent.model deepseek/deepseek-v4-flash

# Target the project config (./.infer/config.yaml) instead - it overrides the baseline key-by-key
infer config set agent.model deepseek/deepseek-v4-flash --project

# Recreate config.yaml from defaults
infer config init --overwrite
config set validates before it keeps the write. After writing, it loads the config back; if the loader rejects the result - say agent.reasoning_effort=bogus - the previous file is restored and the command fails, so a bad value can never leave you with a config that stops infer from starting:
$ infer config set agent.reasoning_effort bogus
agent.reasoning_effort = bogus was not saved: invalid agent.reasoning_effort "bogus": must be one of minimal, low, medium, high, xhigh, max
System prompts are not set via
config set- they live inprompts.yaml(for exampleprompts.agent.system_prompt, and the per-modeprompts.agent.mode_adjustment_plan/mode_adjustment_auto) and are edited there. The same file holds the tool descriptions sent to the model underprompts.tools.<Tool>.description- for exampleprompts.tools.RequestApproval.description, which ships with a built-in default explaining when a judge rejection may be escalated. Any key you leave out keeps its built-in text.
Command Mapping
The per-setting subcommands were removed in favor of config get/config set and the top-level infer tools command:
| Old command | New command |
|---|---|
config agent set-model X | config set agent.model X |
config agent set-max-turns N | config set agent.max_turns N |
config agent verbose-tools enable | config set agent.verbose_tools true |
config agent skills enable | config set agent.skills.enabled true |
config tools enable | Set enabled: true in ~/.infer/tools.yaml |
config tools bash enable | Set tools.bash.enabled in ~/.infer/tools.yaml |
config tools safety enable | Set safety.require_approval in ~/.infer/tools.yaml |
config tools safety set bash enabled | Set tools.bash.require_approval in ~/.infer/tools.yaml |
config tools sandbox add DIR | Edit filesystem.allowed in ~/.infer/sandbox.yaml |
config tools grep set-backend rg | Set tools.grep.backend in ~/.infer/tools.yaml |
config tools web-fetch add-domain D | Add to tools.web_fetch.allowed_domains in ~/.infer/tools.yaml |
config export set-model X | config set export.summary_model X |
config show | config get |
config tools exec <tool> | tools execute <tool> |
config tools validate <cmd> | tools validate <cmd> |
See the full configuration reference for detailed options.
Reloading configuration in chat
/reload re-reads the config files and the INFER_* environment in a running infer chat, so editing a setting no longer means restarting the session:
infer config set gateway.timeout 300
# then, in infer chat:
/reload
# status line: Reloaded gateway.timeout
Hot keys - these change the running session immediately:
| Key | Effect on reload |
|---|---|
gateway.timeout | The next request uses the new timeout |
agent.model | Switches the active model, like /model |
agent.max_turns | Applies from the next turn |
agent.max_duration_minutes | Applies from the next turn |
agent.max_tokens | Applies from the next turn |
agent.reasoning_effort | Applies from the next turn, and the status bar follows |
chat.status_bar.* | The whole section - indicators hide or show on the next repaint |
Everything else needs a restart. Any other changed key is named in the status line as "restart to apply" rather than silently ignored - Reloaded agent.model · restart to apply gateway.url. gateway.url and gateway.api_key are restart keys, and tool policy, the file sandbox and approval policy never change mid-session, by design: a running agent keeps the permissions it started with.
Two cases leave the session exactly as it was, with the error shown instead:
- The new config fails validation. The previous config stays active.
- The agent is busy.
/reloadreportsagent is busy, run /reload after this turnrather than swapping config under a running turn.
/reload is only available in infer chat - headless and scheduled runs load their config once at startup.
Telemetry
The CLI records OpenTelemetry signals (metrics and traces) for every session. Telemetry is on by default and is turned off with telemetry.enabled: false (INFER_TELEMETRY_ENABLED=false) - no files are written, nothing is exported, and no trace context is passed to child processes. Data is written to local files under ~/.infer/telemetry/ and can optionally be exported to an OTLP/HTTP collector.
Local files
Both signals write per-session JSONL files to ~/.infer/telemetry/:
| Signal | File pattern | Description |
|---|---|---|
| Metrics | ~/.infer/telemetry/\<session-id\>.jsonl | Token usage, tool outcomes, session duration, and cost (delta temporality) |
| Traces | ~/.infer/telemetry/\<session-id\>-traces.jsonl | One root span per session, child spans for each LLM turn and tool call |
The \<session-id\> is the same UUID that appears in the CLI's session output and conversation storage. Local files use the OTLP/semconv JSON format as-is - no custom encoding.
Metrics
The CLI records the following metrics using the OpenTelemetry GenAI semantic conventions:
- gen_ai.client.token.usage - input and output token counts per LLM request
- gen_ai.execute_tool.duration - tool execution duration in seconds
- infer.agent.runs - total agent session count
- infer.agent.run.duration - session duration in seconds
- infer.client.cost - computed dollar cost per session
Metrics use delta temporality (required by the gateway ingest, and what makes the local files trivially summable by infer stats).
Traces
The CLI emits one trace per session with the following span hierarchy:
- session (root span) - carries
infer.execution.mode,infer.agent.mode,infer.run.outcome, andgen_ai.conversation.id - chat <model> (CLIENT kind) - one per LLM request, with
gen_ai.request.model,gen_ai.provider.name,gen_ai.usage.input_tokens,gen_ai.usage.output_tokens - execute_tool <name> (INTERNAL kind) - one per tool call, with
gen_ai.tool.name,gen_ai.tool.type,infer.tool.outcome
No prompt or response content is recorded in spans. Failed spans carry error.type and Error status per the OpenTelemetry recording-errors conventions.
Spans emitted by subprocesses - Bash tool commands, skill scripts, and headless subagents - are ingested and nested under their originating execute_tool span, so a single trace can span multiple processes. See Trace context propagation to subprocesses.
OTLP/HTTP export
Both signals can be exported to an OpenTelemetry Collector or any OTLP/HTTP-compatible backend by setting the standard OpenTelemetry environment variables:
# Base endpoint (each signal appends its own path: /v1/metrics, /v1/traces)
export OTEL_EXPORTER_OTLP_ENDPOINT=http://otel-collector:4318

# Optional: per-signal endpoint overrides (takes precedence over the base)
export OTEL_EXPORTER_OTLP_METRICS_ENDPOINT=http://otel-collector:4318/v1/metrics
export OTEL_EXPORTER_OTLP_TRACES_ENDPOINT=http://otel-collector:4318/v1/traces

# Headers (e.g. for authentication)
export OTEL_EXPORTER_OTLP_HEADERS="Authorization=Bearer%20my-token"

# Service identity (merged into the resource attributes on every signal)
export OTEL_SERVICE_NAME=infer-cli
export OTEL_RESOURCE_ATTRIBUTES="deployment.environment=production,actor=ci-bot"
When OTEL_EXPORTER_OTLP_ENDPOINT is set, the CLI exports both signals to that endpoint. Per-signal env vars (OTEL_EXPORTER_OTLP_METRICS_ENDPOINT, OTEL_EXPORTER_OTLP_TRACES_ENDPOINT) override the base for that signal. Headers and timeouts follow the standard OTel exporter env-var spec. The CLI builds no OTel log provider, so OTEL_EXPORTER_OTLP_LOGS_ENDPOINT has no effect.
Local file export is always active regardless of OTLP configuration - remote export is additive, not a replacement.
Local OTLP receiver (telemetry.receiver_address)
By default, the CLI runs an ephemeral loopback OTLP/HTTP receiver (127.0.0.1:0) that accepts spans from subprocesses (Bash tool commands, headless subagents) and persists them into the per-session trace file. This receiver is loopback-only and auto-allocated, so it is invisible to external processes.
When you need an external OpenTelemetry Collector (or any OTLP producer) to feed spans back into the CLI's local trace store - for example to see a remote A2A agent's spans in infer traces - set telemetry.receiver_address to a fixed address:
# .infer/config.yaml
telemetry:
receiver_address: 0.0.0.0:4318# Environment variable
export INFER_TELEMETRY_RECEIVER_ADDRESS=0.0.0.0:4318When set, the receiver binds to that address at startup (instead of a random loopback port) and accepts OTLP/HTTP POST /v1/traces (protobuf) from any reachable producer. Received spans are filtered to the session's trace ID and appended to the local trace file, where they appear in infer traces nested under the originating execute_tool span.
Defensive limits: 4 MiB per request body, 5000 spans per session. The receiver always responds 200 - receiver failures never fail the tool.
Example: OpenTelemetry Collector
To receive both signals from the CLI, configure an OpenTelemetry Collector with OTLP/HTTP receivers:
receivers:
  otlp:
    protocols:
      http:
        endpoint: 0.0.0.0:4318

exporters:
  debug:
    verbosity: detailed
  otlp/jaeger:
    endpoint: jaeger-collector:4317
    tls:
      insecure: true

service:
  pipelines:
    metrics:
      receivers: [otlp]
      exporters: [debug]
    traces:
      receivers: [otlp]
      processors: [batch]
      exporters: [otlp/jaeger, debug]

processors:
  batch:
    send_batch_size: 1024
    timeout: 5s
Then run the CLI with the endpoint set:
export OTEL_EXPORTER_OTLP_ENDPOINT=http://otel-collector:4318
infer headless "Analyze the codebase"
Trace context propagation to subprocesses
When telemetry is enabled (telemetry.enabled: true, the default), the CLI propagates its active trace context into the processes it spawns, so spans emitted by tools and subagents stitch into the same trace as the CLI session. Propagation is built entirely on open standards - W3C Trace Context and W3C Baggage on the way out, plain OTLP spans on the way back - so any OpenTelemetry-instrumented tool participates with zero custom code. When telemetry is disabled, none of these variables are set.
Environment variables set for child processes
The Bash tool (and therefore skill scripts) and headless subagents receive:
| Variable | Standard | Contents |
|---|---|---|
TRACEPARENT / TRACESTATE | W3C Trace Context | The current trace, parented on the active execute_tool span, so child spans nest under it. |
BAGGAGE | W3C Baggage | session.id and gen_ai.tool.call.id, for correlating child spans back to the call. |
The two baggage member names are configurable: telemetry.attr_session_id_key and telemetry.attr_tool_call_id_key override session.id and gen_ai.tool.call.id respectively.
Where child spans are sent (OTLP sink selection)
The CLI selects the span sink automatically so children report to the same place the CLI does:
- An OTLP endpoint is configured (
telemetry.otlp.endpoint, or the standardOTEL_EXPORTER_OTLP_ENDPOINT) - the endpoint and its headers are passed through to the child environment asOTEL_EXPORTER_OTLP_ENDPOINT/OTEL_EXPORTER_OTLP_HEADERS, so child spans land in the same remote backend and stitch into the trace there. - No endpoint configured (the default) - the CLI runs an ephemeral localhost OTLP/HTTP receiver for the session and points children at it. Received spans are persisted into the local per-session trace store and appear in
infer traces//traces, nested under the tool span that spawned them.
Either way you get one coherent trace - local by default, in your backend when you have one.
Example: any OTel-instrumented command
Because propagation is standard OTLP, an off-the-shelf tool such as otel-cli emits a correctly parented child span with no wiring. Run it inside a Bash tool call:
otel-cli exec --name "go test" -- go test ./...The resulting go test span shows up as a child of execute_tool Bash in infer traces:
session (standard, success)                12.4s
`-- execute_tool Bash                        9.8s
    `-- go test                              9.6s
The same holds for a program instrumented with an OpenTelemetry SDK: as long as it reads the standard OTEL_EXPORTER_OTLP_ENDPOINT and TRACEPARENT variables - which every conformant SDK does - its spans nest under the execute_tool span automatically, with no CLI-specific integration.
Subagents: one cross-process trace
infer headless honors an inherited TRACEPARENT, so a headless subagent's own session span nests under the caller's execute_tool Agent span - a single trace that spans both processes:
session (standard, success)            152ms
|-- execute_tool Agent                  89ms
|   `-- session (readonly, success)     52ms
|       `-- chat openai/gpt-4o          13ms
Remote A2A agents
Outbound A2A requests carry traceparent, tracestate, and baggage HTTP headers, so a remote agent can continue the trace. This is context-out only: remote spans stitch into your trace through a shared OTLP collector that both sides export to - they are not written back into the local per-session trace store. Point both the CLI and the remote agent at the same telemetry.otlp.endpoint to see the full cross-service trace.
A2A traces example
The examples/a2a-traces directory in the CLI repository demonstrates end-to-end distributed telemetry between the CLI and a remote A2A agent (mock-agent), with an OpenTelemetry Collector in the middle. It exercises both telemetry models:
- Push (OTLP): the CLI exports its traces and metrics to the collector; the mock-agent exports its traces to the collector.
- Pull (Prometheus): the collector scrapes the mock-agent's
:9090/metricsendpoint.
The CLI injects W3C trace context into every outgoing A2A request, so the mock-agent's spans share the CLI's trace ID and parent under the CLI's execute_tool span. The collector fans all traces back to the CLI's local OTLP receiver (via INFER_TELEMETRY_RECEIVER_ADDRESS: 0.0.0.0:4318), so infer traces shows the full distributed trace, including the mock-agent's spans:
session (standard, success)                 152ms
|-- chat deepseek/deepseek-v4-flash             5ms
|-- execute_tool A2A_SubmitTask              89ms
|   `-- a2a.request [mock-agent]             52ms
`-- chat deepseek/deepseek-v4-flash            12ms
Ingested foreign spans are labeled name [service] from the producer's service.name resource attribute - for example a2a.request [mock-agent].
To run the example:
cd examples/a2a-traces
cp .env.example .env   # set at least one provider API key
docker compose up -d --build
docker compose attach cli
# In the CLI, ask: "Ask the mock-agent to summarize the current project."
# Detach with ctrl-p ctrl-q, then:
docker compose exec cli infer traces
See the example README for full configuration notes and troubleshooting.
Limitations
- Interactive (tmux-pane) subagents are not stitched into the caller's trace - only headless subagents inherit the context. Use
mode: headlesswhen you need a subagent's spans in the same trace. - Detached background shells that outlive the CLI lose late spans - once the CLI (and its ephemeral receiver) exits, spans emitted afterward have nowhere local to land. Configure a persistent
telemetry.otlp.endpointfor long-running detached work.
Viewing telemetry data
Local files - the JSONL files under
~/.infer/telemetry/are plain text and can be inspected with any JSON tool:bash# List telemetry files ls ~/.infer/telemetry/ # View metrics for a session cat ~/.infer/telemetry/\<session-id\>.jsonl | jq . # View traces for a session cat ~/.infer/telemetry/\<session-id\>-traces.jsonl | jq .infer stats- aggregates metrics from local files into a summary of tool outcomes, token usage, and sessions. Trace files are excluded from the aggregate. The per-tool Avg column renders microseconds (for example432us) when the mean duration is below 1ms and milliseconds otherwise, so fast tools no longer collapse to0ms. Ininfer stats --format jsonthe matchingavg_msfield can be fractional (for example0.432) rather than an integer. The same applies toinfer insightsand the/statsshortcut.infer traces- renders the span tree of a session from its local trace file. See Viewing traces.infer insights- analyzes past sessions for repeatable workflows and recurring tool failures. The verbatim error and log samples it collects are redacted before the model call - PEM private-key blocks, GitHub token shapes, and the values of provider-secret env vars (plain and JSON-escaped) are replaced with[redacted], in the digest and in the saved report alike. See Insights Shortcut.Remote backend - when OTLP export is configured, data appears in your collector's configured backend (Jaeger for traces, your metrics store).
Viewing traces
infer traces renders the span tree of a session - the session root span, its LLM turns, and the tool calls nested under each turn - with a duration next to every span. It reads the local per-session trace file (~/.infer/telemetry/\<session-id\>-traces.jsonl) directly, so it works fully offline with no OTLP collector required.
# Render the most recent session's span tree
infer traces

# Render a specific session by ID
infer traces abc-123-def

# List the sessions that have trace files
infer traces --list

# Emit the tree as structured JSON
infer traces --format json
With no session ID, infer traces picks the most recent session. The default output is an indented span tree:
session (standard, success)                38.8s
|-- chat ollama_cloud/deepseek-v4-flash     3.4s
|-- execute_tool Read                      162us
`-- chat ollama_cloud/deepseek-v4-flash     8.1s
Spans that finished with an error status (or carry an error.type attribute) are flagged inline with an [error: ...] marker showing the error type - for example [error: context_deadline_exceeded].
Spans ingested from subprocesses appear in the same tree, nested under the execute_tool span that spawned them - Bash tool commands (including otel-cli and OpenTelemetry-SDK-instrumented programs) and headless subagents. See Trace context propagation to subprocesses for how the context is passed and where child spans are collected.
Spans ingested from external producers (for example a remote A2A agent or an OpenTelemetry Collector) are labeled with the producer's service.name resource attribute: name [service]. For example, a span named a2a.request from a service called mock-agent renders as a2a.request [mock-agent] in the tree. This makes it easy to identify which service produced each span in a distributed trace.
--format json emits the same tree as structured output - each node carries the span name, start time, duration in fractional milliseconds, attributes, and an array of child spans - ready to pipe into jq or a custom viewer:
{
  "name": "session",
  "start_time": "2026-07-14T09:12:03.145Z",
  "duration_ms": 38800.0,
  "attributes": {
    "infer.execution.mode": "standard",
    "infer.run.outcome": "success"
  },
  "children": [
    {
      "name": "chat ollama_cloud/deepseek-v4-flash",
      "start_time": "2026-07-14T09:12:03.150Z",
      "duration_ms": 3400.0,
      "attributes": { "gen_ai.request.model": "deepseek-v4-flash" },
      "children": []
    }
  ]
}
The same view is available inside a chat session with the /traces shortcut.
Shortcuts
The CLI provides built-in commands, YAML shortcuts, and Agent Skills - all reachable by typing / in chat.
Autocomplete kinds
Typing / opens the autocomplete list, and every row carries a kind label telling you what it is and where it comes from (the same labels the desktop composer uses):
| Label | What it is | Where it lives |
|---|---|---|
command | Built-in shortcut compiled into the CLI - views and wizards it implements itself | The binary - see Built-in Commands |
shortcut | YAML shortcut, including the ones infer init seeds | .infer/shortcuts/*.yaml - see YAML Shortcuts |
skill | Installed Agent Skill - /<name> activates it for the turn | ./.infer/skills/ or ~/.infer/skills/ |
remote skill | Catalog skill not installed yet - /<name> downloads it first (confirmed in chat) | The skills catalog |
A command always wins over a YAML shortcut of the same name, so a stale shortcut file can never shadow a built-in view. See Shortcut precedence.
Built-in Commands
These show as command in autocomplete:
| Shortcut | Description | Example |
|---|---|---|
/model [name] [msg] | Switch the active model, or run one message with another model | /model deepseek/deepseek-v4-flash |
/init | Fill the input with the AGENTS.md project-analysis prompt | /init |
/agents | View every configured agent - local Markdown presets and remote A2A agents - with their state | /agents |
/tasks | View background work (A2A tasks, shells, subagents) with live status and captured output | /tasks |
/tools | View a filterable list of tools available in the current agent mode, including MCP tools | /tools |
/artifacts | Browse the current session's artifacts and save one here | /artifacts |
/stats | Summarize the session's token usage, tool outcomes, and cost (mirrors infer stats) | /stats |
/traces [id] | Render a session's trace span tree offline (mirrors infer traces) | /traces, /traces abc-123-def |
/voice [seconds] | Record the mic and transcribe to the input field (requires speech-to-text) | /voice, /voice 8 |
/reload | Re-read config files and INFER_* env, applying the hot keys | /reload |
Installing the infer-action workflow is not one of them - it is the opentask catalog skill, mentioned as /opentask <context> in a normal chat turn. A /name no command or shortcut answers for is sent to the agent as an ordinary message, so a skill mention or a typo never dead-ends.
YAML Shortcuts
infer init seeds these into ~/.infer/shortcuts/, so they show as shortcut in autocomplete. They are ordinary custom shortcuts - editable, removable, and replaceable with your own:
| Shortcut | Description | Example |
|---|---|---|
/git <cmd> | Git operations | /git status, /git commit, /git push |
/scm <cmd> | GitHub operations | /scm issues, /scm issue 123 |
/mcp <cmd> | Manage MCP servers | /mcp list, /mcp add |
/skills <cmd> | Manage Agent Skills | /skills list, /skills install <url> |
/shells | List running and recent background shells | /shells |
/export | Export the current conversation to Markdown | /export |
/env | Generate a .env.example with the provider API keys | /env |
/insights [since] | Analyze past sessions for repeatable workflows and recurring tool failures (secrets redacted before the model call and before the report is saved) | /insights, /insights 7d |
/reset [arg] | Wipe all local runtime state on this machine and start a fresh session | /reset, /reset confirm |
Git Shortcuts
# Execute git commands
/git status
/git branch

# AI-generated commit message
/git commit

# Push to remote
/git push origin main
SCM (GitHub) Shortcuts
# List GitHub issues
# Runs: gh issue list --json ... --limit 20
/scm issues

# View issue details
# Runs: gh issue view 123 --json ...
/scm issue 123
The seeded scm.yaml defines only these two subcommands. For pull-request work, ask the agent directly - gh pr create is a write, so it falls through to approval - or add your own subcommand to the shortcut file.
Telemetry Shortcuts
/stats and /traces surface the CLI's local telemetry from inside a chat session, mirroring the infer stats and infer traces commands.
/statssummarizes the session's token usage, tool outcomes, and cost. Its markdown and vertical views use the same duration formatting asinfer stats: the Avg column shows microseconds (for example432us) below 1ms and milliseconds otherwise./traces [session-id]renders the span tree of a session - the session root, its LLM turns, and the tool calls under each turn - with per-span durations. With no argument it shows the most recent session.
session (standard, success)                38.8s
|-- chat ollama_cloud/deepseek-v4-flash     3.4s
|-- execute_tool Read                      162us
`-- chat ollama_cloud/deepseek-v4-flash     8.1s
Both read the local files under ~/.infer/telemetry/, so they work fully offline. See Viewing traces for the infer traces command, its --list and --format json flags, and how error spans are marked.
Insights Shortcut
/insights [since] (and the equivalent infer insights) analyzes past sessions for repeatable workflows worth turning into a skill and for recurring tool failures. The optional since argument limits the window (for example /insights 7d). It reads local sessions and telemetry, builds a digest, sends that digest to the configured model, and writes the report to ~/.infer/insights/.
Secrets are redacted locally before any network call. The digest is masked before it reaches the analysis model, and the saved report is masked before it is written to disk. Redaction covers:
- PEM private-key blocks (always on).
- GitHub token shapes:
ghp_,gho_,ghu_,ghs_,ghr_, andgithub_pat_. - The values of provider-secret environment variables set in the environment, both plain and JSON-escaped (so a key quoted inside a captured JSON payload is masked too).
Each match is replaced with [redacted]. Because the masking runs before the model call and before the file write, pointing insights at collected sessions does not ship verbatim API keys or private keys to the provider, and the report you keep or share carries the same guarantee. Redaction targets known secret shapes and configured provider-secret values - it is not a substitute for keeping unrelated sensitive data out of session transcripts.
If conversation storage is disabled or no model is configured, the analysis is skipped with a notice.
Reset Shortcut
/reset wipes the CLI's local runtime state on the whole machine - not just the current project - and starts a fresh session. It is a two-step shortcut: a bare /reset only previews, and /reset confirm performs the wipe.
# Preview what would be deleted (deletes nothing)
/reset

# Analyze the sessions first, then preview
/reset insights

# Actually delete everything listed in the preview
/reset confirm
Both steps end with a disk-space total: the preview ends with Total reclaimable space: <size>, and /reset confirm ends with Total reclaimed space: <size> after the wipe. The confirm total counts only targets that were actually removed, so anything the wipe failed to delete is excluded. Sizes are formatted like docker system prune - decimal units and 4 significant digits (for example 1.653GB, 4.096kB). The same totals appear when running infer reset and infer reset confirm directly.
/reset confirm only deletes after a preview was shown in the same session (within the last 5 minutes). A cold /reset confirm prints the preview instead, so a tab-completed confirm cannot wipe anything by accident.
Deleted, for every project under ~/.infer/projects/: conversations, plans, scratch dirs, artifacts, history, backups, exports, logs, telemetry, schedules, pid/lock files, and both tmp trees including their media roots (generated speech, music, video, screen recordings, screenshots, retained voice recordings and attachments). With the SQLite backend the conversation database and its WAL sidecars go too.
Preserved: configuration (config.yaml, custom shortcuts, skills, projects.yaml), the avatar library under ~/.infer/avatars/, and saved insights reports under ~/.infer/insights/ (written redacted). Directories you pointed outside ~/.infer (for example a text_to_speech.output_dir of /data/tts) are left alone.
Remote conversation stores are skipped. If storage.type is postgres, redis, or d1, /reset clears local state only and prints a notice that the remote store was left untouched - it is not an error.
/reset insights runs the /insights analysis (repeatable workflows worth turning into a skill, recurring tool failures) before the preview, so you can capture what past sessions were worth learning from before deleting them. The report is written to ~/.infer/insights/ - with secrets redacted, as for any insights run - and survives the reset. If conversation storage is disabled or no model is configured, the analysis is skipped with a notice and the preview is still shown.
Voice Shortcut
The /voice shortcut records audio from your microphone, transcribes it locally with whisper.cpp, and places the text into the input field - ready to review and send. It is disabled by default and only appears when speech_to_text.enabled is true.
# Record until you go quiet (or the max cap), then transcribe
/voice

# Record for at most 8 seconds
/voice 8
Recording stops automatically a couple of seconds after you stop speaking (speech_to_text.silence_timeout), at the max_recording_seconds cap, or at the per-call override. See Speech-to-Text for prerequisites, configuration, and model selection.
GitHub Action Setup
Installing or updating the infer-action GitHub Action workflow has no dedicated CLI surface - it is the agent's job. Mention the opentask catalog skill as /opentask <context> in a normal chat turn and the run streams like any other turn, with every write going through normal tool approval.
For a full reference of
infer-actioninputs, outputs, and workflow recipes (PR review, scheduled summaries, release notes), see the GitHub Action documentation.
Say what you want in the context: the repository to target if it is not the current checkout, and any workflow configuration such as a model or a timeout.
infer chat
> /opentask install the GitHub Action workflow
> /opentask install the workflow in my-org/my-service, model: deepseek/deepseek-v4-flash
What the agent does:
- Reads the
opentaskskill, which carries the canonicalinfer-actionworkflow and its example workflows - it works from the skill rather than fetching docs over the network. - Adds a git worktree under
/tmpwhen the target is the current checkout, or shallow-clones the target repository, so your working branch is never touched. - Checks out the fixed branch
infer/install-github-action, on top of the remote branch if one already exists. - Creates or updates
.github/workflows/tasks.yml, following both the skill's canonical workflow and the repository's existing CI conventions. - Summarizes the diff, then commits, pushes, and opens or updates the pull request - asking for your approval on the push and on the PR.
Asking again updates that same branch and pull request instead of opening a duplicate.
Prerequisites: the GitHub CLI installed and authenticated (gh auth login), with write access to the target repository.
Repository secrets: the generated workflow expects these in the target repository, or in its organization:
INFER_APP_ID- GitHub App ID, when authenticating as a GitHub App instead of with the defaultGITHUB_TOKENINFER_APP_PRIVATE_KEY- the App's private key (.pemcontents)- Provider API keys (
ANTHROPIC_API_KEY,OPENAI_API_KEY,DEEPSEEK_API_KEY, and so on)
For organization repositories the CLI checks whether the INFER_APP_* org secrets already exist, so an App registered once can be reused across repositories. See Secrets and least-privilege for why an App token beats GITHUB_TOKEN.
Usage in issues: once the workflow is merged, mention @infer in any issue or issue comment to activate the agent:
@infer Please analyze this bug and suggest a fixFor more information on the infer-action GitHub Action, see the GitHub Action documentation or the upstream repository.
Custom Shortcuts
Create YAML files in .infer/shortcuts/ directory. Shortcuts support three types:
1. Simple Commands
Execute a single command:
# .infer/shortcuts/simple.yaml
shortcuts:
  - name: hello
    description: 'Say hello'
    command: echo
    args:
      - 'Hello from Inference Gateway!'
2. Shortcuts with Subcommands
Group related commands under a parent shortcut:
# .infer/shortcuts/dev.yaml
shortcuts:
  - name: dev
    description: 'Development operations'
    command: bash
    subcommands:
      - name: test
        description: 'Run all tests'
        command: bash
        args:
          - -c
          - 'go test ./...'

      - name: build
        description: 'Build the project'
        command: bash
        args:
          - -c
          - 'go build -o app .'
A subcommand that declares its own command: runs that command with its args verbatim - /dev test runs bash -c 'go test ./...'. A subcommand without its own command: reuses the parent's command and gets its name (then its args) appended to the parent's args, so spell out the full invocation in every subcommand.
Usage: /dev test, /dev build
3. AI-Powered Snippets
Use LLM to generate dynamic content based on command output. The snippet.prompt can reference JSON fields from command output using {fieldName} placeholders, and snippet.template uses {llm} for the AI-generated response:
# .infer/shortcuts/ai-commit.yaml
shortcuts:
  - name: ai-commit
    description: 'AI-generated commit message'
    command: bash
    args:
      - -c
      - |
        diff=$(git diff --cached)
        jq -n --arg diff "$diff" '{"diff": $diff}'
    snippet:
      prompt: "Generate commit message for:\n{diff}"
      template: '!git commit -m "{llm}"'
The command must output JSON. Fields are accessible in the prompt template via {fieldName} syntax. The LLM response is accessible via {llm} in the template.
Name collisions with built-ins
A built-in command always wins over a custom YAML shortcut of the same name - the custom one is skipped with a warning naming the file, so a stale shortcut file can never shadow a built-in view such as /agents. Rename the custom shortcut to reach it again.
Advanced Features
Cost Tracking
Real-time token usage and cost calculation displayed in the status bar.
Features:
- Per-model pricing calculation
- Cumulative session costs
- Input and output token tracking
- Status bar indicator
- Custom pricing support
View Costs:
# Costs displayed in status bar during chat
infer chat
# Status bar shows model and current cost

# Inspect a saved conversation's entries (per-entry metadata, including model)
infer conversations show <session-id>

# Same, as one JSON object for piping into jq
infer conversations show <session-id> --format json | jq .
Pricing Configuration
Pricing lives under the pricing key in .infer/config.yaml. The custom_prices map overrides or adds entries to the built-in per-model pricing table, keyed by model name.
# .infer/config.yaml
pricing:
  enabled: true
  currency: 'USD'
  custom_prices:
    'ollama_cloud/deepseek-v4-pro':
      input_price_per_mtoken: 0.0
      output_price_per_mtoken: 0.0
requires_pro: true| Field | Type | Description |
|---|---|---|
input_price_per_mtoken | number | Cost per 1M prompt (input) tokens, in currency. |
output_price_per_mtoken | number | Cost per 1M completion (output) tokens, in currency. |
requires_pro | boolean | Marks the model as gated behind a paid Pro subscription. Defaults to false. |
Subscription-gated models are billed at zero session cost regardless of the rates on the entry. Use non-zero rates with requires_pro: true to keep an informational rate in the picker label while a flat-fee subscription covers the actual billing:
pricing:
  enabled: true
  custom_prices:
    ollama_cloud/glm-5.3-flash:
      input_price_per_mtoken: 0.15
      output_price_per_mtoken: 0.50
      requires_pro: true # informational rate only, billed as flat-fee subscription
Override caveat: a
custom_pricesentry fully replaces the default for that model - it is not merged field by field. Omittingrequires_proin a custom override therefore resets it tofalse, even when the model is flagged Pro by default. Setrequires_pro: trueexplicitly when overriding the pricing of a Pro model.
Model Categories (Free / Pay-as-you-go / Subscription)
The model picker's pricing tab row - [1] All, [2] Free, [3] Pay-as-you-go, [4] Subscription - groups models into three disjoint categories:
| Category | Meaning |
|---|---|
| Free | No per-token cost and not subscription-gated. |
| Pay-as-you-go | Billed per token. |
| Subscription | Gated behind a paid subscription rather than per-token billing. |
Subscription is an axis orthogonal to price: an Ollama Cloud model is not metered per token but is not free, so it is labelled pro subscription rather than free. A subscription model may still carry a per-token rate - the gateway keeps the provider's pay-as-you-go rate for reference - in which case the picker shows the rate with a subscription suffix. The marker appears both in the picker rows and in /model autocomplete descriptions:
ollama_cloud/deepseek-v4-pro   (1M, pro subscription)
ollama_cloud/glm-5.3-flash     (1M, $0.15/$0.50 per MTok, subscription)
deepseek/deepseek-v4-flash     (1M, $1.74/$3.48 per MTok)
Subscription models cost zero per session. The session cost line and the status-bar cost report $0.00 for any subscription-gated model, even when the picker label shows a rate - the rate is informational and the flat-fee subscription covers usage. This applies whether the model is flagged by the gateway (pricing.subscription: true) or by a custom_prices entry with requires_pro: true, as in the example above.
The classification comes from the gateway's pricing metadata - the pricing.subscription flag reported per model - so it tracks the gateway catalog with no CLI-side list to maintain. A custom_prices entry still wins: set requires_pro: true to gate a model the gateway does not flag, or false to un-gate one (remembering the override caveat that an entry fully replaces the default).
The gateway flag replaced the previous hardcoded list of Pro models. Subscription models with per-token rates bill at zero cost while keeping their published rates.
Model Thinking Visualization
Collapsible thinking blocks for models that support thinking (Claude, o1, etc.).
Features:
- Collapsible blocks with first sentence preview
- Ctrl+K keyboard shortcut to toggle
- Theme-aware styling
- Performance optimization (long thinking blocks collapsed by default)
Usage:
infer chat
# Ask complex question requiring reasoning
> "Design a scalable microservices architecture for e-commerce"
# Model's thinking process displayed in collapsible blocks
# Press Ctrl+K to expand/collapse thinking
Conversation Management
Storage Backends:
- JSONL (default): append-only files under
~/.infer/projects/<project-slug>/conversations/ - SQLite: one shared database at
~/.infer/conversations.db - PostgreSQL: Shared team database
- Redis: High-performance caching
- Cloudflare D1: External SQLite over Cloudflare's HTTP query API
- In-memory: Temporary sessions
The message queue is configured separately through queue.* and reuses these same storage.<type> connection settings when it runs on a durable backend.
Features:
- Automatic conversation history
- AI-generated titles (batch: 10 messages)
- Token optimization with compaction
- Backend-agnostic inspection via the storage layer (works the same across
jsonl,sqlite,postgres,redis,d1, andmemory)
Where conversations live:
Conversations are stored in your home directory, grouped per project - nothing conversation-related is written to the project directory:
- jsonl:
~/.infer/projects/<project-slug>/conversations/<id>.jsonl, where<project-slug>is the absolute project path with the separators replaced (/home/alice/repobecomes-home-alice-repo). - sqlite: one shared database at
~/.infer/conversations.db, with each row carrying aprojectcolumn. - postgres, redis, d1: one shared store, grouped by the same
projectfield in the conversation metadata.
Every session records the project it ran in (its absolute working directory), and listings scope to the current project by default: the /conversations TUI picker shows only this project's conversations, and so does infer conversations list - pass --all-projects to list every project's conversations.
An explicit storage.jsonl.path or storage.sqlite.path always overrides these defaults, and such a store only ever lists itself.
Searching the picker:
The /conversations picker footer reads Press / to search whenever no query is active. Press / to open the search box, type to filter the listed conversations by a case-insensitive substring, and press Esc to clear the query and leave search. The box takes every printable character - accented letters, CJK, emoji and the space bar all land in the query - and Backspace removes one character rather than one byte. Deleting a conversation works from a filtered list too: narrow the list with a search, select the row and confirm the delete dialog - the removed row leaves both the filtered and the full list.
No migration. Stores written by older versions under the project's
.infer/conversationsor.infer/conversations.dbare orphaned by design - the CLI no longer reads or writes them. Delete them manually when you no longer need them. The generated.infer/.gitignoreno longer ignoresconversations/conversations.db*.
Subcommands:
list: List saved conversations with metadata (id, title, message/request counts, tokens, cost). Scoped to the current project;--all-projectslists every project's conversations.show <session-id>: Print a single conversation's entries in chronological order (role, timestamp, content, andtool_call_idfor tool results). By default only the first 10 entries are printed so a carelessshowdoes not flood its reader (a shorter session is never windowed) - see theshowflags below.delete <session-id>: Remove a conversation from the storage backend. Runs non-interactively with no confirmation prompt. Unknown or missing session id exits non-zero with an error from the storage layer.
delete notes:
- Runs non-interactively - no confirmation prompt, so scripts and the desktop app can shell out to it.
- Unknown or missing session id exits non-zero with a clear error from the storage layer (e.g.
conversation not found: <id>). - Session id resolution follows the same rules as
show(see below).
show flags:
--include-hidden: Include entries persisted as hidden - system reminders, plan-approval prompts, drained background-task results, and the synthetic verify message injected byinfer headless. Off by default.--format text|json:text(default) is human-readable -jsonemits one pretty-printed JSON object withmetadataandentries(plus atruncatedflag when the output was windowed), so a whole conversation parses in onejqcall.--grep <substring>: Only show the entries whose text contains the substring (case-insensitive), so a long session can be cherry-picked entry by entry without dumping the rest.--no-trunc: Print every entry instead of the default first-10 window.--append,-a: Print the entries after the default first-10 window instead of the window itself, so a long session can be read in chunks.--no-truncwins when both are passed.
Session id resolution:
<session-id> is resolved the same way as infer headless --session-id and infer chat --session-id: a literal UUID is used as-is, while any other value is treated as a session group key and resolved to that group's current session id (registering the group if it is new). This means you can show a conversation by group name such as channel-telegram-12345.
Commands:
# List this project's conversations to find a session id
infer conversations list

# List conversations from every project
infer conversations list --all-projects

# Show a conversation's entries (hidden entries omitted by default)
infer conversations show 12345678-1234-1234-1234-123456789abc

# Show by session group name (for example a channel group key)
infer conversations show channel-telegram-12345

# Include hidden entries such as system reminders
infer conversations show <session-id> --include-hidden

# Only the entries whose text mentions a substring
infer conversations show <session-id> --grep "undefined symbol"

# Show the entries after the default first-10 window
infer conversations show <session-id> --append

# One JSON object for piping into jq
infer conversations show <session-id> --format json | jq .

# Delete a conversation by literal UUID
infer conversations delete 12345678-1234-1234-1234-123456789abc

# Delete by session group key (for example a channel group key)
infer conversations delete channel-telegram-12345
Cloudflare D1 backend
Cloudflare D1 is an external, SQLite-compatible store the CLI writes to over D1's HTTP query API. It is built for ephemeral CI runners (for example a headless infer headless run on GitHub Actions): unlike sqlite, jsonl, and memory - which live on the runner's disk and are wiped on recycle - D1 persists off-runner and stays readable by the gateway through its native binding. Unlike postgres and redis, it needs no wire-protocol connection, just HTTPS.
Set storage.type: d1 and configure the storage.d1 block:
storage:
  enabled: true
  type: d1
  d1:
    account_id: '<cloudflare-account-id>'
    database_id: '<d1-database-id>'
    api_token: '<api-token-with-d1-edit>' # inject via INFER_STORAGE_D1_API_TOKEN
    base_url: 'https://api.cloudflare.com/client/v4' # optional
Environment variables:
| Variable | Description |
|---|---|
INFER_STORAGE_D1_ACCOUNT_ID | Cloudflare account id that owns the D1 database. |
INFER_STORAGE_D1_DATABASE_ID | Target D1 database id. |
INFER_STORAGE_D1_API_TOKEN | API token with D1 edit permission. Secret - inject, never commit. |
INFER_STORAGE_D1_BASE_URL | Optional API base URL. Defaults to https://api.cloudflare.com/client/v4. |
Notes:
- No manual migration. Like
jsonl,redis, andmemory, D1 creates its schema automatically on first connect - there is no separate migration step to run. - Schema parity. The D1 driver runs the SQLite migrations verbatim over HTTP, so the
conversationsandsession_groupstables stay byte-for-byte compatible with the SQLite backend - either side can initialise the database. - UTC timestamps. Timestamps are stored as UTC RFC3339 so
ORDER BY updated_at DESCsorts stably across runners in any timezone and external reads stay unambiguous. - Secret handling.
api_tokenfollows the existing plaintext-config + env-override convention (like the Postgres password) and is never logged - inject it viaINFER_STORAGE_D1_API_TOKEN.
Message Queue
The message queue holds messages waiting for the agent to pick up on its next availability - text typed while a turn is running, background-job completion notes, and work pushed in by other processes. Its backend is configurable, independently of conversation storage:
| Backend | Survives a restart | Shareable across processes | Connection settings |
|---|---|---|---|
memory (default) | no | no | - |
sqlite | yes | yes | storage.sqlite |
postgres | yes | yes | storage.postgres |
redis | yes | yes | storage.redis |
# .infer/config.yaml
queue:
  type: redis # memory (default), sqlite, postgres or redis
  name: '' # queue scope, empty means this process's session id
poll_interval: 2s # cross-process wake-up cadence, durable backends only- queue.type (
INFER_QUEUE_TYPE): backend for the queue, defaultmemory. It is deliberately separate fromstorage.type- the storage defaultjsonlis not a queue backend, and followingstorage.typewould silently make the default queue durable.jsonlandd1are rejected by config validation. Non-memory backends reuse the matchingstorage.<type>connection settings, so a queue never grows a second host/port/password block. - queue.name (
INFER_QUEUE_NAME): the queue scope, resolved once at startup. Empty means this process's session id, so two local sessions never take each other's typed messages - but a new session is a new scope, so nothing carries over a restart. Set the same explicit name on every process that should consume the work, and on every external producer. - queue.poll_interval (
INFER_QUEUE_POLL_INTERVAL): how often a durable backend is polled for entries written by someone else, default2s. An idle agent is woken within that interval, so producers never talk to infer directly.
Semantics:
- FIFO per scope, oldest message first.
- A drain takes every message out in one atomic step, so two processes draining at the same time never receive the same message.
- Delivery is at-most-once, as with the process-local queue: a drained message lost to a crash before it reaches the conversation is gone. Ack and redelivery are out of scope.
- An unreachable backend fails startup with an error naming the backend - it never silently falls back to
memory. chat.status_bar.indicators.queuegates the status-bar indicator. The memory queue hides it while empty, a durable backend is always visible and names the backend (redis, orredis 3 queuedwhile work waits), rendered in the error color while the backend is unreachable.
Feeding the queue from outside infer
External producers enqueue by writing one JSON record to the configured backend:
| Field | Type | Notes |
|---|---|---|
role | string | SDK role of the message, "user" for user work |
content | JSON | the SDK message content - a plain text message is a JSON string |
source | string | one of composer, stdin, a2a, shell, subagent, job; use a2a for work another agent pushes |
request_id | string | free-form producer-supplied id for tracing and ordering, empty allowed |
queued_at | RFC3339 timestamp | when the producer created the entry |
Redis keeps one list per queue scope at infer:queue:<name>, oldest entry at the head:
redis-cli RPUSH infer:queue:my-shared-queue '{
  "role": "user",
  "content": "run the nightly regression checks",
  "source": "a2a",
  "request_id": "nightly-2026-10-12",
  "queued_at": "2026-10-12T20:00:00Z"
}'
RPUSH appends to the tail and infer consumes from the head, so producers never prepend. LRANGE infer:queue:<name> 0 -1 reads the queue without consuming it.
SQLite and PostgreSQL share the message_queue table (queue_name, role, content, source, request_id, queued_at, plus an id sequence key that defines the FIFO order and must not be set by hand). The consumer drains it with a single DELETE ... RETURNING statement, which on PostgreSQL locks rows with FOR UPDATE SKIP LOCKED:
INSERT INTO message_queue (queue_name, role, content, source, request_id, queued_at)
VALUES (
  'my-shared-queue',
  'user',
  '"run the nightly regression checks"',
  'a2a',
  'nightly-2026-10-12',
  NOW()
);
Persistent Memory
The Memory tool gives the agent durable, cross-session memory: facts it learns in one session survive into the next. Each fact is a single Markdown fact-file (with YAML frontmatter) stored under a configurable directory - ~/.infer/memory by default - and catalogued by a MEMORY.md index. That index is injected into context at the start of every session, so the agent always knows what it has recorded; it then reads or writes individual facts on demand. A default system reminder (memory-consult) nudges it to consult and keep memory current. Memory is enabled by default.
Per-project fact organization
Facts are organized by project to keep memory relevant and scoped:
- Project facts live in per-project subdirectories:
<project-slug>/<slug>.md(e.g.inference-gateway-cli/build-commands.md). - Global facts stay at the memory directory root (e.g.
user-preferences.md). - Legacy flat files (pre-existing fact-files at the root) keep working as global facts - no migration needed.
The project is detected automatically:
- Git remote origin is resolved to
org/repo(e.g.inference-gateway/cli). - If no git remote is found, the current working directory basename is used.
- If neither is available, the fact is stored as global.
Fact frontmatter
Each fact-file includes YAML frontmatter that records its metadata:
---
name: build-commands
description: how to build the CLI
metadata:
  type: project
  project: inference-gateway/cli
  session: channel-telegram-12345
---| Field | Description |
|---|---|
name | Short slug identifying the fact (e.g. build-commands). |
description | One-line summary shown in the MEMORY.md index. |
metadata.type | Fact type: user, feedback, project, or reference. |
metadata.project | Human-readable org/repo that owns this fact. Omitted for global facts. |
metadata.session | The session ID that last wrote the fact (e.g. channel-telegram-12345). |
Index filtering
The MEMORY.md index injected at session start is filtered to show only:
- Entries for the current project (facts under the detected project slug).
- Global entries (facts at the memory directory root).
A single summary line at the bottom names other projects that have facts but are not shown. The full unfiltered index (all projects) is always available by calling Memory read with no name.
Not the same as
storage.type: memory. This is the agent's knowledge memory - durable facts on disk under~/.infer/memory. Thememoryconversation storage backend is unrelated: an in-RAM transcript store that is wiped when the process exits.
The Memory tool
Memory is a Workflow tool whose operation parameter selects one of three actions:
| Operation | Parameters | Effect |
|---|---|---|
read | name (optional) | With no name, returns the MEMORY.md index; with a name, that fact-file. |
write | name, description, type, content (all required), project (optional) | Creates or updates a fact-file and its index entry. |
delete | name (required) | Removes a fact-file and its index entry. |
name is a short slug (for example build-commands) for global facts, or project/slug (for example inference-gateway-cli/build-commands) for project facts - exactly as shown in the MEMORY.md index. description is the one-line summary shown in the MEMORY.md index, content is the Markdown fact body, and type is one of user, feedback, project, or reference.
The optional project argument on write controls where the fact is filed:
project value | Behavior |
|---|---|
| (omitted) | Defaults by type: user facts are global; feedback/project/reference go under the detected project. |
global | Forces the fact to be stored at the memory directory root (a global fact). |
org/repo | Files the fact under another project's subdirectory (e.g. inference-gateway/cli). |
Configuration (memory.yaml)
Runtime knobs live in memory.yaml (seeded by infer init; the in-code defaults apply when the file is absent):
# .infer/memory.yaml (or ~/.infer/memory.yaml)
enabled: true
dir: '' # "" => ~/.infer/memory
max_chars: 2000 # cap on the MEMORY.md index injected into context (truncates at line boundary)
max_entry_chars: 2000 # per-fact write cap (0 = default)| Key | Default | Environment variable | Description |
|---|---|---|---|
enabled | true | INFER_MEMORY_ENABLED | Master switch - registers the Memory tool and the index injection. |
dir | ~/.infer/memory | INFER_MEMORY_DIR | Directory holding the fact-files and MEMORY.md. "" = default. |
max_chars | 2000 | INFER_MEMORY_MAX_CHARS | Upper bound on the MEMORY.md index injected at session start. Truncation respects line boundaries. |
max_entry_chars | 2000 | INFER_MEMORY_MAX_ENTRY_CHARS | Per-fact character cap on write content. 0 means use the default. |
The memory directory is local by default. To back it with a git remote - pull on run start, commit and push on change - configure a Sync backend.
Sync backend
By default the memory directory lives on a single machine (backend.type: local, a pure no-op). Point the backend at a git remote to share one memory across machines, CI runners, channels, and scheduled runs: the CLI pulls on run start and commits + pushes on change.
# .infer/memory.yaml (or ~/.infer/memory.yaml)
enabled: true
dir: '' # "" => ~/.infer/memory
max_chars: 4000
backend:
  type: local # local (default) | git
  git:
    repo: 'git@github.com:my-org/agent-memory.git'
    branch: main
    commit_message: 'chore(memory): sync'
    timeout: 60 # seconds per git op
    sync:
      on_start: pull # pull (default) | off
      on_finish: push # push (default) | off
type: local is the default and a pure no-op - existing users see no change.
| Key | Default | Environment variable | Notes |
|---|---|---|---|
backend.type | local | INFER_MEMORY_BACKEND_TYPE | local (no-op) or git. |
backend.git.repo | '' | INFER_MEMORY_BACKEND_GIT_REPO | Remote URL. Required when type: git. |
backend.git.branch | main | INFER_MEMORY_BACKEND_GIT_BRANCH | Branch to track. |
backend.git.commit_message | chore(memory): sync | INFER_MEMORY_BACKEND_GIT_COMMIT_MESSAGE | Deterministic, non-LLM commit message. |
backend.git.timeout | 60 | INFER_MEMORY_BACKEND_GIT_TIMEOUT | Seconds per git op (prevents credential hangs). |
backend.git.sync.on_start | pull | INFER_MEMORY_BACKEND_GIT_SYNC_ON_START | pull or off. |
backend.git.sync.on_finish | push | INFER_MEMORY_BACKEND_GIT_SYNC_ON_FINISH | push or off. |
Validation: when memory is enabled and type: git, repo is required; on_start must be pull or off, and on_finish must be push or off.
How it syncs
- On run start (SyncIn). Clones the repo when the memory dir is missing, otherwise fast-forward / rebase pulls. An
ls-remoteprobe decides clone vs. init-in-place - an empty remote, or a pre-existing local memory dir, is initialized in place instead of cloned. - On change (SyncOut). Commits and pushes only when
git status --porcelainreports changes, through a bounded push -> pull-rebase -> retry loop. A per-hostflockserializes concurrent runs (channels / scheduler / heartbeat) so they do not clobber each other. - Where the push happens. In chat, the
Memorytool pushes on each write / delete - not a post-session hook, which would commit-storm once per message. In headless mode, it pulls on start and pushes once at run finish. Either way it works across channel, scheduler, and heartbeat subprocess runs. - Best-effort, never fatal. A failed clone / pull / push is logged and the run continues - sync never aborts the agent run.
Authentication
Sync uses the ambient git credential chain - ssh-agent, a git credential helper, or GIT_* environment variables. The backend injects no ssh key or env override of its own, so pick whichever your environment already uses:
- SSH (preferred) - a
git@github.com:...remote plus a loaded ssh-agent key. gh auth- the GitHub CLI credential helper forhttps://remotes.- Token in URL - works, but the CLI logs a warning, because credentials embedded in the remote URL persist in
.git/config. Prefer SSH.
The per-op timeout (default 60 seconds) keeps an interactive credential prompt from hanging a run.
Disabling memory
Turn it off in memory.yaml:
# .infer/memory.yaml (or ~/.infer/memory.yaml)
enabled: false
or via the environment, without touching config:
export INFER_MEMORY_ENABLED=falseWhen disabled, the Memory tool is not registered, no MEMORY.md index is injected, and the memory-consult reminder is pruned automatically.
MCP Integration
Connect to Model Context Protocol servers for extended capabilities. MCP provides stateless tool execution for external services like databases, file systems, and APIs.
Setup:
Seed the userspace baseline, which includes ~/.infer/mcp.yaml:
infer initConfigure MCP servers in ~/.infer/mcp.yaml (or add --project to the infer mcp commands below to write a project-level .infer/mcp.yaml instead):
enabled: true
connection_timeout: 30
discovery_timeout: 30
liveness_probe_enabled: true
liveness_probe_interval: 10

servers:
  # Auto-start MCP server in container (recommended)
  - name: 'demo-server'
    enabled: true
    run: true
    oci: 'mcp-demo-server:latest'
    description: 'Demo MCP server'

  # Connect to a local MCP server - the endpoint spelled out field by field
  # (an entry without them resolves to http://localhost/mcp)
  - name: 'filesystem'
    scheme: 'http'
    host: 'localhost'
    port: 3000
    path: '/sse'
    enabled: true
    description: 'File system operations'
    exclude_tools:
      - 'delete_file'

  # Connect to a hosted MCP server - `url` replaces scheme/host/port/path
  - name: 'agentmail'
    enabled: true
    url: https://mcp.agentmail.to/mcp
    headers:
      x-api-key: ${AGENTMAIL_API_KEY}
infer mcp add <name> <url> splits a URL into the field-by-field form for you, so you rarely need to write those by hand.
Hosted servers (url and headers): url is a full hosted endpoint and takes precedence over scheme/host/port/path, which you then leave out. headers are sent on every request to that server, which is how a hosted server gets its own credential. ${VAR} in a header value is expanded from the environment of the process that loads the file - the daemon or the CLI - so the credential itself never sits in mcp.yaml. An enabled server whose expanded header comes out empty is skipped with a warning and no container is started for it, so a missing key costs you that one server rather than the session.
CLI Commands:
# Add auto-start MCP server
infer mcp add my-server --run --oci=my-mcp:latest

# Add an external MCP server by URL (split into scheme/host/port/path)
infer mcp add filesystem http://localhost:3000/sse

# List MCP servers, or show connection status
infer mcp list
infer mcp status

# Enable or disable a server
infer mcp enable my-server
infer mcp disable my-server

# Start or stop an auto-start (OCI) server
infer mcp start my-server
infer mcp stop my-server

# Update a server definition, or remove it
infer mcp update my-server --oci=my-mcp:2.0.0
infer mcp remove my-server
infer mcp enable-global / disable-global toggle MCP support as a whole rather than a single server.
Using MCP Tools:
MCP tools appear as MCP_<server>_<tool> in chat. Example:
infer chat
> "Use the MCP_demo-server_get_time tool to get current time"
Servers per agent: a Markdown agent picks the servers it uses with mcpServers in its frontmatter, naming servers of this file. Its sessions connect only those, and a server set to enabled: false here still comes up for an agent that names it - so a server can stay off for every chat and serve one agent.
See MCP documentation for detailed integration guide and server development.
Agent Skills
Reusable, model-readable instruction folders that the agent loads on demand. The CLI uses the same on-disk format as Gemini CLI and OpenAI Codex CLI, so a skill authored for any of those tools drops into .infer/skills/ unchanged. Skills are discovered from three locations, in precedence order: project .infer/skills/, the .agents/skills/ open standard (a shared cross-tool convention), then user-global ~/.infer/skills/. Skills are enabled by default - discovered skills are injected into the system prompt out of the box. Only the lightweight metadata (name + description) is added; each SKILL.md body is read on demand. Turn them off with agent.skills.enabled: false, or skip individual skills with disabled_skills.
# .infer/config.yaml
agent:
  skills:
    enabled: true # default
    max_chars: 4000 # cap on the rendered AVAILABLE SKILLS block (0 disables the cap)
disabled_skills: [] # optional list of skill names to skip# Discover, install, and remove skills (also available in chat as /skills ...)
infer skills list
infer skills install acme/internal-comms --user # or a bare name, or a github tree URL
infer skills uninstall internal-commsOnce enabled, invoke a skill explicitly with /<name> (for example /pdf-helper) or by asking the agent to "use the <name> skill"; the CLI deterministically activates it by injecting the skill's metadata and pointing the agent at its SKILL.md. Installed skills under ~/.infer/skills and ./.infer/skills stay readable by the Read tool through a sandbox carve-out, so they load even when the agent runs outside the project directory (for example in CI).
See the full Agent Skills guide for the on-disk layout, the SKILL.md frontmatter contract, install flags, activation triggers, and the sandbox carve-out. To publish a skill in the shared index, see the Skills Catalog.
/tools view
The /tools shortcut opens a read-only, filterable list of the tools available to the agent in the current agent mode. Each row shows the tool name plus a word-wrapped description (up to two lines, with an ellipsis on overflow).
- Filtering: type
/to start filtering; matching terms are underlined in the results. - Status line: shows
N toolsat the bottom. - Live refresh: the list refreshes on every entry, so agent-mode changes and asynchronously registered MCP tools are reflected immediately.
- Mode-aware: Plan mode hides mutating tools (Write, Edit, Delete, Bash), showing only read-only tools.
- MCP tools: dynamically registered MCP tools appear as
MCP_<server>_<tool>once their server is connected.
infer chat
> /tools
/agents view
The /agents shortcut opens the Agents view - the single, filterable list of every agent the chat can delegate to, local and remote alike. There is no separate A2A-only view: each row carries a type chip that says where it comes from.
| Chip | Row | State column | Detail line |
|---|---|---|---|
local | A Markdown subagent preset (an agent file in any of its four locations, labelled user for the ~/.agents ones) that the Agent tool spawns in-process | read-only or read-write | Tool allowlist, model (or inherit), and the source file |
a2a | A remote A2A agent from agents.yaml | Its readiness state | The agent URL, or the failure/progress detail |
Rows are sorted by name, and typing / filters on the chip as well as the name - local narrows the list to presets, a2a to remote agents.
The a2a rows stay live for the session lifetime when liveness probes are enabled:
- An agent still pulling its image shows pull progress (
<done>/<total> layers). - An agent that was down at startup turns green automatically when it becomes reachable.
- An agent that goes down mid-session shows the failure detail inline.
- A recovered agent shows a "Recovered" status.
The status bar A2A: X/Y indicator reflects the same live state and opens this view - X counts down on failures and counts back up on recovery.
infer chat
> /agents  # View local presets and remote A2A agents
/tasks view
The /tasks shortcut opens the background-work panel - a live list of everything running or recently finished outside the current chat turn. Rows are grouped into one table per kind: A2A tasks, background shells, and subagents. Each row shows a status (Running, Completed, or Failed) and an Elapsed column that updates live about once per second while any work is still in flight (the ticker stops once everything is terminal).
infer chat
> /tasks
Selecting a row opens a detail panel with that task's metadata - ID, Detail (the command for a shell, or the task description for a subagent), Status, Started, and Elapsed. A2A rows additionally show their task history and the agent's Final Result; background-shell and subagent rows render an Output section instead.
Output detail section
Selecting a background shell row shows the shell's captured stdout/stderr:
- While the shell is running, the output streams live, refreshed about once per second along with the Elapsed column.
- Once the shell finishes, the panel shows the full captured output, bounded by the shell's output ring buffer.
Selecting a subagent row shows:
- Its run stats - tool calls succeeded and failed, input and output tokens. They count up while a headless subagent runs.
- Its transcript - the task, each assistant turn with the tools it called, and every tool result (a long result is cut at 2 KB). It refreshes every second while anything is running. An interactive subagent's pane runs under the subagent's session ID, so its conversation loads the same way.
- Its final answer instead, when the conversation cannot be loaded (
storage.enabled: false).
Searching tasks
Press / in the panel to open its search box, type to filter the rows by a case-insensitive substring, and press Esc to clear the query and leave search. The box takes every printable character, so accented letters, CJK, emoji and the space bar all land in the query, and Backspace removes one character rather than one byte - a multibyte character disappears in a single press.
The background job list under the composer is the live view of what is running. /tasks is where finished jobs stay for review.
/tasks in a daemon chat
In a daemon chat the panel lists and cancels the jobs of the session's worker - its shells, subagents, recordings and A2A tasks - with their output, stats and a subagent's transcript, over the list_tasks and cancel_task frames. The same frames serve the other daemon clients, the browser extension and the desktop app.
- The view refreshes while a job runs. A job started while nothing was running shows up after reopening
/tasks. - Cancelling asks the worker to stop the job. It ends a moment later, so the panel shows it finished on the next refresh, and a cancelled shell shows as
Failed.
Rendering is bounded so a chatty shell cannot overflow the panel: the Output section shows at most the last 10KB of output. When the captured output is larger, it is prefixed with (truncated, showing last 10KB) and only the trailing 10KB is displayed.
The Output section brings background shells and subagents to parity with the A2A "Final Result" panel. Rows for jobs that expose no output (an A2A task keeps its own Final Result panel) show no Output section.
A2A Integration
Delegate specialized tasks to Agent-to-Agent compatible agents. The A2A client speaks A2A v1.0.1, matching agents built on ADK v0.30.0 or later, while still reading the pre-v1.0.1 task state spellings - see protocol version and task states.
Setup:
# Initialize agents configuration
infer agents init

# Add remote agent
infer agents add calendar-agent http://calendar.example.com

# Add local agent with Docker
infer agents add my-agent http://localhost:8081 --oci ghcr.io/myorg/agent:latest --run

# Add any catalog agent by name only (URL and image derived from its catalog entry)
infer agents add grafana-agent

# Add a built-in agent by name only (browser-agent ships one tag per browser engine)
infer agents add browser-agent --tag lightpanda

# Pin a built-in agent to a released version
infer agents add browser-agent --tag chromium-0.8.0

# List agents
infer agents list

# View agent details
infer agents show calendar-agent

# Update an agent's image tag
infer agents update browser-agent --tag firefox

# Pass environment variables - comma-separated, or the flag repeated
infer agents add my-agent http://localhost:8081 --environment API_KEY=secret,LOG_LEVEL=debug
infer agents add my-agent http://localhost:8081 --environment API_KEY=secret --environment LOG_LEVEL=debug
--environment accepts KEY=VALUE,KEY=VALUE on one flag, and the repeated-flag form still works - the two can be mixed. An empty --environment "" is rejected.
Bare names resolve any agent published in the A2A Registry catalog. The five agents with built-in defaults (browser-agent, mock-agent, google-calendar-agent, documentation-agent, n8n-agent) take precedence and work offline; every other name is looked up in the catalog, with the URL and OCI image derived from its published metadata. A name in neither place needs an explicit URL - see built-in agents vs other catalog agents.
Usage:
infer chat
> "Schedule a meeting tomorrow at 2 PM using the calendar agent"
> /agents  # View connected agents
See A2A documentation for creating custom agents, or use the ADL CLI to scaffold new A2A agents from YAML definitions.
Agent Credentials
An agent that protects its /a2a endpoint gets an auth block in its agents.yaml entry - a static bearer token or an OIDC client-credentials grant, with the secret read from an environment variable named in the block. See authenticating to A2A agents for the fields.
Which requests carry them: every request the CLI makes to that agent. The agent card fetch, task submission, background task polling, task cancellation, and the liveness probe behind infer agents status all send the Authorization: Bearer header.
Where they go: credentials are matched by the scheme, host and port of the agent's configured url and are sent only to that origin. Another origin, a redirect target, and another service on the same host do not receive them.
What the model sees on failure: a missing environment variable, a failed token request, or a 401/403 from the agent is reported to the model as one line, without the response body:
Authentication failed for A2A agent "billing": 401 UnauthorizedA background task whose polling is rejected ends as failed. infer agents show prints the mode and the variable name, so a missing variable is visible without exposing a secret.
A2A Liveness Probes
When A2A agents are configured, the CLI periodically re-probes them for the lifetime of the session instead of checking them only once at startup. This means an agent that was down at startup turns green automatically when it becomes reachable, and an agent that goes down mid-session is reflected in the A2A: X/Y indicator and the a2a rows of the /agents view.
How probes work:
- External agents (URLs in
a2a.agents) are probed via their agent card (/.well-known/agent-card.json). - Local Docker agents are probed via
GET <url>/health. - Status updates are emitted only on state changes (no noisy per-probe output).
- Probes shut down cleanly when the session ends.
Configuration:
# .infer/config.yaml
a2a:
  enabled: true
  agents:
    - http://localhost:8081
  liveness_probe_enabled: true # default: true
liveness_probe_interval: 30 # seconds, default: 30| Setting | Default | Environment variable | Description |
|---|---|---|---|
liveness_probe_enabled | true | INFER_A2A_LIVENESS_PROBE_ENABLED | Enable recurring liveness probes. Set false for one-shot checks |
liveness_probe_interval | 30 | INFER_A2A_LIVENESS_PROBE_INTERVAL | Interval in seconds between probes |
Setting liveness_probe_enabled: false restores the old behavior where agents are checked only once at startup.
Parallel Tool Execution
Execute up to 5 tools concurrently for improved performance.
Configuration:
agent:
  max_concurrent_tools: 5 # Default: 5
Benefits:
- Faster multi-file operations
- Concurrent web fetches
- Parallel code searches
- Reduced total execution time
Workflows
Bug Investigation and Fix
infer chat
# Shift+Tab to Plan Mode
> "Analyze bug in issue #123 and create fix plan"

# Shift+Tab to Standard Mode
> "Implement the fix according to the plan"

# Test and commit
> "Run test suite to verify"
> "/git commit"
Feature Development
infer chat
> "Read CONTRIBUTING.md and understand project structure"

# Shift+Tab to Plan Mode
> "Design implementation for user profile feature with avatar upload"

# Shift+Tab twice to Auto-Accept Mode
> "Implement the user profile feature according to the plan"

# Shift+Tab to Standard Mode
> "Review changes and run all tests"
Code Review and Refactoring
infer chat
# Plan Mode for analysis
> "Review authentication module for security issues and code quality"

# Standard Mode for implementation
> "Refactor based on recommendations, prioritize security issues"
GitHub Issue Resolution
infer headless "Fix the bug described in GitHub issue #456"

# Agent autonomously:
# 1. Fetches issue details
# 2. Analyzes relevant code
# 3. Implements fix
# 4. Runs tests
# 5. Creates commit referencing issue
Best Practices
For Beginners
- Start with Plan Mode for unfamiliar code
- Always work in git repositories
- Review diff visualizations before approving
- Begin with simple tasks
For Power Users
- Use Auto-Accept for trusted, repetitive tasks
- Create custom shortcuts for frequent commands
- Combine with scripts for automation
- Leverage A2A for specialized workflows
Performance Tips
- Be specific with file paths and function names
- Use Grep to narrow down relevant files first
- Break large tasks into smaller subtasks
- Provide context with references
Safety
- Review diffs before approving modifications
- Run tests after significant changes
- Have backups before extensive Auto-Accept usage
- Allow-list only trusted commands
- Add sensitive paths to
filesystem.deniedin~/.infer/sandbox.yaml
Security
Command allow-listing
The Bash tool is default-deny: a command auto-runs only when it matches the per-mode allowed-list for the active agent mode. The effective list is mode.all.allow (the every-mode baseline) unioned with the active mode's own entries:
# ~/.infer/tools.yaml
tools:
  bash:
    mode:
      all:
        allow:
          - ls( .*)?
          - pwd( .*)?
          - tree( .*)?
          - git status( .*)?
          - git diff( .*)?
          - npm (install|test|run).*
      auto:
        allow:
          - .* # unrestricted - Auto-Accept mode only
Read-only gh operations are in the baseline so the agent can inspect GitHub out of the box; writes (gh issue/pr create|edit|comment) and destructive operations (for example gh pr merge, gh repo delete) are not - they fall through to approval. See Default gh allowed-list for the full list.
Entries match the whole command, and a clean-command guard rejects command substitution, multi-command chains/pipelines, file-write redirects, dangerous find actions, and environment-variable leaks before matching. The only thing that lifts the guard is the .* sentinel (Auto-Accept mode).
File sandbox
Which paths the file tools may read and write is decided by a userspace policy file, ~/.infer/sandbox.yaml - not by config.yaml. It holds one section per resource, today filesystem with two lists:
filesystem:
  allowed: # the sandbox. Outside it the user is asked. First match wins.
    - .
    - /tmp
    - path: vendor/
      access: read # read | write (default write). A write here asks.
  denied: # always wins over allowed, a blocking entry over one that asks
    - path: .infer/
      on_violation: approval # block | approval (default block)
    - .git/
    - '*.env'
infer init seeds the file with the defaults.
Entry forms
Each entry is either a path string or a map:
| List | Map key | Values | Meaning |
|---|---|---|---|
allowed | access | read, write (default) | A write into a read entry asks the user |
denied | on_violation | block (default), approval | block fails outright, approval asks the user |
Paths are either anchored (/abs, ~/x, ., ./x - matched at that location) or patterns matched at any depth (dir/, *.glob, name).
Defaults
allowed:.and/tmp.denied:.infer/(withon_violation: approval),.git/,*.env,.environment,auth.yaml,*.key,*.pem,id_rsa,id_dsa,id_ecdsa,id_ed25519.
The config dirs (.infer/ and ~/.infer/) therefore ask before every read and write, since their files can hold tokens - including auth.yaml. Built-in carve-outs keep the agent's own working surface open without a prompt: skills, plans, plugins, memory, the artifacts directory and runtime output such as the media root.
Read-only library carve-outs. Dependency sources are readable without configuration, so the agent can inspect the libraries a project builds against:
| Language | Directories |
|---|---|
| Go | $GOMODCACHE (or $GOPATH/pkg/mod) and $GOROOT/src |
| Rust | $CARGO_HOME/registry/src and $CARGO_HOME/git/checkouts (default ~/.cargo), plus $RUSTUP_HOME/toolchains/*/lib/rustlib/src (default ~/.rustup) |
Writes under these directories stay denied - the carve-out is read-only, so the agent cannot edit a vendored dependency in place.
Decision order
deniedfirst. A blocking entry fails whatever its position; otherwise the first matching approval entry asks the user.- Built-in carve-outs, which skip the default
.infer/denial. - The first matching
allowedentry - a write into areadentry asks. - Otherwise the user is asked. An empty
allowedlist is no boundary.
Loading
- Only
~/.infer/sandbox.yamlis read. A project.infer/sandbox.yamlis ignored, so a checked-out repository cannot widen your sandbox, and the agent's file tools can never write the policy file - the same guard covers~/.infer/tools.yaml. - The file loads over the defaults: a list it leaves out keeps its default.
- A file that fails to parse or validate stops
inferfrom starting, rather than falling back to a wider policy. infer config setdoes not reach the sandbox - edit the file.
Grants
When the user approves a denied path, the grant lasts for the session. Answering "always" persists it into sandbox.yaml, except for paths matched by a denied entry, which stay session-only - denied wins over any allowed entry an "always" could write.
Environment and daemon overrides
INFER_TOOLS_SANDBOX_DIRECTORIES (and the daemon's per-thread sandbox_directories thread option) adds directories to filesystem.allowed instead of replacing the list.
export INFER_TOOLS_SANDBOX_DIRECTORIES="/work/project,/tmp/scratch"Approval Workflow
Tool approval has two independent layers - whether an action needs approval, and how that approval is delivered:
- Whether -
safety.require_approval(with per-tool overrides liketools.bash.require_approval/tools.write.require_approval, and for Bash the per-mode allowed-list). - How -
safety.approval_behaviour, one of:
approval_behaviour | How a needed approval is delivered |
|---|---|
prompt (default) | Prompt in the chat TUI; under a channel manager, deliver over IPC; otherwise block. |
ipc | Deliver over IPC when a broker is attached (e.g. the channel manager); otherwise block. |
judge | One LLM judge call decides. Always reachable - never downgraded to block. |
block | Always reject an approval-requiring action with a reason - never prompt. |
Both layers live in ~/.infer/tools.yaml, not config.yaml:
# ~/.infer/tools.yaml
safety:
  require_approval: true
  approval_behaviour: prompt
judgeis the only behavior that requires a resolvable judge model - config validation fails at startup when neitherjudge.model(injudge.yaml) noragent.modelis set. Theauto-with-judgemode is validated separately by the headless runner at start (--mode/INFER_AGENT_MODE).
LLMs request approval before executing Write/Edit/Delete/Bash operations, with a colored, syntax-aware diff preview for file edits.
A batch waits for every prompt
When a model requests several tools at once and any call in that batch is gated, no call of the batch runs until the last prompt is answered. That includes the calls that need no approval - a Read or TodoWrite batched with a gated Write - and a background job in the same batch. The cost is that a long first tool does not start while you are still deciding on the rest. Once the round is decided the cleared calls run as before: overlapping, bounded by the same concurrency limit, with results flushed in tool-call order.
Rejecting a later call does not undo an earlier approval - the call you approved still runs. A call you approved in a round that never completes (a failed approval, an interrupted session) does not run at all, and no longer lingers in the chat as approved. The status line reads Tool approved: <tool> while the next prompt is open, rather than claiming the tool is already executing.
A single gated call, auto-accept mode and fully ungated batches behave as before. Prompts a tool opens during execution are unaffected: sandbox access grants, RequestApproval escalations and AskUserQuestion can still interrupt a running call.
Headless secure-by-default
infer headless runs in standard mode, so an off-list or mutating action is not auto-run. With no approver reachable (CI, heartbeat) it is blocked with a reason; under a channel manager (--require-approval) it is sent for IPC approval (for example a Telegram confirmation). There is no .* default - full autonomy is an explicit opt-in (a curated allowed-list, the append override, or mode.auto / .*). To keep a gate without a human, run --mode auto-with-judge (or set approval_behaviour: judge) and let an LLM judge answer instead of blocking.
For a CI agent that should edit files and run a curated command set with no interactive approver, use the controlled-autonomy profile - block everything that would need approval, but let the agent write files and run a vetted allowed-list:
# ~/.infer/tools.yaml
safety:
  approval_behaviour: block # reject anything that would otherwise prompt
tools:
  write:
    require_approval: false # ...but let the agent write/edit files freely
  bash:
    mode:
      all:
        allow: # curate exactly what may run unattended
          - git status( .*)?
          - git add( .*)?
          - go (build|test)( .*)?
Add a couple more commands without touching config via INFER_TOOLS_BASH_ALLOW_APPEND="git commit,git push".
Troubleshooting
Connection Issues
# Check configuration
infer config get

# Verify gateway status
infer status

# Debug logging (logging.debug)
INFER_LOGGING_DEBUG=true infer chat
Permission Issues
# Check configuration directory
ls -la ~/.infer/

# Recreate config.yaml from defaults
infer config init --overwrite

# Re-initialize the project
infer init
Tool Execution Problems
# Inspect tool configuration
infer config get tools

# Check whether a bash command is allowed (without running it)
# Exits non-zero with the reason on stderr when it is not
infer tools validate "git status"

# Enable debug logging
export INFER_LOGGING_DEBUG=true
infer headless "your task"
Computer Use Issues
# Verify display server
echo $DISPLAY  # Linux/X11

# Check permissions (macOS) - required before the accessibility tree returns elements
# System Settings > Privacy & Security > Accessibility

# Test screenshot
infer chat
> "Take a screenshot and describe what you see"
If Computer with action: accessibility returns an empty tree or screenshot fallback guidance on macOS, the Accessibility permission for infer is the first thing to check. On Linux and Windows that fallback is expected - the accessibility providers are not implemented there yet.
Shell Completions Not Working
# Confirm the completion script generates
infer completion zsh | head

# Zsh: the file must live on a directory in $fpath and be named _infer,
# then start a fresh shell
infer completion zsh > "${fpath[1]}/_infer" && exec zsh

# Bash: source the generated file (or place it under a bash-completion dir)
source <(infer completion bash)
If completions still do not appear, the shell rc is usually not sourcing the completion file. Verify compinit is called for zsh (or bash-completion is installed for bash), confirm the file path is on $fpath/a bash-completion directory, then start a fresh shell.
Command Reference
| Command | Description |
|---|---|
infer init | Seed the userspace baseline in ~/.infer/ |
infer env | Write a .env.example with every provider API key |
infer status | Check gateway health and resource usage - --format json|yaml for machine-readable output (Gateway Status) |
infer chat | Interactive chat session (TUI) |
infer chat --web | Web-based terminal interface |
infer headless <task> | Autonomous task execution |
infer skills <subcommand> | Manage Agent Skills (list, search, install, uninstall) |
infer plugins <subcommand> | Manage Claude Code-format plugins (install, list, enable, disable, update, remove) |
infer daemon | Start the daemon - scheduler, channel listener, and heartbeat (Channels) |
infer daemon stop <id> | Stop a session's agent and delete the remote runtime it ran on, including one it already came home from (Workspace lifecycle and cleanup) |
infer config <subcommand> | Configuration management (init, get, set) |
infer tools <subcommand> | Run agent tools directly (execute, validate) |
infer agents <subcommand> | A2A agent management |
infer binaries <subcommand> | Manage the helper binaries under ~/.infer/bin/ (gateway, ffmpeg, whisper-cli, llama-tts) - status [name...] reports each one as missing, stale or current by sha256 (approval-free), install [name...] installs or upgrades it (--version <tag> pins a release) |
infer conversations <subcommand> | Conversation history management (list, show, delete) |
infer conversation-title | Generate AI titles for saved conversations, or run it as a daemon |
infer export <session-id> | Export a conversation to Markdown under the project's exports/ directory |
infer stats | Summarize local telemetry - token usage, tool outcomes, and cost |
infer traces | Render a session's trace span tree (Telemetry) |
infer insights [since] | Analyze past sessions for repeatable workflows and recurring failures |
infer reset / infer reset confirm | Preview, then wipe local runtime state (Reset Shortcut) |
infer avatars <subcommand> | Avatar library management (list, create, delete) for TextToVideo renders |
infer completion <shell> | Generate a shell completion script (bash, zsh, fish, powershell) |
infer version | Show version information (backwards-compatible subcommand) |
infer --version | Show version information (styled by fang) |
infer --help | Display styled help information |
Global Flags
Available on every command:
| Flag | Description |
|---|---|
-v, --verbose | Enable verbose output |
--no-colors | Disable ANSI colors (also auto-disabled when stdout is not a terminal or NO_COLOR is set) |
--tools-bash-allow-append <cmds> | Comma/newline-separated commands added to the bash allow-list in every mode; INFER_TOOLS_BASH_ALLOW_APPEND takes precedence |
--reminders-file <path> | Reminders YAML path, overriding project .infer/ and ~/.infer/ reminders; INFER_REMINDERS_CONFIG takes precedence |
For per-command flags and examples, see the CLI repository's Commands Reference.
Support and Resources
- Repository: github.com/inference-gateway/cli
- Releases: GitHub Releases
Canonical CLI references
This page mirrors the CLI repository's documentation; these pages are the source of truth for each topic:
| Topic | Reference |
|---|---|
| Installation | installation.md |
| Commands and global flags | commands-reference.md |
| Tools and tool overview | tools-reference.md |
| Configuration | configuration-reference.md |
| Tool approval | tool-approval.md |
| Cost tracking | cost-tracking.md |
| Computer use | computer-use.md |
| Web terminal | web-terminal.md |
| Frame sources and vision | vision.md |
| Persistent memory | memory.md |
| Reminders and command hooks | hooks.md |
| Plugins | plugins.md |
| Runnable examples | examples.md |
The CLI is actively developed with regular updates and new features. Check the repository for the latest releases and announcements.